

You want to sample OpenTelemetry traces without losing the ones you will need at 3 AM: the errors and the slow requests. A ratio sampler in the SDK cannot promise that, because it decides before the request finishes. Collector tail sampling can, at the price of memory and routing rules. Filtering, span metrics and ingestion-side drop rules each cover a different part of the problem.
This guide compares the options by what each one keeps (errors, slow traces, percentiles), then walks through collector configs for sampling, filtering and enrichment. The configs follow the current tail sampling processor and filter processor READMEs. Check the README for the collector version you run before you copy anything.
What each volume-control option keeps
| Option | Where it decides | Errors | Slow traces | Percentiles |
|---|---|---|---|---|
| Head sampling (SDK ratio) | Trace start, from the trace ID | Kept at the sampling ratio only | Kept at the sampling ratio only | Distribution shape holds, with fewer samples |
| Tail sampling (collector) | After the trace is collected | Kept by a status_code policy | Kept by a latency policy | Skewed high if computed from kept traces |
| Filter processor | Per span, in the pipeline | Dropped if your condition matches | Dropped if your condition matches | Lost for dropped spans |
| Span metrics connector | Before sampling | Counted in metrics | Counted in histogram buckets | Computed over all spans it sees |
| Last9 Drop rules | At ingestion, on attributes | Dropped if the rule matches | Dropped if the rule matches | Lost for dropped data |
Span metrics do not reduce trace volume. They protect the numbers you alert on while the other options reduce volume. The rest of this post expands each row.
Sampling strategies in OpenTelemetry
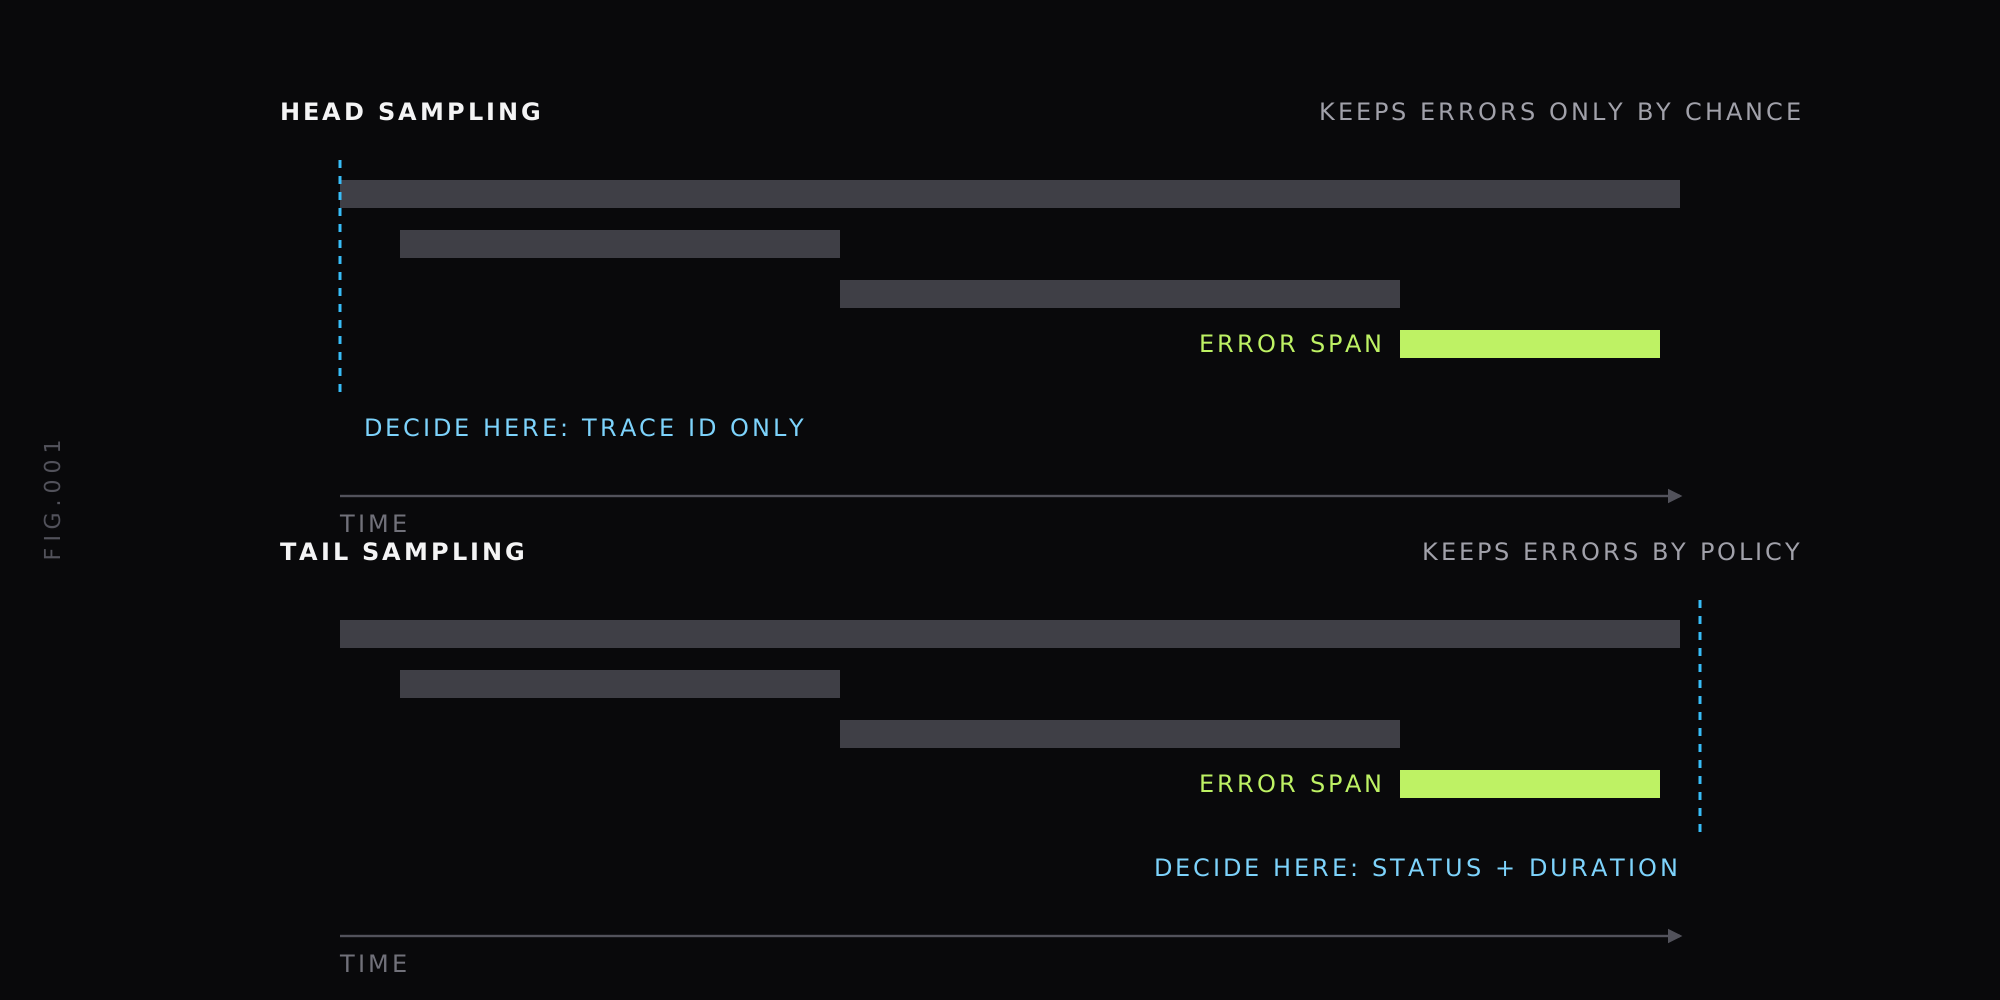
The OpenTelemetry sampling docs split sampling into head and tail. The difference is when the decision is made and what data it can see.
Head sampling
Head sampling makes the decision as early as possible, usually from the trace ID and a target percentage. It is easy to configure and cheap to run. Its documented downside is that it cannot use data from the whole trace, so it cannot guarantee that every trace with an error is kept.
Most SDKs read the sampler from environment variables. Wrapping the ratio sampler in a parent-based sampler makes downstream services follow the decision made at the root:
export OTEL_TRACES_SAMPLER="parentbased_traceidratio"export OTEL_TRACES_SAMPLER_ARG="0.25" # keep 25% of tracesIn Go, the same thing in code:
import sdktrace "go.opentelemetry.io/otel/sdk/trace"
tp := sdktrace.NewTracerProvider(    sdktrace.WithSampler(        sdktrace.ParentBased(sdktrace.TraceIDRatioBased(0.25)),    ),)
Services that sample independently can still produce fragmented traces. Consistent probability sampling addresses that by carrying the decision in tracestate.
“Probabilistic” and “ratio” sampling are not a separate third strategy. They describe how a head or tail sampler picks traces: a fixed percentage chosen by hashing the trace ID.
Tail sampling
Tail sampling decides after it has seen all or most of the spans in a trace. That is the only way to say “keep every trace with an error” or “keep every trace slower than two seconds”. In the collector, the tail_sampling processor does this with a list of policies. A trace is sampled when a policy returns a sample decision.
processors: tail_sampling: decision_wait: 10s num_traces: 50000 expected_new_traces_per_sec: 1000 decision_cache: sampled_cache_size: 100000 non_sampled_cache_size: 100000 policies: - name: keep-errors type: status_code status_code: { status_codes: [ERROR] } - name: keep-slow type: latency latency: { threshold_ms: 2000 } - name: baseline type: probabilistic probabilistic: { sampling_percentage: 10 }This keeps every trace with an ERROR status, every trace longer than 2,000 ms, and 10% of everything else. The latency policy measures from the earliest span start to the latest span end, and with no upper bound it samples anything above threshold_ms.
Three settings deserve attention:
decision_wait(default 30s) is how long the processor holds a trace before deciding. Set it longer than your slowest legitimate trace, or late spans arrive after the decision.num_traces(default 50,000) is how many traces stay in memory. If the collector holds more than this, traces are dropped before they are sampled and thesampling_trace_dropped_too_earlymetric rises.decision_cacheremembers trace IDs after their spans leave memory, so spans that arrive late follow the earlier decision. The README suggests sizing it well abovenum_traces.
The default of 50,000 is a starting point. Measure held traces against your traffic and raise it if traces drop early.
Tail sampling needs routing
The processor keeps spans in memory while it waits, so every span of a trace must reach the same collector instance. With more than one sampling collector, put a first layer in front that routes by trace ID using the load balancing exporter:
# Layer 1: agents or a routing tierexporters:  load_balancing:    routing_key: "traceID"    protocol:      otlp:        tls:          insecure: true    resolver:      dns:        hostname: otelcol-sampling-headless.observability.svc.cluster.local
service:  pipelines:    traces:      receivers: [otlp]      processors: [memory_limiter, batch]      exporters: [load_balancing]
Layer 2 is a pool of collectors running tail_sampling. The README recommends separating the layers for failure isolation instead of running both pipelines on one instance. The exporter was renamed from loadbalancing to load_balancing in recent releases, and the old name still works as a deprecated alias. For the operational side of running a pool, see how to scale the OpenTelemetry Collector.
If you want a standalone sampler instead of collector config, Honeycomb’s open source Refinery is a tail-based sampling proxy. Its README describes rules-based sampling, such as keeping all traces with an error, and dynamic sampling for the rest.
Keep percentiles accurate under sampling
Tail sampling that keeps every slow trace and few fast ones changes the population you are measuring. A P99 computed from the kept traces measures the sampler’s selection, not your traffic, and it will read higher than the real value. The same applies to error rates computed from kept traces.
The fix is to compute latency and error metrics before sampling, from every span, and sample only the traces you store. The span metrics connector does this: it aggregates request, error and duration (R.E.D) metrics from spans. Put it where all spans pass, typically the first layer, and keep the metrics pipeline separate from the sampling decision.
connectors:  span_metrics:    histogram:      explicit:        buckets: [100ms, 250ms, 500ms, 1s, 2s, 5s]    dimensions:      - name: http.method      - name: http.status_code
service:  pipelines:    traces:      receivers: [otlp]      processors: [memory_limiter]      exporters: [load_balancing, span_metrics]    metrics:      receivers: [span_metrics]      processors: [batch]      exporters: [otlp]
Percentiles from histogram buckets are estimates bounded by your bucket edges, so choose edges around your SLO thresholds. The README’s note on the Single Writer Principle matters when several collectors run the connector: each instance must produce a distinct metric stream. The component was renamed from spanmetrics to span_metrics as well. Our walkthrough on converting traces to metrics with SpanMetrics covers setup, and why percentiles are often computed wrong explains what happens when you average or downsample them.
Filtering telemetry data
Filtering drops telemetry you never want, such as health checks and debug logs. Do it as close to the source as you can. In Python, OTEL_PYTHON_EXCLUDED_URLS removes endpoints at instrumentation time, which we cover in excluding health checks from Python OTel traces.
In the collector, the filter processor now takes OTTL conditions per signal. Telemetry is dropped when a condition is true, and conditions in a list are combined with OR:
processors: filter/noise: error_mode: ignore trace_conditions: - IsMatch(span.attributes["http.route"], ".*/(health|ready|live).*") metric_conditions: - metric.name == "go_gc_duration_seconds" log_conditions: - log.severity_number < SEVERITY_NUMBER_INFOThis replaces the include and exclude blocks with match_type that older versions of this post used. Attribute names vary by instrumentation (http.route, url.path, http.target), so check what your spans carry. Drop only spans whose whole trace is noise. Removing one span from the middle of a real trace leaves its children orphaned.
For metrics, filtering by labels in the Collector goes deeper.
Volume control in Last9
Last9 handles volume at the ingestion layer, so changes do not need a redeploy. The Drop page documents rules for metrics, logs and traces:
- Metrics are matched by metric name. Logs and traces are matched by attributes and resource attributes.
- Multiple filters in one rule combine with AND, and the operators are
==,!=and=~. - A preview button shows matching data before you save, and rules take 1-2 minutes to take effect.
- Dropped data is not ingested and cannot be recovered. Deleting a rule resumes ingestion of data that arrives afterwards.
The documented examples include dropping health check traces with attributes["http.route"] =~ .*/health.*. Drop rules match on attributes, so they are a good fit for known noise. The docs do not describe a rule that keeps errors and slow traces while sampling the rest, and they do not describe tail-based sampling at ingest. If you need that behavior, run tail_sampling in your collector tier as above.
For the numbers you alert on, Streaming Aggregation includes TraceMetrics, which turns traces into latency, error and throughput metrics without querying raw spans. Check the pipeline-order diagram on that page when you combine Drop rules with TraceMetrics, so you know whether the spans you drop still count in the metric.
The Storage docs state that Last9 applies no sampling on your data. Anything you sample or drop, you do upstream or with a Drop rule.
While OpenTelemetry is the preferred choice today, understanding its roots in OpenTracing is essential. Learn about the differences and migration steps in our in-depth comparison.
Data enrichment techniques
Enrichment adds context so the traces you keep are worth keeping. Do it once, close to the source, and keep the attributes low in cardinality.
Resource attributes from the environment
Set shared attributes with environment variables so every language SDK picks them up:
export OTEL_SERVICE_NAME="checkout"export OTEL_RESOURCE_ATTRIBUTES="deployment.environment=production,service.version=1.8.2"If both are set, OTEL_SERVICE_NAME takes precedence over service.name in OTEL_RESOURCE_ATTRIBUTES. In code, the Python SDK equivalent:
import osfrom opentelemetry import tracefrom opentelemetry.sdk.resources import Resourcefrom opentelemetry.sdk.trace import TracerProvider
resource = Resource(attributes={    "service.name": "my-service",    "deployment.environment": os.getenv("DEPLOYMENT_ENV", "unknown"),})
trace.set_tracer_provider(TracerProvider(resource=resource))
Data from external sources
When the context lives outside the telemetry, such as a customer tier in another system, you can write a custom processor. This sketch shows the core loop. You still need to supply fetchExternalData and register the processor with a factory:
func (e *ExternalEnricher) ProcessTraces(ctx context.Context, td ptrace.Traces) (ptrace.Traces, error) { for i := 0; i < td.ResourceSpans().Len(); i++ { rs := td.ResourceSpans().At(i) externalData := fetchExternalData(rs.Resource().Attributes()) rs.Resource().Attributes().PutStr("external.data", externalData) } return td, nil}Learn how to effectively instrument your Golang application for comprehensive observability, capturing valuable metrics and traces.
Advanced processor configurations
Beyond sampling and filtering, the collector has processors for reshaping data. The OpenTelemetry Collector guide explains how they fit together. Here are three that matter for volume and privacy.
Attributes processor
processors: attributes: actions: - key: db.statement action: delete - key: credit_card action: hash - key: email action: extract pattern: "^(?P<username>[^@]+)@"This deletes the db.statement attribute, hashes the credit_card attribute, and extracts the part of email before the @ into a new username attribute. The extract action needs named groups in the pattern, and it overwrites an existing attribute of the same name. Extracting leaves the original email in place, so add a delete action for it if the address must not leave your network.
Resource processor
processors: resource: attributes: - key: cloud.availability_zone value: zone-1 action: upsert - key: k8s.cluster.name from_attribute: k8s.cluster action: insertThis sets a cloud availability zone on all telemetry and copies the Kubernetes cluster name from another attribute when k8s.cluster.name does not already exist.
Span processor
processors: span: name: to_attributes: rules: - ^\/api\/v1\/(?P<tenant>[^\/]+)\/(?P<resource>[^\/]+) include: match_type: regexp attributes: - key: http.url value: .*This pulls the tenant and resource out of the span name into attributes and rewrites the name with placeholders. Rules must use named subexpressions, because each name becomes an attribute. The include block restricts processing to spans that have an http.url attribute.
Pipeline order and performance
Order matters because each processor sees what the one before it emits. The collector’s processor documentation recommends this order:
memory_limiterfirst, so it can shed load before downstream processors accumulate data.- Sampling and filtering processors that drop data, so you do not process what you will discard.
- Processors that rely on request context, such as
k8sattributes, before batching, because batching clears the context. - Processors that transform or enrich, such as
attributesandtransform. batchlast.
The memory limiter README recommends setting GOMEMLIMIT to 80% of the collector’s hard memory limit, and starting spike_limit_mib at about 20% of the hard limit. Tail sampling raises memory use because spans wait in memory, so these settings matter more on the sampling tier.
Rate limiting belongs inside the sampler too: rate_limiting is a policy type in tail_sampling, with a spans_per_second setting, not a separate processor.
A complete sampling collector
Here is one gateway collector for a high-traffic e-commerce platform. It drops health checks, keeps all errors and slow traces, keeps 10% of the rest, enriches what it keeps, and batches last:
receivers:  otlp:    protocols:      grpc:        endpoint: 0.0.0.0:4317
processors:  memory_limiter:    check_interval: 1s    limit_mib: 3200    spike_limit_mib: 640  filter/noise:    error_mode: ignore    trace_conditions:      - IsMatch(span.attributes["http.route"], ".*/(health|ready|live).*")  tail_sampling:    decision_wait: 10s    num_traces: 50000    expected_new_traces_per_sec: 1000    decision_cache:      sampled_cache_size: 100000      non_sampled_cache_size: 100000    policies:      - name: keep-errors        type: status_code        status_code: { status_codes: [ERROR] }      - name: keep-slow        type: latency        latency: { threshold_ms: 2000 }      - name: baseline        type: probabilistic        probabilistic: { sampling_percentage: 10 }  resource:    attributes:      - key: deployment.environment        value: production        action: upsert  batch:    timeout: 1s    send_batch_size: 1024
exporters:  otlp:    endpoint: backend.example.com:4317    sending_queue:      enabled: true      num_consumers: 10      queue_size: 5000    retry_on_failure:      enabled: true      initial_interval: 5s      max_interval: 30s      max_elapsed_time: 300s
service:  pipelines:    traces:      receivers: [otlp]      processors: [memory_limiter, filter/noise, tail_sampling, resource, batch]      exporters: [otlp]
The limit_mib of 3200 is an example for a 4 GiB container, not a recommendation. Size it for your own deployment. Replace the backend.example.com endpoint and add authentication headers from your backend’s setup instructions.
Before you roll this out, run through a short checklist:
- Errors, slow traces and percentiles each have a named mechanism: a
status_codepolicy, alatencypolicy and a span metrics connector. - Every span of a trace reaches the same sampling collector.
num_traces,decision_waitanddecision_cacheare sized from observed traffic, and you alert onsampling_trace_dropped_too_early.- You tested the policy on staging traffic and compared kept traces against a known set of failures.
- Anything you drop with a filter or a Last9 Drop rule is disposable, because dropped data cannot be recovered.
FAQ
How do I sample OpenTelemetry traces but keep all errors?
Use tail sampling. In the collector’s tail_sampling processor, add a status_code policy for ERROR, a latency policy for slow traces and a probabilistic policy for the baseline. A trace is kept when any policy says sample. Head sampling in the SDK cannot do this because it decides before the outcome is known.
What is the difference between head and tail sampling?
Head sampling decides at the start of a trace, usually from the trace ID and a ratio, so it is cheap but blind to errors and latency. Tail sampling decides after the spans of a trace have been collected, so it can keep errors and slow traces, at the cost of holding spans in memory and routing every span of a trace to one collector.
Does sampling make P99 latency inaccurate?
It can. If a tail sampler keeps every slow trace and only a fraction of fast ones, percentiles computed from the kept traces skew high. Compute latency histograms with a span metrics connector before sampling, then sample the traces you store.
Can I use OpenTelemetry tail sampling at high volume?
Yes, with a two-tier layout. The processor holds spans in memory and needs every span of a trace on the same collector, so agents route by trace ID with the load balancing exporter to a pool of sampling collectors. Size num_traces and decision_wait for your traffic and watch the sampling_trace_dropped_too_early metric.
Does Last9 sample my telemetry?
Last9 documents that it applies no sampling on your data. You can drop telemetry at ingestion with Drop rules, which match attributes and are irreversible for data already dropped, or turn traces into metrics with Streaming Aggregation. The documentation does not describe tail-based sampling at ingest.
More resources
- OpenTelemetry sampling concepts
- Tail sampling processor README
- OpenTelemetry Collector configuration
- What is OpenTelemetry?
- OpenTelemetry Registry for related tools and libraries


