This is the full developer documentation for Last9
# Introduction
> Last9 is an observability platform for logs, metrics, and traces. Built on OpenTelemetry and Prometheus with high-cardinality storage, alerting, and SLOs.
New to Last9? Read [What is Last9?](/docs/introduction/) for a product overview, or jump to the [Quick Start Guide](/docs/onboard/) to send your first telemetry data. This documentation covers ingestion via OpenTelemetry and Prometheus, the Control Plane, alerting and SLOs, log and trace exploration, dashboards, and the Last9 MCP server for AI agents.
## [Getting Started](/docs/introduction/)
[Understand what Last9 is and how to quickly start sending data](/docs/introduction/)
## [Control Plane](/docs/control-plane/)
[Manage your telemetry data, its configurations, and its lifecycle](/docs/control-plane/)
## [Discover](/docs/discover-services/)
[Auto-discover and monitor services, background jobs, infra and more with OpenTelemetry](/docs/discover-services/)
## [Logs](/docs/logs/)
[Explore your logs data, its details, and related telemetry](/docs/logs/)
## [Traces](/docs/traces/)
[Explore your trace spans, its dependencies and timeline charts, and span details](/docs/traces/)
## [Real User Monitoring](/docs/discover-applications/)
[Monitor your web application's performance from your users' perspective](/docs/discover-applications/)
## [Alerting](/docs/alerting/)
[Create threshold alerts for metrics and logs, or detect metric anomalies with Adaptive Alerting](/docs/alerting/)
## [Instrumentation](/docs/integrations/)
[Send data via OpenTelemetry, Prometheus, AWS Cloudwatch, and more](/docs/integrations/)
## [SLOs](/docs/slos/)
[Monitor and manage your service reliability with SLOs and SLIs](/docs/slos/)
## [Tutorials](/docs/howto/)
[Common how-tos for Prometheus, Kubernetes, VictoriaMetrics, etc.](/docs/howto/)
## [FAQs](/docs/faqs/)
[Frequently asked questions about Last9 — what, why, how](/docs/faqs/)
## Other Resources
## [Changelog](https://last9.io/changelog/)
## [Blog](https://last9.io/blog/)
## [Community](https://discord.com/invite/Q3p2EEucx9/)
## [X / Twitter](https://x.com/last9io/)
## [Youtube](https://youtube.com/@last9/)
# Access Policies
> Leverage Last9's access policies to perform traffic shaping of time series data in real-time.
Last9 supports automatic data tiering of the metrics based on retention policies. These data tiers have different retention policies. E.g., Blaze Tier stores data for the last two hours, whereas Hot Tier stores data for the last six months. Depending on the use case, the tiers are designed to access their metrics from a fast or slow tier.
It is extremely crucial to ensure that traffic for real-time alerting is always prioritized and served from the fastest Blaze tier. The Grafana queries can be served from the Hot tier without conflicting with alerting. Access Policies ensure that one can create these policy guardrails to ensure the metrics data is accessible from a specific tier based on its purpose.
Note
Access Policies are specific to a Last9 cluster. Different clusters can have different Access Policies.
Each Access Policy is associated with a Token created for a Tier. Tokens allow ACL for time series data by providing a way to access data from specific tiers for either `read` `write` or both operations.
## Setting up Tokens
To achieve this, create a read token first from Settings -> Tokens.
[Creating a Read Token in Levitate](https://www.youtube.com/embed/qfdUYwAMZvw)
## Creating Access Policy
Once the Token is created, one can create an Access Policies from Settings -> Policies.
[Creating Access Policy in Levitate](https://www.youtube.com/embed/0j_N9CKyigY)
That’s it, you don’t have to change anything more. Just use the token associated with the Alerting policy to configure alertmanager and the token associated with the visualization policy to [configure Grafana](/docs/grafana-config/).
Last9 will take care of performing traffic shaping in real-time.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Acknowledge Alerts
> Record who owns a firing alert in the Last9 Alert Monitor. Acknowledge an alert, Acknowledge & mute it, reassign it, or release it.
An alert shows its state, but it does not show who responds to it. Acknowledge an alert to become its owner. The [Alert Monitor](/docs/alert-monitor/) then shows your name on the alert, so your team knows who responds to it.
Acknowledgement is available on every firing alert rule in the Alert Monitor.
An acknowledgement does not stop the notifications
An acknowledgement records the owner. It does not stop the notifications to your [Notification Channels](/docs/notification-channels/), and the alert continues to notify as configured. To stop the notifications too, use **Acknowledge & mute**, which mutes the alert rule with the same action.
## Acknowledge an Alert
You can acknowledge an alert from two places:
* **The alert row** — open the actions menu at the end of the row, then select **Acknowledge**.
* **The alert details view** — select the **Acknowledge** chip in the header.
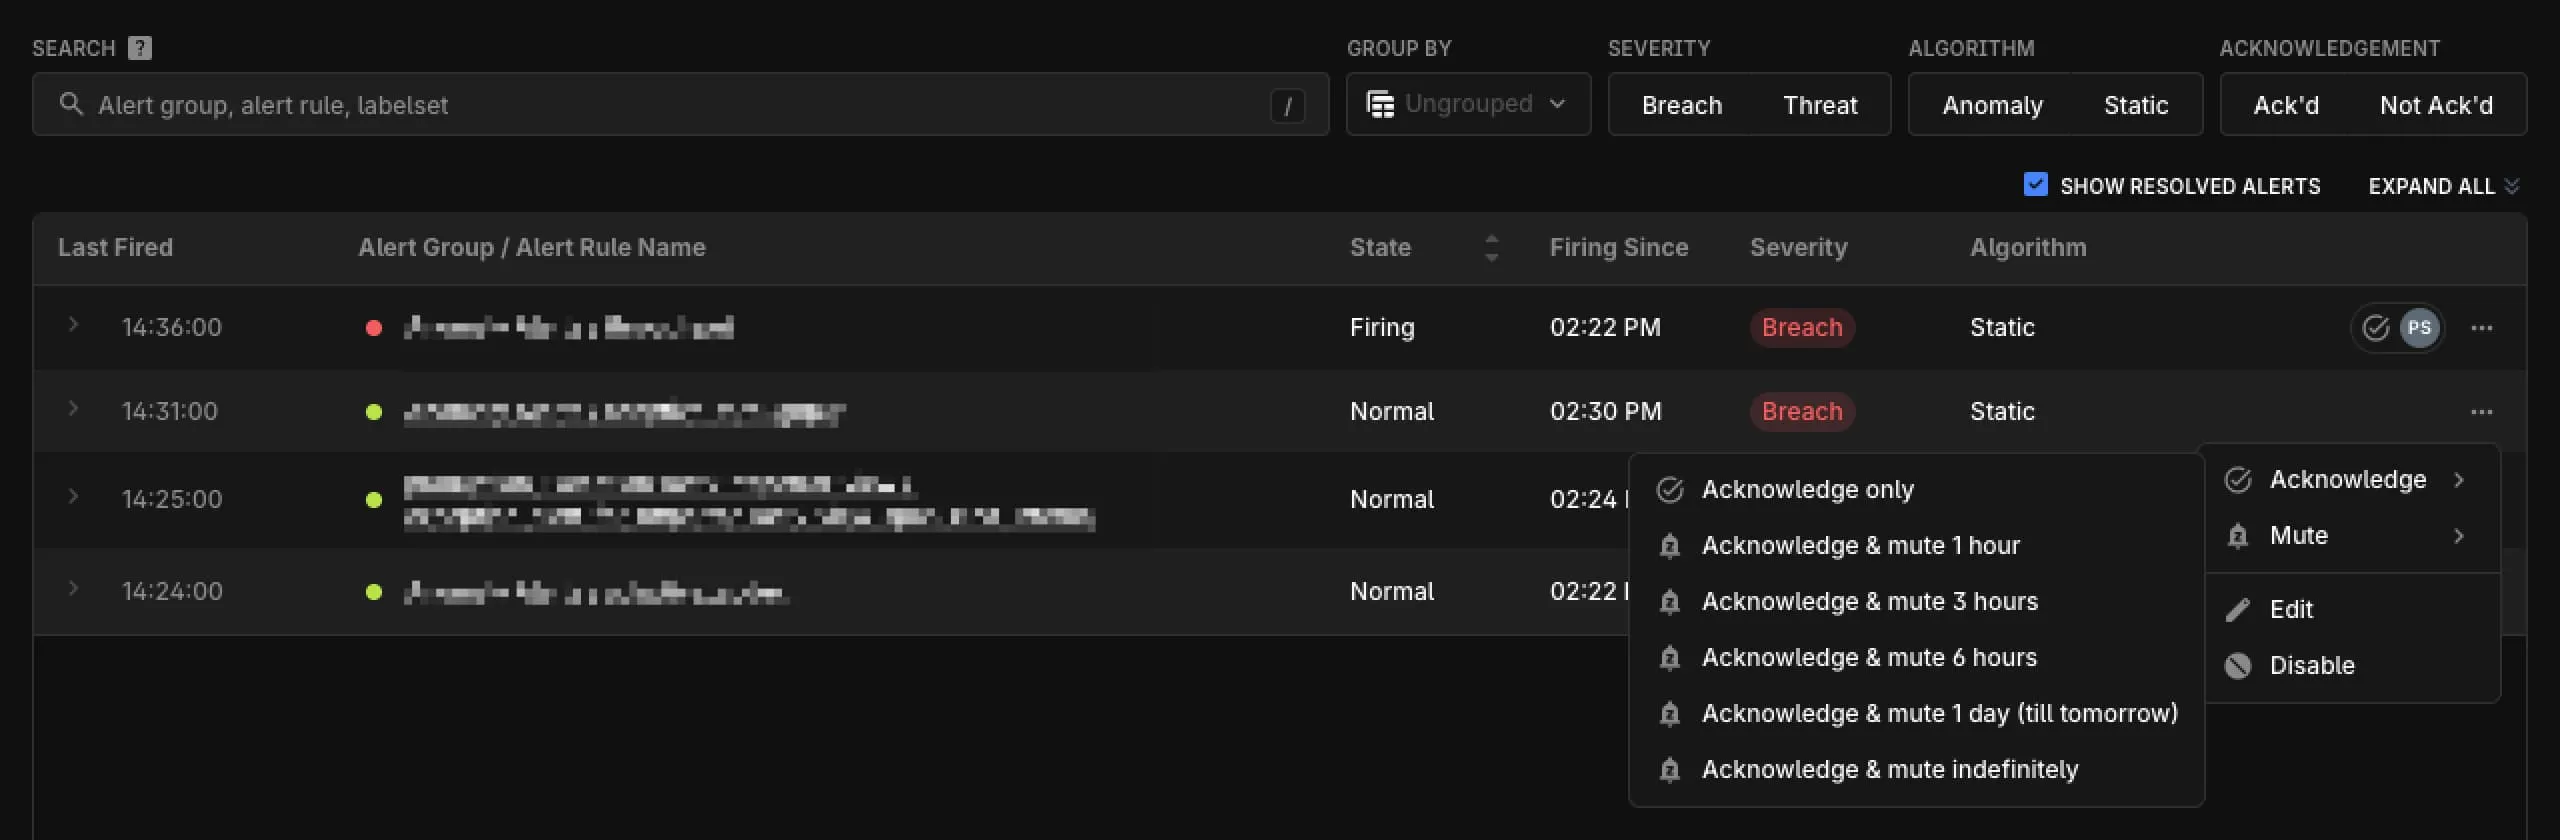
Both places give you the same options:
| Option | Result |
| -------------------------------------------- | ----------------------------------------------------------------------- |
| **Acknowledge only** | You become the owner. The notifications continue. |
| **Acknowledge & mute 1 hour** | You become the owner. The alert rule is muted for 1 hour. |
| **Acknowledge & mute 3 hours** | You become the owner. The alert rule is muted for 3 hours. |
| **Acknowledge & mute 6 hours** | You become the owner. The alert rule is muted for 6 hours. |
| **Acknowledge & mute 1 day (till tomorrow)** | You become the owner. The alert rule is muted until tomorrow. |
| **Acknowledge & mute indefinitely** | You become the owner. The alert rule is muted until someone unmutes it. |
After you acknowledge an alert, the owner appears in every place the alert appears:
* The alert row shows an **owner avatar** with the initials of the owner.
* The alert details header shows **Ack’d by *name***, or **Ack’d and muted by *name*** when the acknowledgement includes a mute.
* Hovering over either one shows the full name of the owner, their email address, and when they acknowledged the alert. For a mute, it also shows when the mute ends.
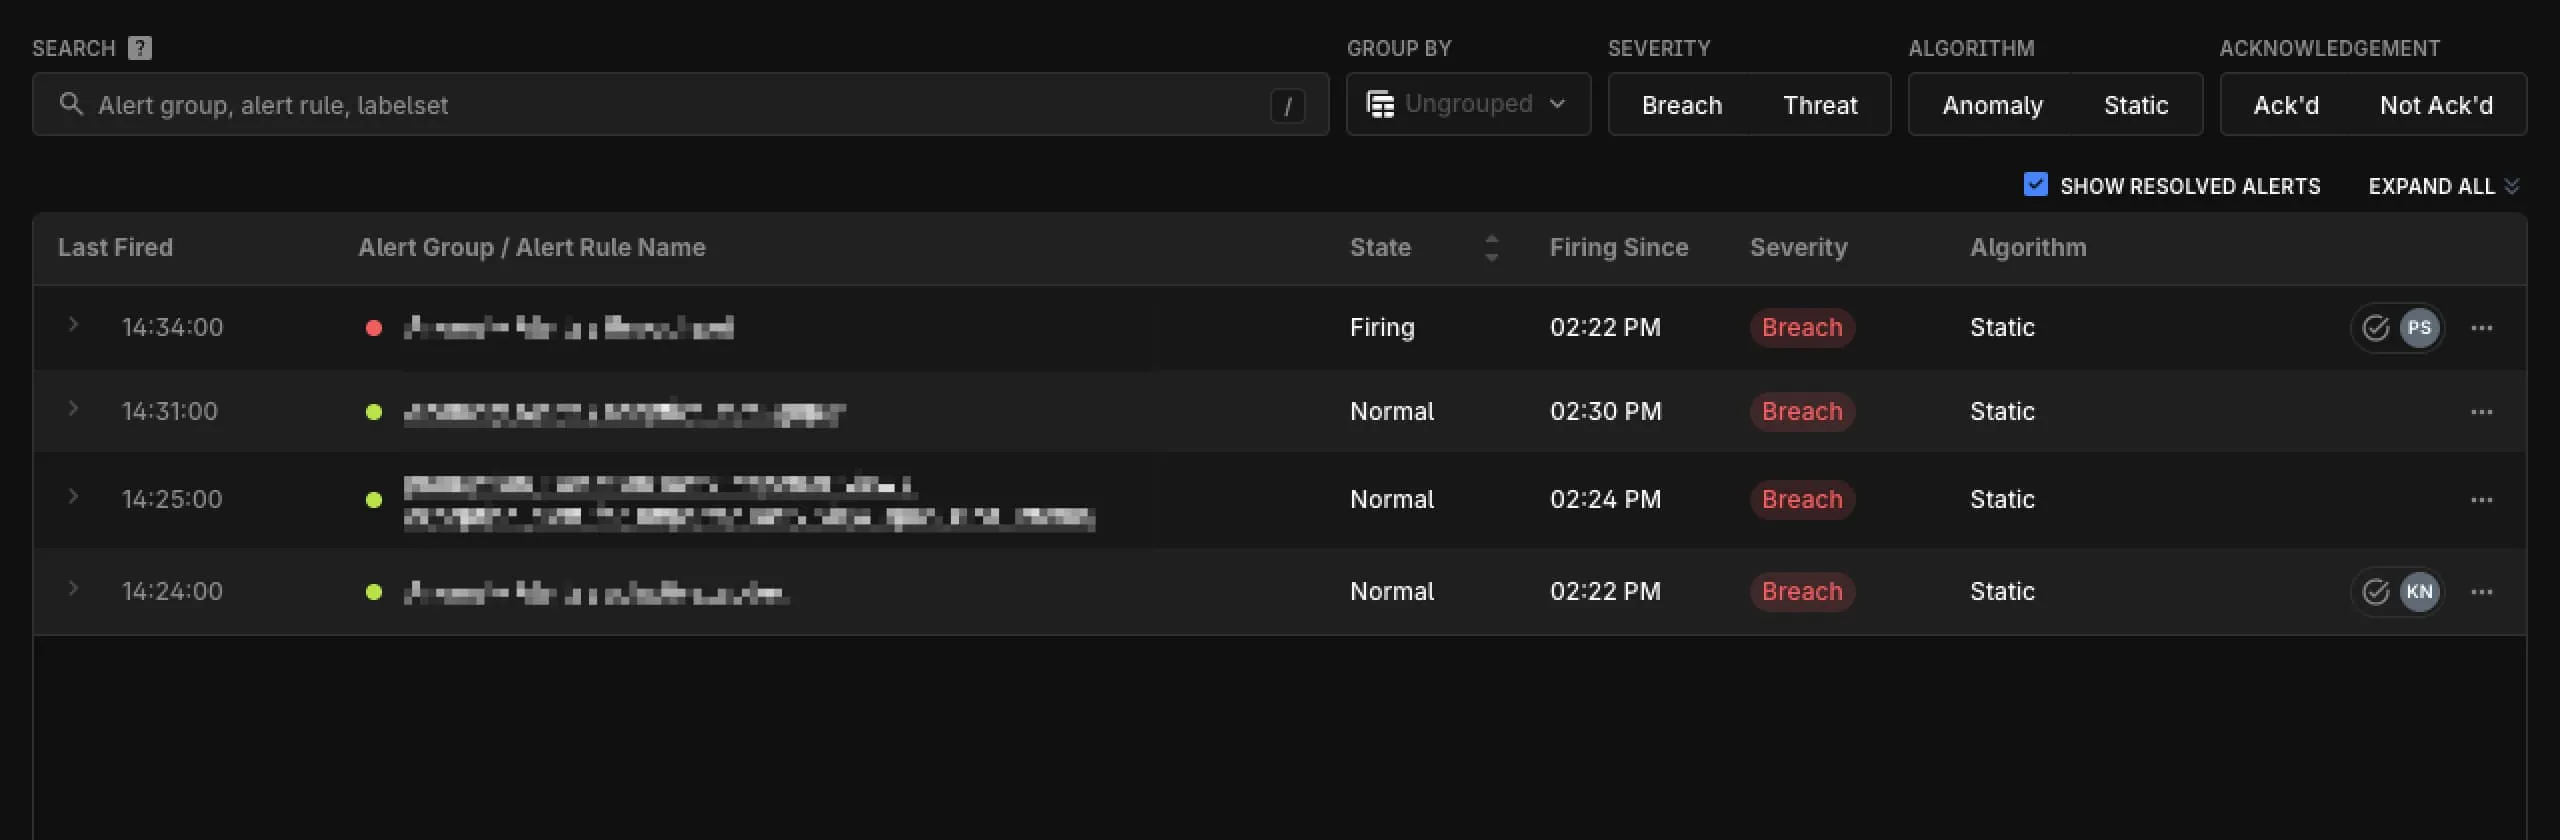
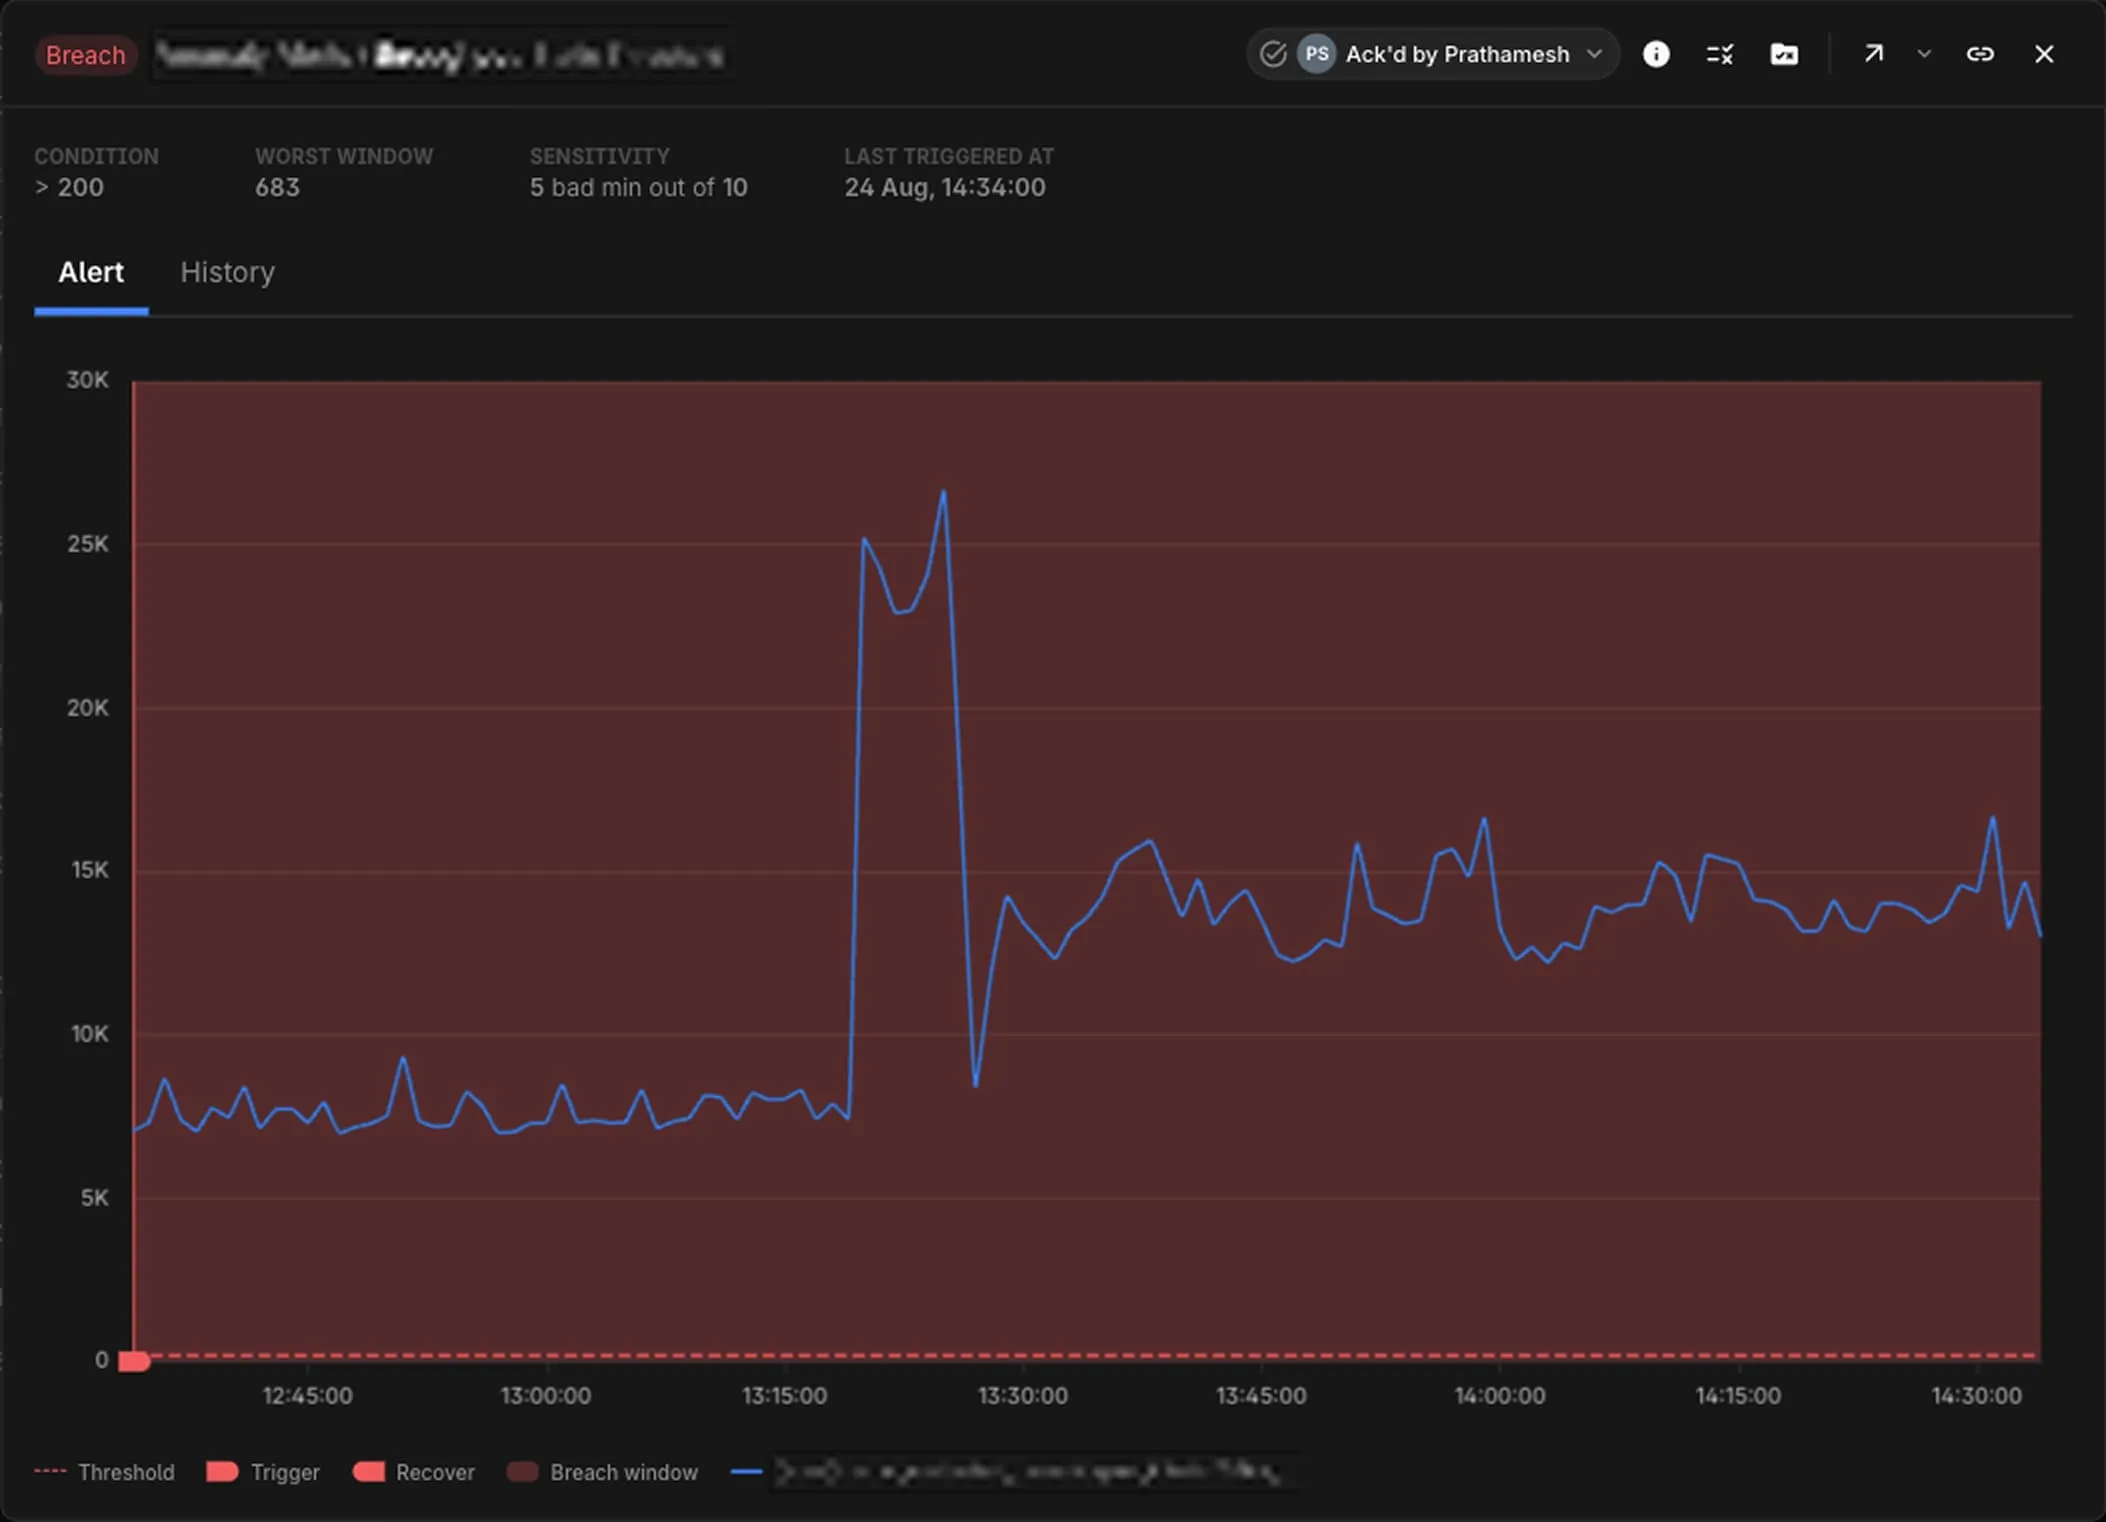
One person owns an alert rule at a time. If someone else acknowledges the alert first, your **Acknowledge** control is replaced by their ownership chip.
## What an Acknowledgement Covers
An acknowledgement applies to the alert rule, not to a single timeseries. Each labelset that fires under the rule shares the same acknowledgement, so the owner appears on the rule row and not on each labelset. A mute also applies at rule level, so **Acknowledge & mute** and the acknowledgement have the same scope.
An acknowledgement continues while the alert fires. It ends when one of these conditions is true:
* The alert resolves.
* The owner or an Admin releases the acknowledgement with **Unacknowledge**.
* Someone reassigns the alert to a different owner.
* The owner is no longer an eligible owner. Refer to [Automatic Release](#automatic-release).
## Release an Acknowledgement
To release the ownership, select **Unacknowledge** from the same menu. The alert becomes unacknowledged, and any Editor or Admin can then acknowledge it.
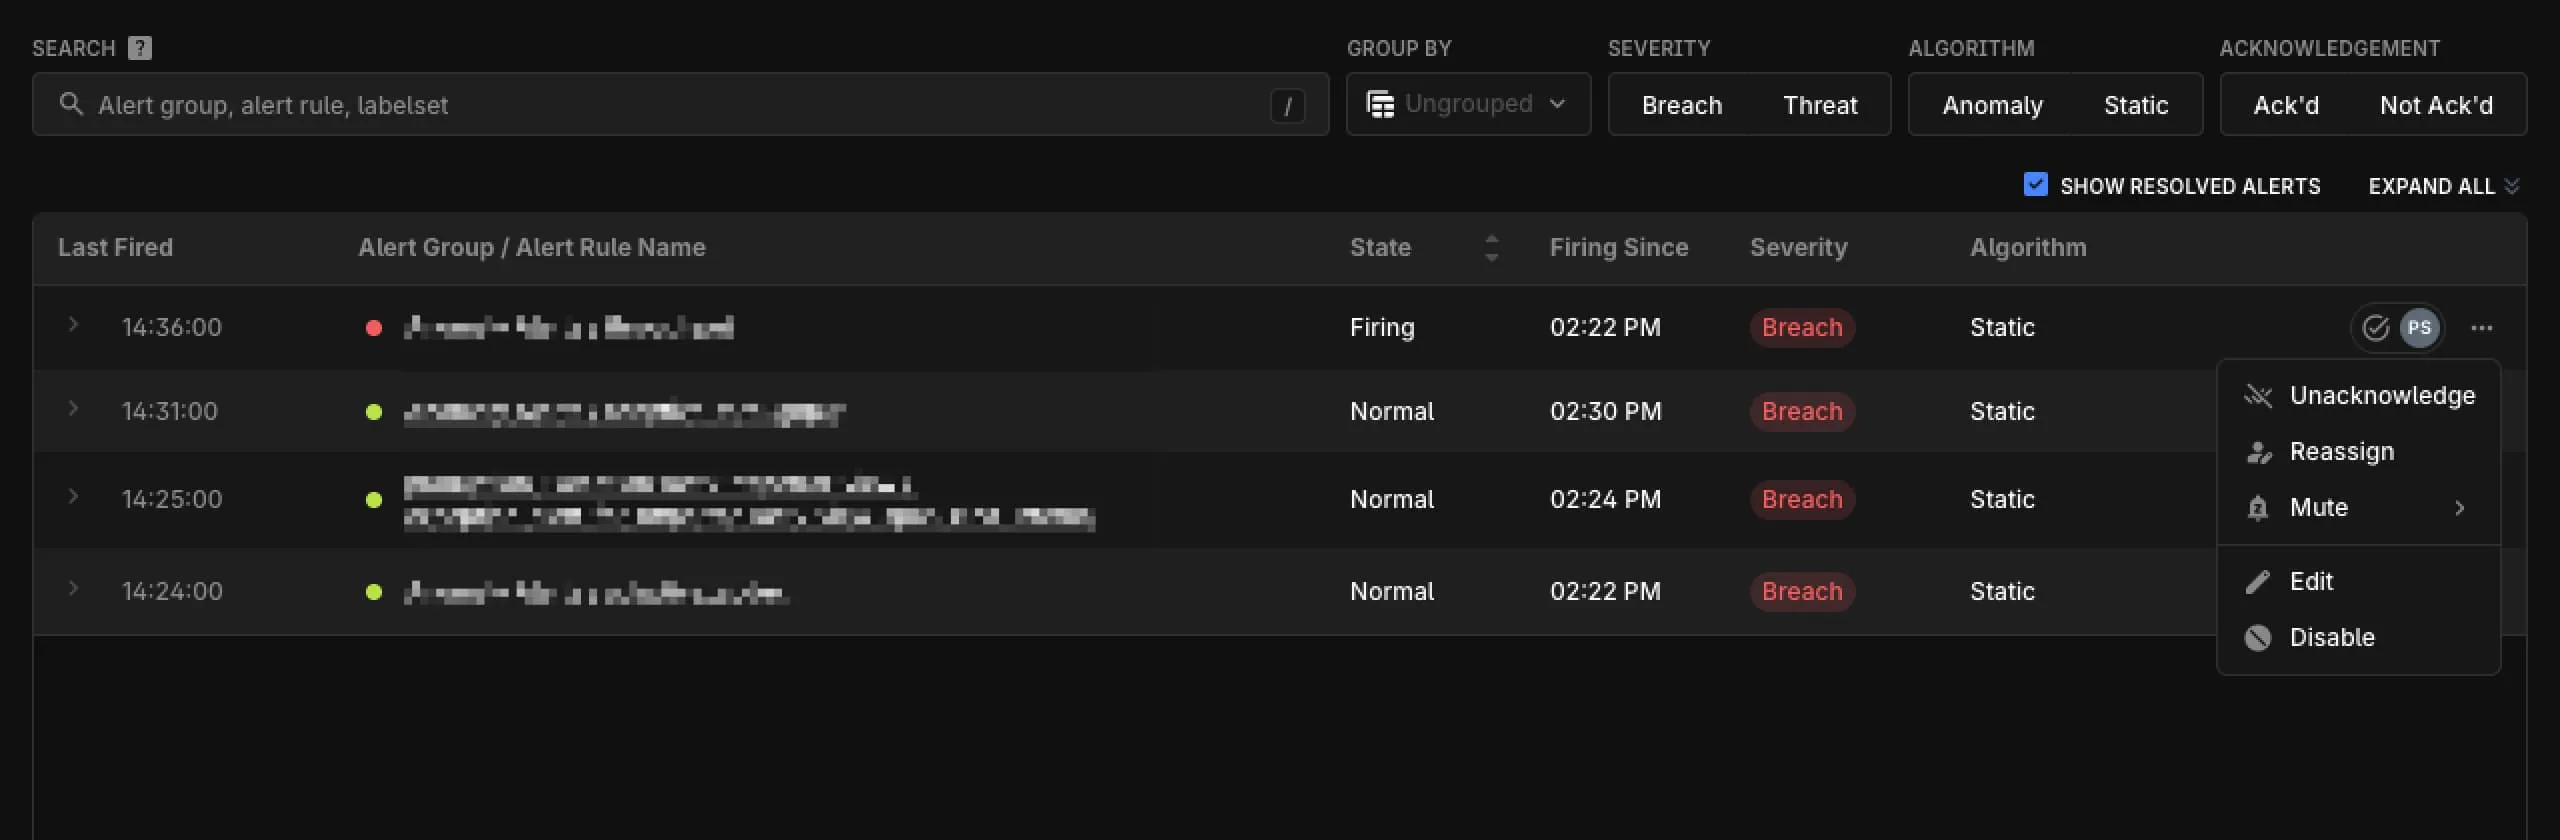
Only the current owner or an Admin can release an acknowledgement. If an Admin releases someone else’s acknowledgement, Last9 asks for a confirmation first, which prevents an accidental release.
If you used **Acknowledge & mute**, a release also unmutes the alert rule. If you muted the alert rule separately, or if you muted its [Alert Group](/docs/alert-rules/#alert-groups-view), the alert rule stays muted and a release does not unmute it.
## Reassign an Alert
To give the alert to someone else, select **Reassign**, then pick them from the list. Last9 replaces your name with the name of the new owner in every place the alert appears.
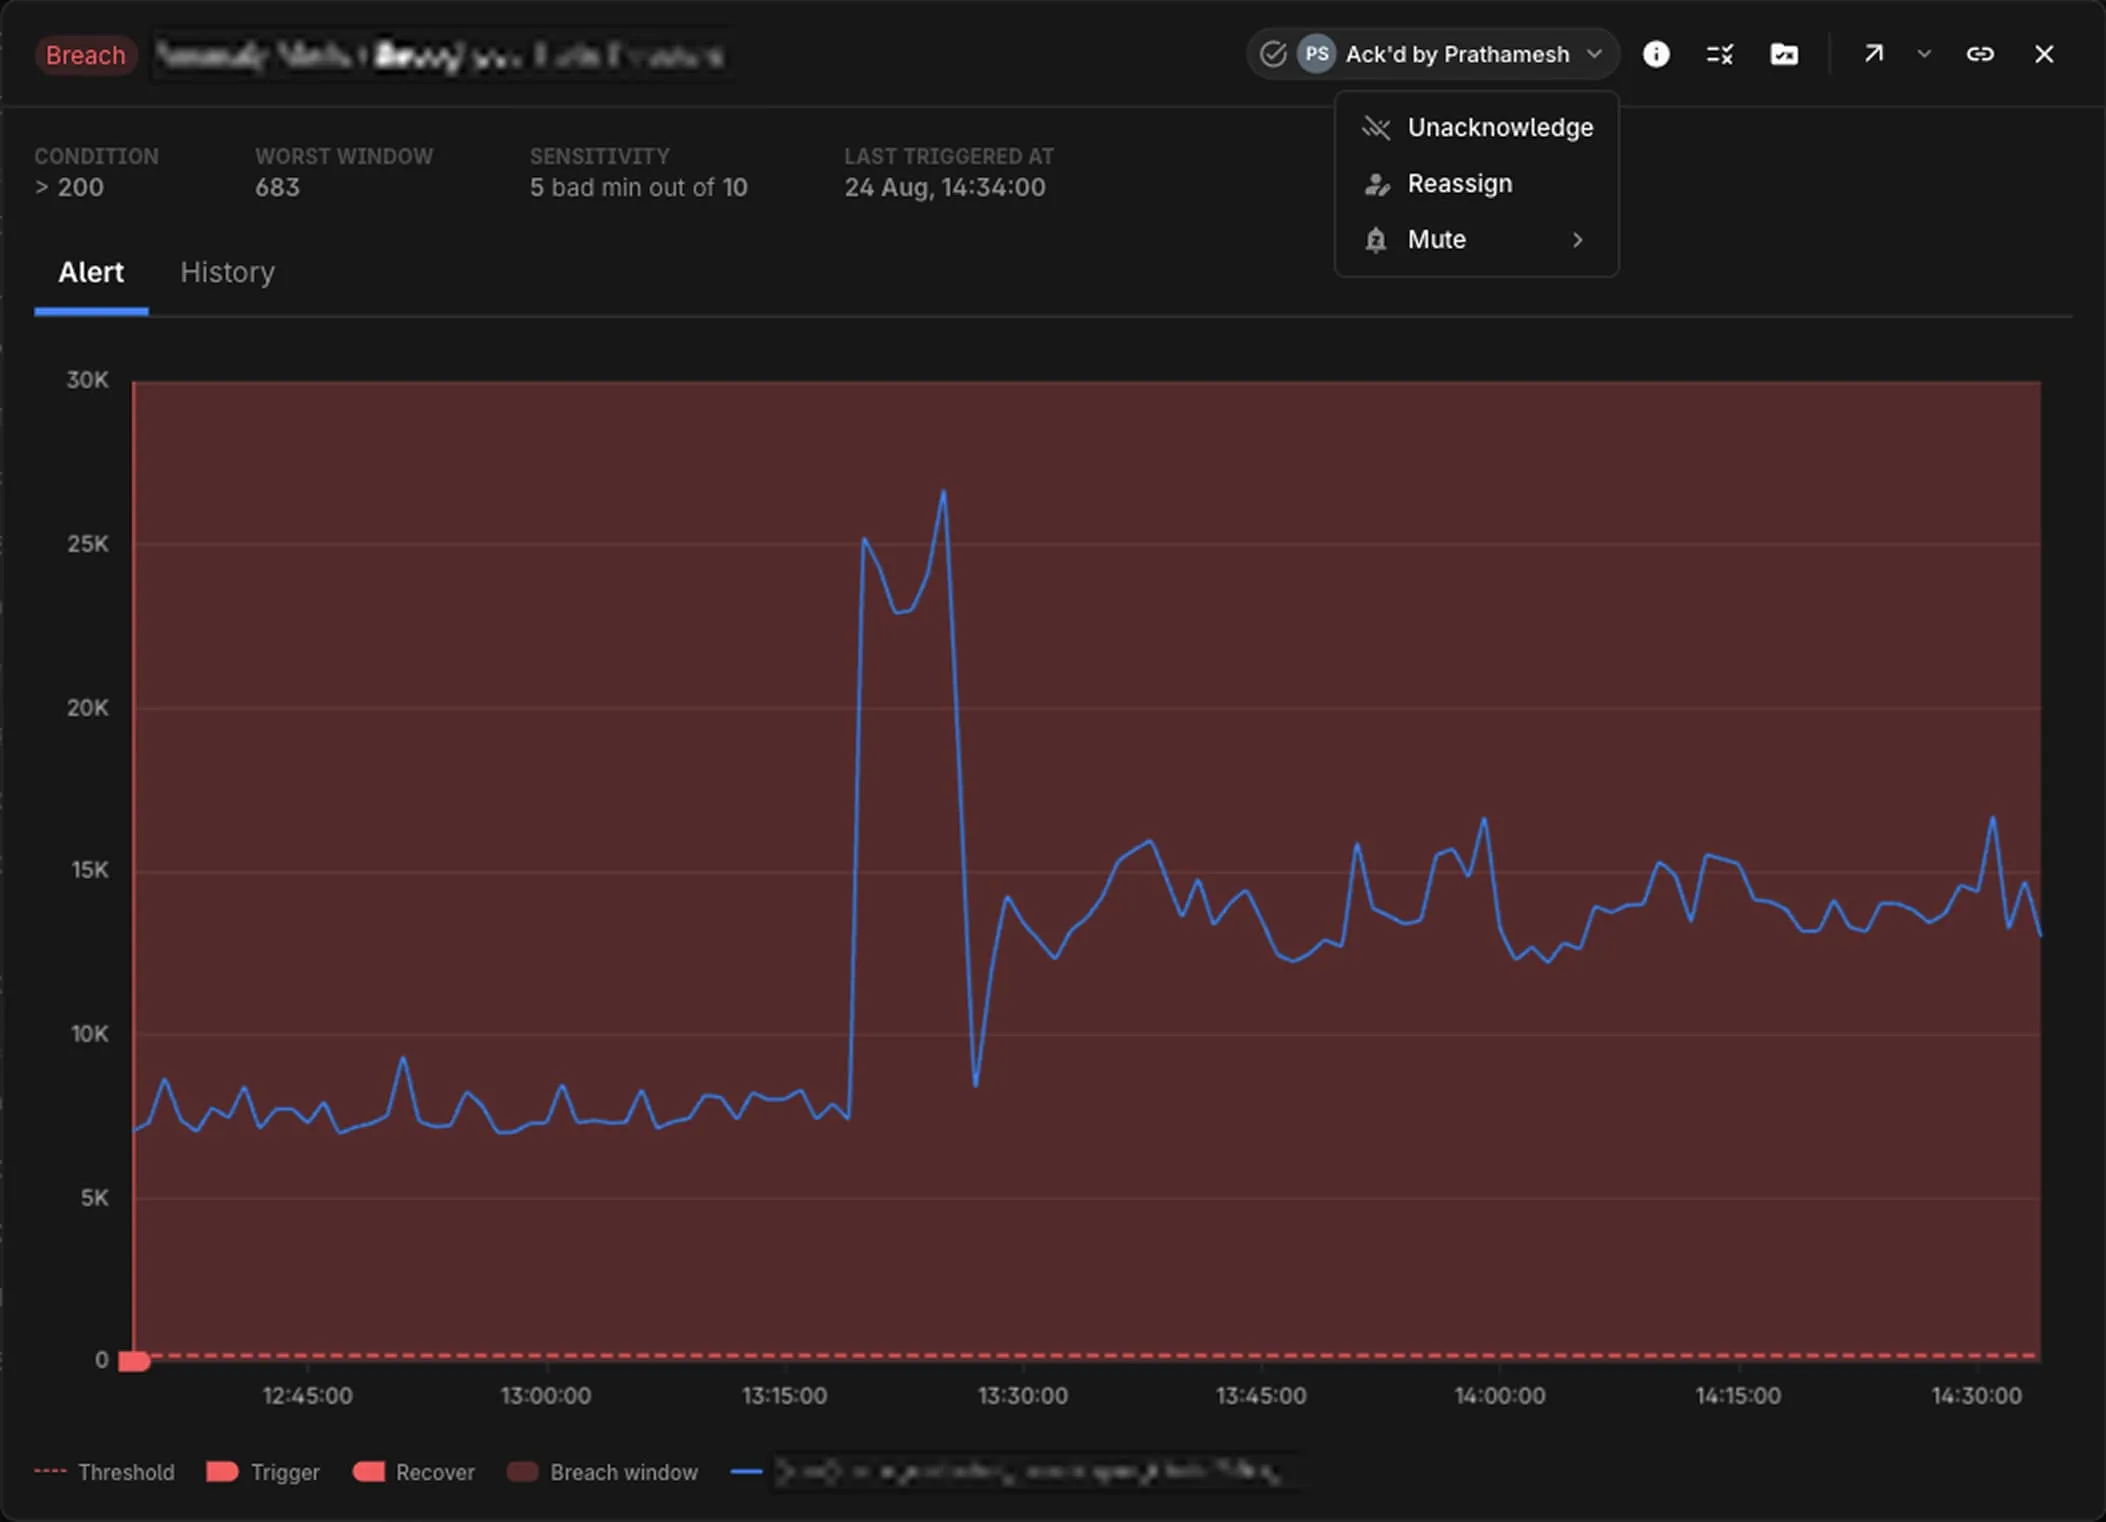
Only the current owner or an Admin can reassign an alert. If an Admin reassigns someone else’s alert, Last9 asks for a confirmation first.
The list shows the active Editors and Admins in your organization. A Viewer cannot own an alert, so the list omits Viewers, and the current owner.
## Permissions
An acknowledgement follows your organization [role](/docs/users/#user-roles):
| Capability | Viewer | Editor | Admin |
| ---------------------------------------- | ------ | ------ | ----- |
| See the owner of an alert | ✅ | ✅ | ✅ |
| Acknowledge an alert | ❌ | ✅ | ✅ |
| Release or reassign your own alert | ❌ | ✅ | ✅ |
| Release or reassign someone else’s alert | ❌ | ❌ | ✅ |
| Become the owner of an alert | ❌ | ✅ | ✅ |
The **Acknowledge & mute** options, and the **Mute** options beside them, also need permission to configure the notification channels. Without that permission, only **Acknowledge only** is available.
## Filter by Acknowledgement
The Alert Monitor has an **Acknowledgement** filter with two values, **Ack’d** and **Not Ack’d**. Use it to separate the alerts that have an owner from the alerts that still wait for one. The filter is reflected in the URL, so you can share a filtered view.
## Automatic Release
An acknowledgement expires when the alert resolves. While the alert is still firing, the acknowledgement does not expire on its own — it stays with its owner until one of the conditions below is met. You can also [release](#release-an-acknowledgement) or [reassign](#reassign-an-alert) it at any time.
An acknowledgement is held by a person, so Last9 releases the acknowledgements of a user when that user can no longer respond. Last9 releases all the acknowledgements of a user in the organization when you:
* change the user to the **Viewer** role,
* remove the role of the user in the organization, or
* deactivate the user, or remove the user from the organization.
Those alerts become unacknowledged, and any Editor or Admin can then acknowledge them.
## Audit Trail
Last9 records each acknowledgement, reassignment, and release in the [Audit Trail](/docs/audit-trail/), with the alert rule and its alert group. Use it to find who owned an alert at a given time.
***
## Troubleshooting
* **“Acknowledged. Rule not muted — the alert group is already muted.”**
Your acknowledgement is saved, but the rule is not muted because its [Alert Group](/docs/alert-rules/#alert-groups-view) is already muted. The group mute already stops the notifications, so no other action is necessary.
* **“Acknowledgement released. Rule could not be unmuted — unmute it from the rule menu.”**
You released the ownership, but the alert rule stays muted. To unmute the rule, use the actions menu of the rule.
* **The Acknowledge option is not available.**
Your role cannot acknowledge alerts — ask an Admin for the Editor role. If only the mute durations are unavailable, ask an Admin for permission to configure the notification channels.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Adaptive Alerting
> How the Adaptive algorithm detects anomalies using a standard-deviation model instead of fixed thresholds.
The **Adaptive** algorithm flags anomalies by comparing a metric against its own recent history instead of a fixed threshold. It learns a baseline band from the metric’s mean and standard deviation over a lookback window, and fires when the metric breaks out of that band — so it adapts to normal traffic variation rather than a number you have to guess. It’s the recommended starting point for general anomaly detection.
## How it works
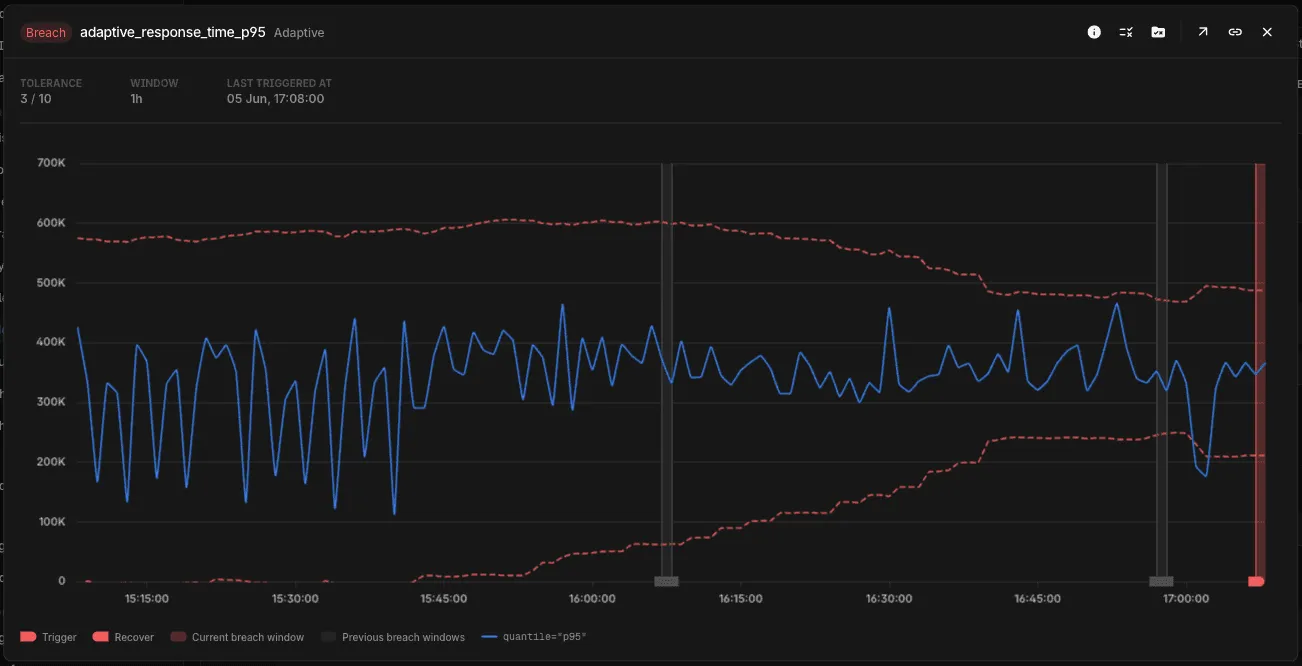
Adaptive builds a baseline band — the mean ± a multiple of the standard deviation over a lookback window — and treats points outside the band as anomalous. Two controls shape it:
* **Tolerance** (1–10) — how wide the band is. Higher values are more tolerant: a wider band and fewer alerts.
* **Window** — the lookback used to learn the band (for example, `1h`). Shorter windows react faster; longer windows smooth over daily or weekly patterns.
The preview shades the learned band (dashed bounds) around the metric, so you can see exactly where it would break out and fire:
## Setting up an Adaptive alert
1. [Create an Alert Rule](/docs/creating-an-alert-rule/) and choose **Metrics**.
2. Build your query in the Builder or PromQL.
3. In the **Condition** section, select the **Adaptive** algorithm.
4. Set **Tolerance** and **Window**.
5. Check the live preview against the learned band, then save.
See [Creating an Alert Rule](/docs/creating-an-alert-rule/#metrics--adaptive) for the full editor walkthrough.
## Recommendations
* **Tolerance** — start in the middle of the range and adjust from the preview. Lower it for critical signals where small deviations matter; raise it for noisy signals to cut false positives.
* **Window** — match it to how the signal behaves: `1h` or less for fast-changing, real-time services; a few hours for standard web services; a day or more for signals with daily or weekly patterns.
## Alerting on logs or traces
Adaptive runs on metrics. To use it on log or trace data, first convert it to a metric with [LogMetrics](/docs/streaming-aggregations/#transforming-logs-to-metrics-last9-logmetrics) or [TraceMetrics](/docs/streaming-aggregations/#transforming-traces-to-metrics-last9-tracemetrics), then point an Adaptive rule at the resulting metric.
## When should I use Adaptive Alerting?
Use Adaptive Alerting for new metric rules when you want to detect deviations from a learned baseline instead of maintaining a fixed threshold. For other cases:
* Use a **static threshold** for fixed or discrete signals.
* Existing legacy spike and changepoint rules continue to evaluate, but those algorithms cannot be selected for new rules. See [Anomaly Algorithms (Legacy)](/docs/anomaly-algorithms/) when maintaining an existing rule.
## Advanced: the `adaptive_std_cmp` macro
For advanced cases — or to embed adaptive logic inside a larger PromQL expression — the same model is available as the `adaptive_std_cmp` macro, used as a **Threshold** query. It returns `1` when the metric deviates beyond the given number of standard deviations and `0` otherwise; set the Threshold to fire when the value is `> 0.5`.
```promql
adaptive_std_cmp(query, std_factor, duration)
```
* **query** — base PromQL metric query
* **std\_factor** — standard deviations from the mean: `2` ≈ 95% of normal variation (sensitive), `2.5` balanced, `3` ≈ 99.7% (least sensitive)
* **duration** — lookback window for the calculation (without quotes)
```promql
adaptive_std_cmp(trace_service_response_time{service_name="prod-api-service"}, 2, 10m)
```
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Agents Monitoring
> Monitor LLM and agent usage across your applications — conversations, token consumption, latency, cost, success rates, and active models — built on OpenTelemetry GenAI semantic conventions
Agents Monitoring gives you a single view of how your applications use large language models and AI agents: how many conversations they run, what they cost, how long calls take, how often they fail, and which models are actually in use.
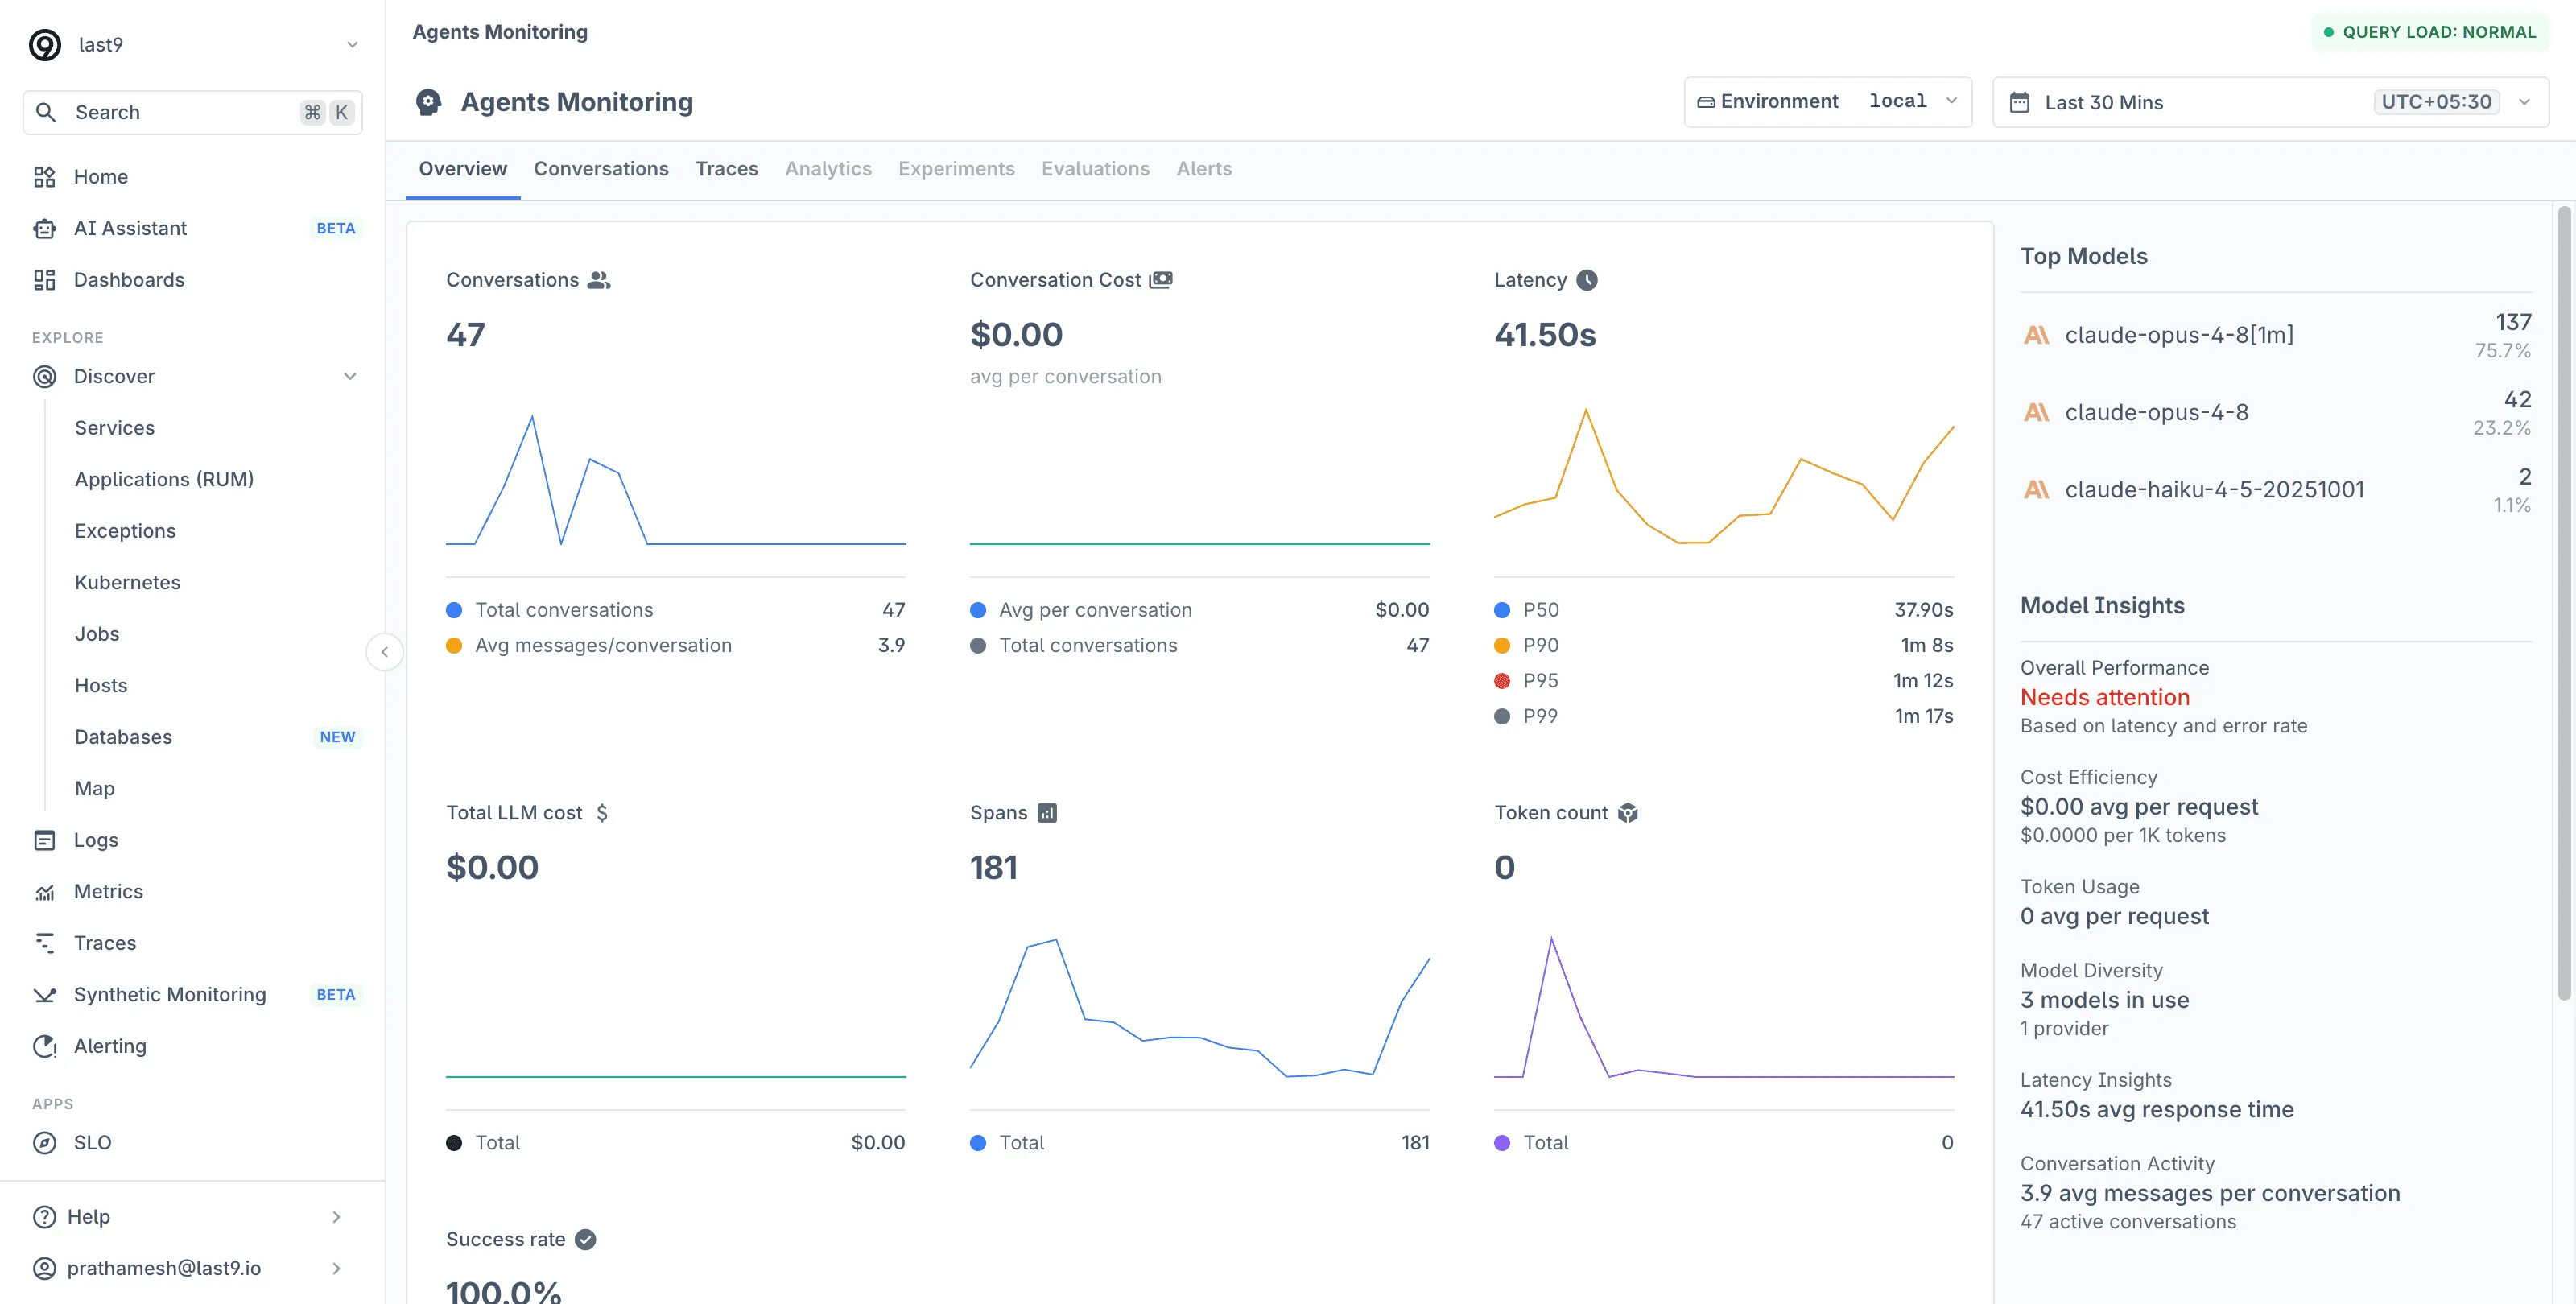
The view is built on the [OpenTelemetry GenAI semantic conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/). Any instrumentation that emits GenAI-convention telemetry feeds it — no Last9-specific SDK required.
## Overview
Open **Agents Monitoring** under the AI section of the sidebar. The Overview tab reports, for the selected environment and time range:
| Card | What it shows |
| --------------------- | ------------------------------------------------------------------ |
| **Conversations** | Total conversations and average messages per conversation |
| **Conversation Cost** | Average cost per conversation |
| **Latency** | P50, P90, P95, and P99 call duration |
| **Total LLM cost** | Spend across all calls in the range |
| **Spans** | Total LLM spans recorded |
| **Token count** | Total tokens consumed |
| **Success rate** | Success and error rate across all requests |
| **Top Models** | Models serving traffic, with request counts and share |
| **Model Insights** | Overall performance, cost efficiency, token usage, model diversity |
The **Conversations** tab lists individual conversations, and the **Traces** tab shows the underlying LLM spans — a slow or failing call links to the full request trace: the endpoint that triggered it, retries, and downstream work.
## Metrics
The overview is backed by GenAI semantic-convention metrics in your Last9 workspace — `gen_ai_client_token_usage_total` for tokens and the `gen_ai_client_operation_duration_seconds` histogram for request counts and latency, with `gen_ai_request_model` and `error.type` labels. The same series are queryable with PromQL in dashboards, alerts, and ad-hoc queries.
## Getting Data In
Instrument your application with any library that emits GenAI semantic-convention telemetry. See the [AI integrations](/docs/integrations/) for supported options, including the [Python GenAI SDK](/docs/integrations/python-genai-sdk/) for LLM observability in Python applications.
Note
Monitoring for coding agents (Claude Code, Cursor, Codex, and others) is a separate **Coding Agents** view fed by the agents’ own OpenTelemetry output. See the [coding agent integrations](/docs/integrations/) to connect them.
***
## Troubleshooting
* **The overview is empty**: no GenAI-convention telemetry has arrived yet. The empty state links to the integrations to set one up. Verify your instrumentation exports `gen_ai_*` metrics by checking the metrics explorer for `gen_ai_client_token_usage_total`.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Last9 AI
> Investigate production issues with Last9 AI across logs, metrics, traces, and alerts, in the dashboard, in Slack, and in your coding agent.
Last9 AI investigates production issues using your logs, metrics, traces, and alerts. Ask about a service and a time window, and it queries your telemetry, reports the evidence behind each finding, and links back to the underlying data in Last9.
It runs on [Mithai](https://github.com/last9/mithai), Last9’s open-source multiplayer agent harness for your organization. Mithai supplies the sessions, memory, skills, and chat adapters behind every surface, so a Slack thread holds one investigation that several engineers work in together. You can also [run Mithai yourself](/docs/ai/collaboration-mode/#build-a-shared-agent-with-mithai) for workflows that Last9 AI does not cover.
## What Last9 AI does
* **Investigates across signals.** It follows an error from an exception to the failing trace and the correlated logs, and checks change events near the incident.
* **Shows its evidence.** Answers include links to the queries behind them, and they separate confirmed findings from possible causes.
* **Works with your team.** Several engineers investigate together in one Slack thread. An AI Assistant conversation is your own, and you can share it with a colleague to read. See [Collaboration mode](/docs/ai/collaboration-mode/).
* **Acts on what it finds.** It can propose a dashboard for the signals you want to keep watching, and it asks for approval before saving a change.
* **Reaches your code.** Your coding agent can query the same telemetry through [Last9 MCP](/docs/ai/mcp/) while you work in the repository.
For the investigation method itself, refer to [Investigate an incident with AI](/docs/ai/investigate-an-incident/).
## Where Last9 AI works
Last9 AI meets you where the work already happens. It runs in the Last9 dashboard, in the exception and dashboard panels you already open, in your Slack incident channel, and in your coding agent.
## [AI Assistant](/docs/ai/ai-assistant/)
[Investigate in a chat conversation and open the underlying data in the dashboard](/docs/ai/ai-assistant/)
## [Exceptions](/docs/ai/analyze-exceptions/)
[Investigate a selected exception in its service and time window](/docs/ai/analyze-exceptions/)
## [Dashboards](/docs/ai/analyze-dashboards/)
[Investigate a selected chart point or table row in its service context](/docs/ai/analyze-dashboards/)
## [Slack](/docs/ai/slack/)
[Investigate with your team in an incident thread](/docs/ai/slack/)
## [Last9 MCP](/docs/ai/mcp/)
[Give your coding agent access to Last9 telemetry while you inspect code](/docs/ai/mcp/)
## [Plugins and skills](/docs/ai/agent-skills/)
[Add task-specific investigation instructions to your coding agent](/docs/ai/agent-skills/)
## [Your own agent](/docs/ai/build-your-own-ai-sre/)
[Query Last9 telemetry from a bot or service you build and operate](/docs/ai/build-your-own-ai-sre/)
MCP supplies the tools that query Last9, and skills supply the instructions for using those tools. Your MCP client runs the agent and controls its tool permissions. The managed surfaces in the dashboard and Slack run the agent for you, although the available workflows differ between surfaces.
## Enable Last9 AI
You need a Last9 account, AI access for your organization, and relevant telemetry flowing into Last9.
An organization admin can open [**AI Settings**](https://app.last9.io/ai-settings) and manage **Enable Last9 AI**. The same page accepts your own model provider key, so your organization can run Last9 AI on an Anthropic or OpenAI key that it supplies and controls.
If the feature is unavailable in your organization, contact .
## Privacy and security
AI investigations use your question, conversation context, and tool results to produce an answer. Tool results can contain telemetry such as log messages, span attributes, and exception details. Consider what your telemetry contains when enabling AI access or connecting an external agent.
For MCP, review the connected client’s model provider, data handling, and tool-approval settings. See [MCP setup](/docs/ai/mcp/#setup) for authentication and [agent integration](/docs/ai/mcp-for-agents/) for programmatic access.
Contact for organization-specific AI availability, model configuration, or data-handling requirements.
***
## Troubleshooting
* **Last9 AI is unavailable in your organization**
Ask an organization admin to check **Enable Last9 AI** in [AI Settings](https://app.last9.io/ai-settings), and to confirm that a model provider key is configured.
* **A surface behaves differently from another**
Available workflows and tool permissions differ between surfaces. Check the page for the surface you are using before comparing results.
* **You need help with one surface**
See [AI Assistant troubleshooting](/docs/ai/ai-assistant/#troubleshooting), [Slack troubleshooting](/docs/ai/slack/#troubleshooting), or [MCP troubleshooting](/docs/ai/mcp/#troubleshooting).
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Last9 plugins and agent skills
> Install Last9 plugins or individual skills for log, trace, CloudWatch, and Go instrumentation workflows.
The [Last9 AI Toolkit](https://github.com/last9/ai-toolkit) provides plugins and skills for coding agents. A plugin bundles skills for a client. Each skill contains instructions for a specific task, such as selecting a service, discovering fields, querying telemetry, and checking the result.
For example, the logs skill tells the agent to confirm the fields available for the selected service. It then uses counts or other summaries to find a pattern before inspecting matching records. The Last9 MCP server supplies the tools that run the queries.
## Choose a skill
| Skill | Use it for | What it guides |
| ------------------ | ----------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------ |
| `last9-logs` | Investigating errors and log patterns | Select the service, discover attributes, summarize patterns, and inspect matching records. |
| `last9-traces` | Investigating latency, errors, or a specific trace | Confirm the service, environment, time, and symptom, then discover fields before building a query. |
| `last9-cloudwatch` | Investigating AWS metrics already ingested into Last9 | Identify the AWS resource and metric statistic, query the selected resource, and distinguish missing data from a measured zero. |
| `go-agent-install` | Adding Last9 instrumentation to a Go application | Inspect the module and framework, check for existing OpenTelemetry instrumentation, configure supported instrumentation, and verify spans. |
CloudWatch investigations cover Billing, RDS/Aurora, ElastiCache, MSK, DynamoDB, EC2, SQS, DMS, KMS, and S3. The CloudWatch skill queries data in Last9, and AWS ingestion setup is a separate step. See [AWS CloudWatch metrics](/docs/integrations/observability/aws-cloudwatch-metrics/) to send the metrics to Last9.
## Install the toolkit
Choose the plugin for your client, or install individual skills with the skills CLI. The Claude Code and Codex plugins bundle the four skills listed above. Connect Last9 MCP separately after the setup.
* Claude Code
Add the marketplace and install its Last9 plugin:
```bash
claude plugin marketplace add last9/ai-toolkit
claude plugin install last9@last9-ai-toolkit
```
The plugin bundles the four skills listed above.
* Codex
Add the marketplace and install its Last9 plugin:
```bash
codex plugin marketplace add last9/ai-toolkit
codex plugin add last9@last9-ai-toolkit
```
The plugin bundles the four skills listed above.
* OpenCode
Version 0.3.0 supports OpenCode V1 and does not run on OpenCode V2. See the [OpenCode migration guide](https://opencode.ai/v2/docs/migrate-v1) for the differences between versions.
The published [Last9 OpenCode plugin](https://www.npmjs.com/package/@last9/opencode-plugin) configures the hosted Last9 MCP server and bundles the four skills listed above. Add it to your `opencode.json` or `opencode.jsonc`:
```json
{
"$schema": "https://opencode.ai/config.json",
"plugin": [["@last9/opencode-plugin", { "org": "" }]]
}
```
Replace `` with your organization slug, restart OpenCode, then authorize access:
```bash
opencode mcp auth last9
```
You can set the `url` option to a full MCP endpoint instead of supplying `org`. The plugin also accepts `LAST9_ORG_SLUG` or `LAST9_MCP_URL` as environment variables. An existing `last9` MCP configuration takes precedence over the plugin’s settings.
The plugin includes the skills, so a separate skills installation is unnecessary. If you prefer to configure MCP and skills separately, use [OpenCode MCP setup](/docs/integrations/opencode/) and the individual skills tab.
* Individual skills
Use an agent that supports [Agent Skills](https://skills.sh), such as Claude Code, Codex, or Cursor. Run the following command:
```bash
npx skills add last9/ai-toolkit
```
Follow the installer’s prompts to select the skills and target agent. To install only the logs skill, run the following command:
```bash
npx skills add last9/ai-toolkit --skill last9-logs
```
To install for Claude Code, run the following command:
```bash
npx skills add last9/ai-toolkit -a claude-code
```
For other ways to install the skills, see the [toolkit installation guide](https://github.com/last9/ai-toolkit#installation).
## Connect Last9 MCP
The logs, traces, and CloudWatch skills require an authenticated Last9 MCP connection in the same agent session. See [Last9 MCP setup](/docs/ai/mcp/#setup) for your client, and check your connection settings on the [MCP](https://app.last9.io/mcp) page in Last9.
Installing a skill or the Claude Code or Codex plugin does not authenticate the client or give it access to telemetry. If the agent cannot find the required tools, check the MCP connection before starting the investigation.
## Run an investigation
Ask your agent to use the installed skill and provide the service or resource and time window it needs. Replace the example resources with your own.
### Find a log error pattern
```text
Use the last9-logs skill to investigate errors for checkout-api
in production over the last 30 minutes. Discover the fields in
the selected service, summarize the main error patterns, and show evidence
for the most frequent pattern.
```
Check that the agent confirms the service and field names before applying filters. Review whether the result is a count of all matching records or a sample of individual records.
### Investigate a slow request
```text
Use the last9-traces skill to investigate slow requests for
checkout-api in production between 14:00 and 14:30 UTC on
2026-09-10. Start by confirming the available attributes, then
find representative slow traces and explain which operations
account for the delay.
```
If you have a trace ID, include it to narrow the investigation. The agent may ask for missing service, environment, or time details.
### Investigate an AWS resource
```text
Use the last9-cloudwatch skill to inspect CPU and query latency
for my RDS instance over the last hour. Confirm the Last9 data
source, AWS account, region, and instance before querying.
State the metric statistics, units, and any missing data.
```
A CloudWatch resource may have no application service label or APM instrumentation. Identify the AWS resource using the dimensions returned by queries and the account and region in its integration settings.
## Instrument a Go service
Run the instrumentation skill from your Go application repository:
```text
Use the go-agent-install skill to inspect this Go service and
add Last9 tracing. Check the framework and existing OpenTelemetry
instrumentation before making changes. Show how to verify a
request appears in Last9.
```
The skill supports automatic wiring for chi and provides manual integration guidance for other frameworks. Review the resulting code changes and instrumentation settings, then generate a request and confirm that its spans reach Last9.
## Verify the result
Skills guide model behavior. They do not replace the client’s permissions, approval controls, or your review of the output.
Before using an investigation result, review the following details:
* Confirm that the agent called the Last9 tools with the intended service, resource, and time window.
* Open returned evidence links and inspect their queries and time windows.
* Check whether a result was sampled, incomplete, or blocked by a tool error.
* Keep a proposed explanation separate from a confirmed cause.
For a complete workflow, see [Investigate an incident with AI](/docs/ai/investigate-an-incident/). To embed Last9 tools in your own agent, see [Build your own AI SRE on Last9 data](/docs/ai/build-your-own-ai-sre/).
***
## Troubleshooting
| Problem | Next step |
| -------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------- |
| The agent does not recognize a skill | Check that you installed it for that agent and that the agent can see it in the current session. |
| The skill is available but Last9 tools are missing | Connect and authenticate Last9 MCP in the same client. |
| The agent guesses a field or service name | Ask it to use discovery tools and the returned names before retrying the query. |
| CloudWatch metrics are not found | Confirm ingestion, data source, account, region, and resource; do not assume every exporter uses the same metric names. |
| Go instrumentation already exists | Have the agent inspect the existing setup before adding another provider or middleware. |
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# AI Assistant
> Investigate errors, latency, and alerts in a Last9 AI chat conversation, then open the underlying telemetry in the dashboard.
AI Assistant is the chat surface for Last9 AI in the dashboard. Ask about a service and time window, review the evidence behind each answer, and open the underlying telemetry in Last9.
Start with a specific service, environment, and time window:
Investigate HTTP 5xx errors for checkout-api in production over the last 30 minutes. Confirm the service and data source, identify the affected routes, and include links to the supporting evidence. Separate confirmed findings from possible causes.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Investigate%20HTTP%205xx%20errors%20for%20checkout-api%20in%20production%20over%20the%20last%2030%20minutes.%20Confirm%20the%20service%20and%20data%20source%2C%20identify%20the%20affected%20routes%2C%20and%20include%20links%20to%20the%20supporting%20evidence.%20Separate%20confirmed%20findings%20from%20possible%20causes.)
Replace `checkout-api` with your service name. For the full investigation method, refer to [Investigate an incident with AI](/docs/ai/investigate-an-incident/).
Conversations are personal
An AI Assistant conversation belongs to you. Teammates cannot see it until you share it, and they can only read what you share. To investigate together in one place, use a [Slack thread](/docs/ai/slack/), where several engineers ask the assistant in the same conversation. See [Collaboration mode](/docs/ai/collaboration-mode/) for shared conversations, Slack investigations, and team access.
## Prerequisites
* AI access enabled for your Last9 organization. See [Enable Last9 AI](/docs/ai/#enable-last9-ai).
* Relevant logs, metrics, or traces flowing into Last9.
## Start a conversation
1. Open [**AI Assistant**](https://app.last9.io/ai-assistant) in the Last9 dashboard.
2. Ask about a service and time window. Include an environment, alert, request ID, trace ID, or error message when available.
3. Review the answer and open its evidence links. Check that the query, filters, and time range match your question.
4. Ask a follow-up in the same conversation. Focus on a service or request, compare with successful requests, or ask which evidence is still missing.

## Work in a conversation
Once a conversation is open, use it to follow the evidence, check an alert, and keep the signals you verified.
### Investigate errors and latency
Ask the assistant to inspect exceptions, log patterns, service performance, and traces. Useful follow-ups connect an observed symptom to a specific request or dependency:
For the failing request identified above, inspect the related trace and logs. Which operation failed, and what evidence supports the explanation?
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=For%20the%20failing%20request%20identified%20above%2C%20inspect%20the%20related%20trace%20and%20logs.%20Which%20operation%20failed%2C%20and%20what%20evidence%20supports%20the%20explanation%3F)
Compare slow and successful requests for the selected route in the same window. Which operations or attributes differ?
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Compare%20slow%20and%20successful%20requests%20for%20the%20selected%20route%20in%20the%20same%20window.%20Which%20operations%20or%20attributes%20differ%3F)
The assistant can only investigate data available to its tools. Missing instrumentation, restricted access, and incomplete results can leave the cause unresolved.
### Review alerts and changes
Use an alert as an investigation starting point. Ask which condition fired, which services are affected, and whether available [change events](/docs/change-events/) overlap with the incident.
Investigate the alert for the window in its message. Check the supporting telemetry and recent change events. Explain what is confirmed and what needs further investigation.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Investigate%20the%20alert%20for%20the%20window%20in%20its%20message.%20Check%20the%20supporting%20telemetry%20and%20recent%20change%20events.%20Explain%20what%20is%20confirmed%20and%20what%20needs%20further%20investigation.)
### Open the evidence links
Responses can include links to the underlying data in Last9. Use them to inspect the query, continue in the explorer, and share evidence with a teammate.
Use the linked query as the starting point for additional filters or a more detailed investigation.
### Create a dashboard from an investigation
Ask the assistant to create a dashboard for the signals you want to keep watching:
Create a dashboard for checkout-api using the request rate, error rate, and latency metrics we verified in this investigation. Show the proposed dashboard before saving it.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Create%20a%20dashboard%20for%20checkout-api%20using%20the%20request%20rate%2C%20error%20rate%2C%20and%20latency%20metrics%20we%20verified%20in%20this%20investigation.%20Show%20the%20proposed%20dashboard%20before%20saving%20it.)
The assistant can propose creating or updating saved dashboards. Review the operation and its arguments before approving the change. For an existing dashboard, provide its URL and ask for an update.
## Chat history
Use chat history to return to an investigation and continue asking questions. Start a new chat for an unrelated incident so its details stay separate.
When reopening an older conversation, ask for a new query window before relying on its recovery status. Previous answers describe the data queried at that time.
## Ask mode in Logs and Traces
For a focused query in [Logs Explorer](/docs/logs-explorer/) or [Traces Explorer](/docs/traces-explorer/), use the **Ask** tab to describe the records you want to find:
```text
Show errors for checkout-api in production over the last 30 minutes.
```
Review the generated filters and matching results. Use AI Assistant when you need a conversation that follows evidence across signals.

***
## Troubleshooting
* **AI Assistant is unavailable**
Ask an organization admin to check **Enable Last9 AI** in [AI Settings](https://app.last9.io/ai-settings).
* **The answer covers the wrong service**
Confirm the service name, environment, and data source, then correct them in a follow-up.
* **No data is returned**
Check the time zone, time window, filters, and whether the relevant signal is ingested.
* **The analysis is incomplete**
Ask which queries failed or returned partial results. Resolve those gaps before relying on the conclusion.
* **A saved answer no longer matches current conditions**
Ask the assistant to query a new explicit window.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Analyze dashboard data with AI
> Start AI analysis from a selected chart point or table row, review its context, and continue a focused investigation.
Use **Ask Last9 AI** on a dashboard chart point or table row to investigate a value in its service context. For example, start from a latency spike or an unexpected error count instead of typing the selected value and labels into a new conversation.
The action analyzes the selected point. To create or update a saved dashboard, see the separate [dashboard creation workflow](/docs/ai/ai-assistant/#create-a-dashboard-from-an-investigation).
## Start from a chart or table
1. Open the dashboard and use its variables and time controls to locate the data you want to investigate.
2. Click a data point in a supported chart or a row in a supported table.
3. Select **Ask Last9 AI** from the point’s menu.
4. Open the **AI Analysis** tab if it is not already selected. The analysis starts automatically.
5. Read the response in the panel.
The action requires AI access and a point whose service context Last9 can identify. It may be absent for panels without a supported service or APM context. Markdown panels do not provide this action.
## Understand the selected context
The analysis starts with information from the clicked point:
| Context | What it contributes |
| ---------------------------------------- | ------------------------------------------------------------------------ |
| Resolved metric query | The selected series query with dashboard variables substituted. |
| Timestamp and value | The observation you selected. |
| Metric labels | The dimensions attached to that observation. |
| Service and environment, when identified | Last9 identifies the service and environment from the available context. |
Check that the service and environment in the result match the point you meant to investigate.
The dashboard time picker helps you find the observation, but the full dashboard time range is not passed as the investigation window. The analysis also excludes the dashboard’s other panels and its full variable configuration. If your question depends on additional dashboard details, provide them in a separate AI Assistant conversation.
## Review the analysis
The analysis explains what the metric measures and the selected value. It assesses whether the value appears normal or concerning when the context supports that judgment, then describes possible causes and next investigation steps.
For example, a high latency value can be the starting point for checking slow requests. To determine whether latency increased over a period, compare time windows using the same service, route, and request filters.
The panel does not edit the chart, query, or saved dashboard, and you cannot type follow-up questions in it. The analysis is your own and has no share link. To give a colleague the findings, continue in AI Assistant and [share that conversation](/docs/ai/collaboration-mode/#share-an-ai-assistant-conversation).
## Continue the investigation
For a follow-up, open [**AI Assistant**](https://app.last9.io/ai-assistant) and provide the relevant service, environment, timestamp, labels, and question. Include the chart query if you want to check its calculation:
```text
I selected a latency spike for checkout-api in production at
14:12 UTC on 2026-09-10. Investigate 14:00 to 14:30 UTC and compare
it with the previous 30 minutes. Check slow traces and related
logs, and distinguish confirmed findings from possible causes.
```
Replace the example details with the point you selected. See [Investigate an incident with AI](/docs/ai/investigate-an-incident/) for the follow-up workflow.
***
## Troubleshooting
* **Ask Last9 AI does not appear in the point’s menu**
Ask an organization admin to check **Enable Last9 AI** in [**AI Settings**](https://app.last9.io/ai-settings). The action is available on supported charts and tables only.
* **The analysis has no service context**
Open **AI Assistant** and supply the service, environment, timestamp, and question directly.
* **The analysis covers the wrong data point**
Use the dashboard variables and time controls to locate the value you want, then select the point again. See [Using Dashboards](/docs/using-dashboards/) for variable and time selection.
* **You cannot ask a follow-up question in the panel**
Open **AI Assistant** and include the service, timestamp, labels, and the chart query.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Analyze exceptions with AI
> Start an AI investigation from an exception, review whether the evidence supports code changes, and share the findings with a coding agent.
Start an AI investigation from an exception’s detail panel to inspect the failure in its service and time window. Last9 uses the exception details to gather related telemetry, then reports whether the evidence supports starting code changes or needs more investigation.
## Start from an exception
1. Open [Exceptions](/docs/discover-exceptions/) in Last9 and select the time range you want to investigate.
2. Click an exception row to open its detail panel.
3. Click **Investigate with AI**. The investigation starts when the dialog opens.
4. Review the streamed investigation notes and the resulting analysis.
The action is available where exception AI investigation is enabled. If it is disabled, ask an organization admin to check **Enable Last9 AI** in [**AI Settings**](https://app.last9.io/ai-settings).
## What the investigation uses
You do not need to retype the exception details. Last9 supplies the selected exception’s identity and fingerprint, service, operation, cluster, and time window.
Last9 uses the selected exception details to look for supporting evidence:
| Evidence | What it helps explain |
| -------------------- | -------------------------------------------------------------- |
| Exception details | The failure being investigated and its recorded context. |
| Failing traces | The operations and dependencies involved in affected requests. |
| Correlated logs | Error messages and request details related to the failure. |
| Service dependencies | Where an upstream or downstream service may be involved. |
| Change events | Changes near the incident that may warrant investigation. |
The available evidence depends on what is recorded for the selected exception and time window. For example, if the exception cannot be linked to a trace, the investigation may be unable to confirm a cause in a downstream service.
## Review the result
The result includes a written analysis and a status indicating whether the findings support starting code changes:
| Status | What to do next |
| -------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------- |
| **Ready for code changes** | Review the supporting evidence and source context, then hand the investigation to the engineer or coding agent that will prepare the change. |
| **More evidence needed** | Review the listed gaps. Collect the missing source, reproduction details, or telemetry before treating a proposed cause as established. |
The status describes whether the investigation is ready for an engineer or coding agent to prepare a change. It does not mean a fix has been written, tested, or deployed.
The investigation is your own and has no share link. Use **Copy investigation** to pass the report to a teammate or a coding agent.
Use **Run again** to rerun the investigation. Use **Continue in AI Assistant** to follow up on the findings. For example:
```text
Which missing evidence would distinguish the two possible causes?
Check whether the related logs or traces can resolve the uncertainty
in the same incident window.
```
To investigate a different period, return to Exceptions and select the new time range. Start another investigation from the relevant exception.
## Hand the investigation to a coding agent
Click **Copy investigation** to copy the report. It includes the exception details, findings, evidence, possible causes, source code information, reproduction details, and remaining gaps.
Paste the report into your coding agent in the relevant repository so the agent can locate the affected code and check a proposed fix. When the investigation is ready, the agent can use the report to prepare a draft pull request. Code review, testing, merge, and deployment remain separate steps.
The exception workflow investigates the failure and prepares a report. It does not create a pull request or deploy a fix from the exception panel.
For a broader incident, refer to [Investigate an incident with AI](/docs/ai/investigate-an-incident/). To connect telemetry tools to the coding agent that receives the report, see [Last9 MCP setup](/docs/ai/mcp/#setup).
***
## Troubleshooting
* **Investigate with AI is not available in the detail panel**
Ask an organization admin to check **Enable Last9 AI** in [**AI Settings**](https://app.last9.io/ai-settings).
* **The status reads More evidence needed**
Review the listed gaps. Collect the missing source, reproduction details, or telemetry before you treat a proposed cause as established.
* **The investigation cannot confirm a cause in a downstream service**
Check whether the exception is linked to a trace in the selected window. Select a window where the failing requests are recorded, then start the investigation again.
* **The analysis covers the wrong period**
Return to Exceptions, select the new time range, and start another investigation from the relevant exception.
* **The copied report lacks the code context your agent needs**
Open the evidence links and add the missing source or reproduction details before you paste the report into the coding agent.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Build your own AI SRE on Last9 data
> Connect your own agent to Last9 MCP, preserve incident details, query telemetry, and return an investigation report with supporting evidence.
Connect your own agent to Last9 MCP to investigate an alert or answer an operational question using Last9 telemetry. You choose the model, trigger, conversation storage, and destination for the answer. Last9 provides tools for querying logs, metrics, traces, exceptions, alerts, and other supported data.
This page describes how to design that agent. For managed chat in Last9, use [AI Assistant](/docs/ai/ai-assistant/) or [Slack](/docs/ai/slack/). For team conversations and a framework option for your own shared agent, see [Collaboration mode](/docs/ai/collaboration-mode/).
## Where this guidance comes from
Some guidance on this page comes from an observed integration, where a team connected an internal chat bot to the managed Last9 assistant. The notes marked **From an internal chat integration** record what failed in that deployment. They omit identifying details, and they describe observed failures rather than a recommended implementation.
## Prerequisites
Your agent reaches Last9 telemetry through Last9 MCP, so make the connection work before you design the workflow.
* AI access enabled for your Last9 organization. See [Enable Last9 AI](/docs/ai/#enable-last9-ai).
* Relevant logs, metrics, or traces flowing into Last9.
* An agent framework or SDK that can call a remote MCP server and run a tool-use loop.
* An MCP-type Client token from Last9 Query Tokens, kept in your application’s secret storage. See [MCP for agents](/docs/ai/mcp-for-agents/) for token setup and SDK examples.
* Your organization’s hosted MCP endpoint, which you can check on the [MCP](https://app.last9.io/mcp) page in Last9:
```text
https://app.last9.io/api/v4/organizations//mcp
```
Send the token using the authentication mechanism your MCP client supports. Connect the client and list the available tools, then run one read query against a service you know has data. Use the tool schemas returned by the connection to construct calls, because parameters and availability depend on the connected server.
## Design the investigation workflow
Decide what the agent investigates, which tools it can call, and what it must return, before you connect it to an incident channel.
### Start with one workflow
Pick a specific job, such as explaining a service alert, investigating increased latency, or summarizing service errors. Divide the work between the following parts of your application:
| Part | Responsibility |
| ------------------ | ---------------------------------------------------------------------------------------------------------------------- |
| Trigger | Receive an alert, chat message, or request containing an operational question. |
| Your application | Authenticate the request, record the affected service and time window, retain conversation context, and run the agent. |
| Model | Select from the tools you expose, interpret their results, and ask for missing information. |
| Last9 MCP | Execute supported queries against Last9 and return telemetry results. |
| Report destination | Show the findings, evidence links, open questions, and next action in your application or incident thread. |
First, your application receives an alert, chat message, or request. It then sends the question to the model and runs the model’s Last9 MCP tool calls until it can return an investigation report. Your application controls execution limits and access to tools.
### Preserve incident context
Store the incident’s service, environment, and time window with the conversation, separately from the model’s written answer. Follow-ups such as “share the root cause analysis” can then use the same incident details. Identify each conversation by organization, user, and chat or incident thread to keep unrelated investigations separate.
For example, your application could store the following record:
```json
{
"incident_id": "incident-123",
"service": "checkout-api",
"environment": "production",
"start_time": "2026-09-10T14:00:00Z",
"end_time": "2026-09-10T14:30:00Z",
"question": "Why did HTTP 5xx responses increase?"
}
```
The example illustrates a record in your application, not a Last9 API payload. Store the verified organization and data source alongside it. Add request IDs, trace IDs, alert details, and corrected service names as they become available.
Use the same absolute time window when comparing logs, metrics, and traces. For a follow-up about recovery, query a new window and keep the original incident window for comparison.
Store the original message separately from a follow-up rewritten to include prior context. Preserve the service, host, environment, time window, and requests for logs or root cause analysis. Compare the message your application received with the text sent to the model, especially when your bot also creates a preview or summary for display. For example, rewriting “compare it with last week” should add the previously selected service and time window without dropping the comparison request.
From an internal chat integration
The integration used prior questions and answers to resolve a follow-up. During debugging, shortened and rewritten requests lost the requested time period or the investigation intent.
### Select tools for the job
Expose a small set of read tools appropriate to the workflow. Confirm the names and schemas in your connected server. The [MCP tool reference](/docs/ai/mcp/#available-tools) describes the available categories.
| Question | Useful starting points |
| ------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------- |
| Which service or data source matches the request? | Use entity and data-source discovery tools. |
| How much HTTP traffic arrived, and from which callers? | Query access logs for the service and time window, then group by observed path, status, client, or user-agent fields. |
| What failed? | Inspect exceptions and service logs, then use log queries to summarize matching errors. |
| Why was a request slow? | Check service performance, traces, and trace waterfalls, then compare groups of requests. |
| What changed near the incident? | Check change events and alert details against telemetry from the same time window. |
| Is an AWS resource constrained? | Discover available metrics, confirm the resource, statistic, and unit, then query the selected resource. |
Discover field names before building filters. For example, two services may record HTTP status under different attributes. A filter on a guessed field can return no matches even when the failures are present.
Reuse the [Last9 agent skills](/docs/ai/agent-skills/) for log, trace, and CloudWatch investigation instructions where your agent supports them. Keep their references available to the agent and use the connected tools’ schemas as the parameter source.
Guide your agent to discover available access log fields and filter by the relevant host, path, method, and time. Use traces to add request detail when available. If one service lookup finds nothing, verify the service and time window, then check other relevant signals before ending the investigation.
Report only dimensions that the returned data supports. For example, a request count alone cannot establish which client made the requests.
From an internal chat integration
Questions about endpoint traffic, callers, user agents, and HTTP status distribution needed access logs. Missing traces did not establish that no useful telemetry existed.
For daily p95 or p99 latency, specify which requests to include, the duration unit, and the time zone that defines each day. Keep the service, route, environment, and success or error filters consistent across days. Include request counts so days with little traffic are visible in the comparison.
Calculate each percentile from suitable data for the requests included on each day. Averaging hourly p95 values does not produce a daily p95. If the available metric only exposes precomputed percentiles, explain which requests and time period the series represents before comparing its values.
### Give the agent a clear contract
An investigation contract states what the agent must check and return. Use the following requirements as a starting point for your agent’s prompt:
```text
Investigate the supplied incident using the enabled Last9 read tools.
1. Confirm the service, environment, data source, and time window.
2. Discover available fields before constructing filters.
3. Establish the observed symptom, then test possible explanations
with related telemetry for the same service and time window.
4. Distinguish aggregate measurements from sampled records.
5. Report failed queries, missing data, and execution limits explicitly.
6. Return confirmed findings with evidence links, possible causes
with supporting evidence, and the next targeted check.
7. Describe a fix as proposed unless execution is separately
confirmed. Never infer recovery from silence alone.
```
Implement permissions in your application or MCP client. For a read-only investigator, maintain a list of permitted read tools and check it when exposing or calling tools. Exclude dashboard creation, dashboard updates, and other changes. A prompt asking for read-only behavior is not an access control.
### Set limits and return partial results
Set limits on elapsed time, tool calls, query windows, and result sizes in your application. Start with limits that let the workflow complete, then adjust them based on test runs.
When a query fails or the agent exceeds a limit, return the evidence already collected and the next useful check. Record whether each query succeeded, returned no matches, returned a sample, or failed. Do not treat a timeout as a zero count or proof that no matching data exists.
An investigation report should include the following details:
* State which service and time window were investigated.
* List the confirmed findings and supporting queries or links.
* Explain the possible causes, what could not be checked, and what would confirm or reject each cause.
* Recommend the engineer’s next step.
Store the relevant tool results or evidence references with the incident. A follow-up can then reuse verified observations without rerunning every query, while still making a fresh query when asked about current conditions.
An interactive chat can ask for missing information. An automated caller needs a predictable outcome. When the request already supplies a service and time window, reuse them rather than asking again.
If an automated request lacks a required service, resource, or time window, return a structured incomplete result or error listing the missing fields. Do not leave the job waiting for a conversational answer the caller cannot provide. Define completed, incomplete, and missing-input outcomes in your application rather than parsing them from the model’s final sentence.
Limit concurrent investigations and record failures before increasing the number of requests. Set retry limits for read queries, and retry only errors that may be temporary. Test concurrent calls, long query windows, and retries with your own workload.
From an internal chat integration
Concurrent calls failed until the team added a queue in its application. A workaround observed in one integration does not define a concurrency limit for all Last9 users.
## Test and extend the agent
Confirm the agent’s behavior against real telemetry before an engineer depends on it. Add any change to a system as a separate workflow.
### Test the workflow with real telemetry
Before connecting the agent to an incident channel, test it with the following cases:
| Case | What to verify |
| -------------------------------------------- | ------------------------------------------------------------------------------------- |
| A service with known errors | The agent finds the relevant evidence for the intended service and time window. |
| A misspelled or ambiguous service | It resolves or asks about the service before drawing conclusions. |
| A service with logs but no traces | It uses the available signal and reports the trace gap. |
| An empty result | It distinguishes no matching records from a measured zero or a failed query. |
| A query timeout or execution limit | It returns an incomplete investigation with usable evidence and a next step. |
| A follow-up requesting a root cause analysis | It retains the incident window and verified findings. |
| A long prompt or rewritten follow-up | It preserves the full original request, service, environment, and comparison periods. |
| A recovery check | It queries a fresh window and checks successful activity as well as failures. |
Inspect the actual tool calls and results, not just the final wording. Use the [incident investigation guide](/docs/ai/investigate-an-incident/) to review the report an engineer will receive.
### Add remediation as a separate workflow
Once the investigation is useful, you can add a separately authorized action flow in your application. Show the proposed operation, target, and arguments to a person with permission to approve it. Record the execution result and verify the affected system afterward.
Keep the investigation report clear about who performed each action. Writing the report, proposing a fix, executing a change, and confirming recovery are separate outcomes.
Refer to [MCP for agents](/docs/ai/mcp-for-agents/) for connection examples or [Last9 MCP](/docs/ai/mcp/) for the tool reference.
***
## Troubleshooting
* **The agent cannot list any Last9 tools**
Check the organization slug in the MCP endpoint, and confirm the token is an MCP-type Client token from Query Tokens. Run one read query against a service you know has data.
* **A follow-up loses the incident details**
Store the service, environment, and time window with the conversation, separately from the model’s answer. Pass the stored record into each follow-up.
* **A filter returns no matches although the failures are present**
Have the agent call the discovery tools and build the filter from the returned field names. Two services can record the same value under different attributes.
* **A query times out and the report states a zero count**
Record the outcome of each query separately, then return the evidence already collected and the next useful check. Do not treat a timeout as a measured zero.
* **The agent calls a tool your workflow does not allow**
Maintain a list of permitted read tools in your application or MCP client, and check it when you expose or call a tool. A read-only instruction in the prompt is not an access control.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Collaboration mode
> Investigate incidents with teammates, share AI Assistant conversations within your organization, and manage access to Last9 AI.
Last9 AI is multiplayer in Slack: several engineers ask questions in the same thread, and the assistant answers all of them in that one investigation. An AI Assistant conversation in the dashboard is your own, and you can share it with a colleague in your Last9 organization to read.
Use a Slack thread when teammates need to ask questions together. Share an AI Assistant conversation when a colleague only needs to read the findings from your dashboard investigation.
What is shared, and what is not
A Slack thread is shared: every engineer in the channel asks the assistant in the same investigation. An [AI Assistant](/docs/ai/ai-assistant/) conversation is personal until you share it, and a shared link is read-only. An exception or dashboard analysis is personal and has no share link.
## Share an AI Assistant conversation
1. Open your conversation in [**AI Assistant**](https://app.last9.io/ai-assistant) and wait for the response to finish.
2. Click **Share** to create and copy a share link.
3. Send the link to a colleague in the same Last9 organization. Use **Copy link** to copy it again later.
4. To revoke access through the link, click **Unshare**, then confirm with **Unshare** in the dialog.
The shared view is read-only. A colleague can read the conversation, but cannot send messages or edit your chat through the link. The link opens the saved conversation, so later saved replies can appear when it is opened again.
Only the conversation owner can create or revoke its share link. Recipients must belong to the same Last9 organization, and the link does not provide public access.
## Investigate together in Slack
For installation, authorization, channel access, and troubleshooting, see [Use Last9 AI in Slack](/docs/ai/slack/). This section covers what changes once a team shares the thread.
Keep every question about one incident in the same thread, so each engineer gets answers with the same incident context. An engineer can start with the affected service and time window:
```text
@Last9 Investigate HTTP 5xx errors for checkout-api in production
between 14:00 and 14:30 UTC on 2026-09-10. Identify the affected
routes and include links to the supporting logs and traces.
```
A teammate can then add information or ask a follow-up in the same thread:
```text
@Last9 A deployment completed at 14:05 UTC. Check whether the
failure pattern changed after it. Keep the same service and
incident window, and explain what the evidence supports.
```
The assistant answers both engineers in that one investigation. Each teammate who queries Last9 through the app needs their own authorized Last9 account, with an email address matching their Slack account. A teammate without one can still read the thread.
Everyone reads the same answers, so state a fresh query window when you check recovery. An earlier answer in the thread describes the data queried at that time, not current health.
For evidence review and recovery checks, refer to [Investigate an incident with AI](/docs/ai/investigate-an-incident/).
### Use organization context
Last9 AI uses your organization’s configured skills, access to its telemetry, and tool permissions to investigate requests. It distinguishes reusable memory from conversation history: it reuses durable organization knowledge where that knowledge is configured, and keeps conversation history with the individual chat or incident thread.
An investigation message does not automatically become durable organization knowledge. Sharing a chat also does not combine its history with other dashboard conversations or Slack threads.
### Add runbooks and past incident knowledge
Your team can supply reviewed references for organization-specific skills to use during investigations. Useful references include service relationships, environment and region mappings, known error patterns, runbooks, and past root cause analyses (RCAs).
When configured, a skill reads the relevant reference during an investigation. Supplying a reference does not mean its full contents are included in every conversation.
1. Prepare the references your team wants Last9 AI to use. Keep confirmed findings separate from possible causes, and include supporting evidence.
2. Contact to configure the references and investigation skills for your organization. For an agent you manage yourself, refer to [Build your own AI SRE on Last9 data](/docs/ai/build-your-own-ai-sre/).
3. Test a question about a known incident. Ask the agent to identify the reference it used and check that the response matches the reviewed record.
4. Assign an owner to update each reference when services, runbooks, or findings change. After an update, repeat the test to confirm the agent can read the revised information.
For a past RCA, a short record can contain the following details. The format is illustrative and is not a Last9 API schema:
```markdown
# Incident title
- Incident window:
- Affected service and environment:
- Symptoms:
- Confirmed cause:
- Evidence:
- Action and outcome:
- Follow-up:
- Owner and review date:
```
Use a past RCA to guide what to check, then compare it with current telemetry. A similar error message does not establish the same cause. An investigation should identify the matching evidence, explain any differences, and report what remains unverified.
### Manage organization access
An organization admin controls AI access in [AI Settings](/docs/ai/#enable-last9-ai). Anyone with access to a Slack channel reads the answers posted there, so see [Channel access and shared information](/docs/ai/slack/#channel-access-and-shared-information) before you choose an incident channel.
Sharing findings does not approve a proposed change. Review any approval request in the interface where the action is proposed, and keep completed actions separate from recommendations in the incident report.
### Build a shared agent with Mithai
[Mithai](https://github.com/last9/mithai) is Last9’s open-source multiplayer agent harness for your organization. It powers Last9 AI, and it can also run an agent you build for your own workflows. Mithai keeps conversation history in sessions and reusable notes in memory. Its Slack adapter uses a separate session for each thread. See [Mithai core concepts](https://docs.mithai.dev/concepts/) for the session and memory model.
For a custom agent, decide which team facts belong in shared notes and which incident details should stay in the conversation. Configure the skills, tool permissions, model, and adapters the team needs. Mithai also supports multiple independent agents with separate skill sets and memory through its [multi-agent configuration](https://docs.mithai.dev/configuration/#agents-multi-agent-mode).
Preserve the agent’s memory and session storage across restarts, and review who can access both. The [deployment guide](https://docs.mithai.dev/deployment/) explains persistent storage, and the [security guide](https://docs.mithai.dev/security/) covers credentials, tool approvals, and channel access.
To connect a custom agent to Last9 telemetry, refer to [Build your own AI SRE on Last9 data](/docs/ai/build-your-own-ai-sre/).
***
## Troubleshooting
* **A colleague cannot open the share link**
Confirm that the person belongs to the same Last9 organization. If you revoked the link with **Unshare**, click **Share** to create a new one.
* **Share is unavailable in your conversation**
Wait for the response to finish. Only the conversation owner can create or revoke its share link.
* **`@Last9` does not reply in the incident channel**
Invite the app to the channel and mention `@Last9` in each follow-up. See [Slack troubleshooting](/docs/ai/slack/#troubleshooting) for the workspace connection.
* **A teammate’s question is not answered**
Check that their Slack email address matches their Last9 account email. Ask an organization admin to add the account.
* **An investigation does not use your runbook or past RCA**
Ask the agent to identify the reference it used. Contact to configure the references and investigation skills for your organization.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Investigate an incident with AI
> Investigate an affected service, inspect telemetry, test possible causes, and verify recovery with Last9 AI.
Use Last9 AI to gather evidence for an incident, test an explanation, and prepare a summary for your team. Start with the affected service and time window, and ask for the queries behind each conclusion. Verify recovery separately before closing the incident.
You can use the prompts below in [AI Assistant](/docs/ai/ai-assistant/), [Slack](/docs/ai/slack/), or an agent connected through [Last9 MCP](/docs/ai/mcp/). Available tools and approval controls depend on the interface and its configuration.
## Before you start
* Confirm that the relevant logs, metrics, or traces are available in Last9.
* Identify the service, environment, and data source you want to investigate. If you only know an application nickname, ask the assistant to find the matching service first.
* Record the incident’s start and end time, including the time zone. Use the same window when comparing results from different signals.
* Include an alert, request ID, trace ID, or error message when you have one.
## Run the investigation
Work through the following steps in order. Each step builds on the evidence the previous one returned.
### 1. Define the question
A question with a specific service and time window gives you a result you can check:
Investigate elevated HTTP 5xx responses for checkout-api in production between 14:00 and 14:30 UTC on 2026-09-10. Confirm the service and data source first. Summarize the affected routes, error counts, and latency. Include evidence links and identify any data you could not query.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Investigate%20elevated%20HTTP%205xx%20responses%20for%20checkout-api%20in%20production%0Abetween%2014%3A00%20and%2014%3A30%20UTC%20on%202026-09-10.%0A%0AConfirm%20the%20service%20and%20data%20source%20first.%20Summarize%20the%20affected%20routes%2C%0Aerror%20counts%2C%20and%20latency.%20Include%20evidence%20links%20and%20identify%20any%20data%0Ayou%20could%20not%20query.)
Replace the example service and time window with your incident details. If a query returns no data, verify the service and time window before concluding that the service is healthy.
### 2. Establish what happened
Ask for the symptom before the explanation:
Which requests failed in the incident window? Show the first and last observed failure, affected routes, status codes, and a representative request or trace ID. Distinguish total counts from sampled records.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Which%20requests%20failed%20in%20the%20incident%20window%3F%20Show%20the%20first%20and%20last%20observed%20failure%2C%20affected%20routes%2C%20status%20codes%2C%20and%20a%20representative%20request%20or%20trace%20ID.%20Distinguish%20total%20counts%20from%20sampled%20records.)
Open the returned links in [Logs Explorer](/docs/logs-explorer/), [Traces Explorer](/docs/traces-explorer/), or [Exceptions](/docs/discover-exceptions/). Check the service, filters, and time range against the question you asked.
Explain what each query result establishes:
| Evidence | What it establishes |
| -------------------------------- | ---------------------------------------------------------------------------------------------- |
| A failed request or exception | A specific failure was observed. |
| Error counts over a fixed window | The count shows how often a failure matched the query’s filters and time window. |
| A trace with related spans | The trace shows how an instrumented request moved through services and dependencies. |
| A sample of returned records | The sample shows what the selected records contain, but may not represent the full result set. |
| A query with no matches | The query returned no matching data. Check the filters, time window, and data availability. |
### 3. Test a possible cause
Ask the assistant to connect the symptom to evidence, and to describe what would disprove its explanation:
For the failing requests, check related traces and logs for a shared dependency or error pattern. Compare with successful requests in the same window. Separate confirmed findings from possible causes and list the missing evidence needed to distinguish them.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=For%20the%20failing%20requests%2C%20check%20related%20traces%20and%20logs%20for%20a%20shared%20dependency%20or%20error%20pattern.%20Compare%20with%20successful%20requests%20in%20the%20same%20window.%20Separate%20confirmed%20findings%20from%20possible%20causes%20and%20list%20the%20missing%20evidence%20needed%20to%20distinguish%20them.)
If [change events](/docs/change-events/) are available, compare the incident with deployments and configuration changes. Investigate any deployment near the incident, but do not treat timing alone as proof of a cause.
For latency, ask which spans account for the delay and compare similar successful or faster requests. For errors, inspect the failing operation and its related logs. Report any missing dependency instrumentation or correlation IDs in the conclusion.
### 4. Verify recovery in a new window
An incident summary describes the data already queried. It does not establish the system’s current condition.
Recheck checkout-api in production for the last 15 minutes. State the exact window you query. Are requests succeeding under normal traffic? Compare error rate and latency with the incident window, and say whether the evidence supports recovery.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Recheck%20checkout-api%20in%20production%20for%20the%20last%2015%20minutes.%20State%20the%20exact%20window%20you%20query.%20Are%20requests%20succeeding%20under%20normal%20traffic%3F%20Compare%20error%20rate%20and%20latency%20with%20the%20incident%20window%2C%20and%20say%20whether%20the%20evidence%20supports%20recovery.)
Check for successful activity as well as fewer errors. A quiet service may have no errors because it received no traffic. A single successful retry confirms that request succeeded, but leaves sustained recovery unverified.
### 5. Prepare the handoff
A handoff is a summary another engineer can use to continue the investigation. Ask the assistant to include the findings, completed actions, and remaining questions:
Write an incident handoff with: - Affected services, environments, and exact time windows. - Confirmed findings and their evidence links. - Most likely explanation, supporting evidence, and remaining uncertainty. - Actions actually taken, who took them, and what remains to do. - Latest recovery check and any follow-up validation needed. Do not describe a proposed action as completed or a possible cause as confirmed.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Write%20an%20incident%20handoff%20with%3A%0A-%20Affected%20services%2C%20environments%2C%20and%20exact%20time%20windows.%0A-%20Confirmed%20findings%20and%20their%20evidence%20links.%0A-%20Most%20likely%20explanation%2C%20supporting%20evidence%2C%20and%20remaining%20uncertainty.%0A-%20Actions%20actually%20taken%2C%20who%20took%20them%2C%20and%20what%20remains%20to%20do.%0A-%20Latest%20recovery%20check%20and%20any%20follow-up%20validation%20needed.%0A%0ADo%20not%20describe%20a%20proposed%20action%20as%20completed%20or%20a%20possible%20cause%0Aas%20confirmed.)
Review any proposed change before approving it in your client. For example, creating or updating a dashboard changes saved configuration. An investigation recommendation does not mean the assistant has applied a fix.
## Examples from incident investigations
The examples below are adapted from incident investigations. Names and details are changed, and the prompts are illustrative.
### An outage question followed by an RCA request
Operators use Last9 AI to ask about service health, p95 latency, recent errors, and outages, then request a root cause analysis (RCA). In one outage investigation, the assistant queried several signals but stopped at its investigation limit without enough matching telemetry to establish a cause.
Before writing an RCA from an incomplete answer, ask which evidence is missing:
Before writing the RCA, list which queries returned evidence, which found no matching data, and which could not complete. Confirm the service, environment, and incident window. What is the next targeted check that could establish the cause?
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Before%20writing%20the%20RCA%2C%20list%20which%20queries%20returned%20evidence%2C%20which%20found%20no%20matching%20data%2C%20and%20which%20could%20not%20complete.%20Confirm%20the%20service%2C%20environment%2C%20and%20incident%20window.%20What%20is%20the%20next%20targeted%20check%20that%20could%20establish%20the%20cause%3F)
An incomplete investigation can still identify the next check. Its unanswered questions belong in the handoff.
### An API failure with an unconfirmed downstream cause
An investigation located a failed request and a later successful, slower request. The engineer corrected the service name during the investigation. The available evidence confirmed the failure but did not establish which downstream component caused it.
Use a follow-up that asks for the missing connection:
Use the corrected service name and the same incident window. Can you connect the failed request to a downstream trace or log using its request ID? If the records cannot be connected, explain what we can confirm and what evidence we still need.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Use%20the%20corrected%20service%20name%20and%20the%20same%20incident%20window.%20Can%20you%20connect%20the%20failed%20request%20to%20a%20downstream%20trace%20or%20log%20using%20its%20request%20ID%3F%20If%20the%20records%20cannot%20be%20connected%2C%20explain%20what%20we%20can%20confirm%20and%20what%20evidence%20we%20still%20need.)
The summary should describe the observed failure, verified service and time window, and next evidence to collect. The available data did not support a confirmed cause.
### A large query result and an unresponsive browser
An engineer reproduced a query through MCP and inspected a small sample of large records. The assistant initially confused the sizes of log records with the size of the HTTP response, then corrected its interpretation.
Use a follow-up that separates measurements from estimates:
Separate the result count, sizes of sampled records, estimated total size, and measured HTTP response size. Label each as measured, estimated, or unknown. What would we need to measure to determine whether the response caused the browser to become unresponsive?
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Separate%20the%20result%20count%2C%20sizes%20of%20sampled%20records%2C%20estimated%20total%20size%2C%20and%20measured%20HTTP%20response%20size.%20Label%20each%20as%20measured%2C%20estimated%2C%20or%20unknown.%20What%20would%20we%20need%20to%20measure%20to%20determine%20whether%20the%20response%20caused%20the%20browser%20to%20become%20unresponsive%3F)
Large sampled records can justify measuring the response size. To establish why the browser became unresponsive, collect evidence from the response and the browser itself.
### A notification incident ready for handoff
Before accepting an RCA summary, an engineer asked whether the problem was still occurring. The assistant queried a fresh window and checked successful deliveries and HTTP responses. Engineers performed the remediation separately.
Use a follow-up that requires a current check:
Before finalizing the RCA, check whether deliveries are succeeding now. State the new query window and show success and failure evidence. Update the status based on the new results and keep the engineer's completed actions separate from proposed follow-ups.
[Open as draft in AI Assistant ](https://app.last9.io/ai-assistant?draft=Before%20finalizing%20the%20RCA%2C%20check%20whether%20deliveries%20are%20succeeding%20now.%20State%20the%20new%20query%20window%20and%20show%20success%20and%20failure%20evidence.%20Update%20the%20status%20based%20on%20the%20new%20results%20and%20keep%20the%20engineer's%20completed%20actions%20separate%20from%20proposed%20follow-ups.)
***
## Troubleshooting
| Symptom | Next step |
| -------------------------------- | -------------------------------------------------------------------------------------------------------------------------- |
| The service cannot be found | Ask for matching service names; confirm environment and data source. |
| Queries return no matches | Check the time zone, retention, filters, and whether that signal is being ingested. |
| Logs and traces disagree | Align their time windows and filters; check whether a count covers requests, spans, or log records. |
| A response shows only a sample | Ask for a count of all matching records or use more specific filters before drawing conclusions about the full result set. |
| A tool fails or access is denied | Resolve the query or access issue, then rerun it. Keep that signal marked as unverified. |
| A possible cause lacks evidence | Ask what observation would confirm or reject it; collect that evidence before closing the RCA. |
For connection problems, see [Slack troubleshooting](/docs/ai/slack/#troubleshooting) or [MCP troubleshooting](/docs/ai/mcp/#troubleshooting).
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Last9 MCP
> Connect your AI client to Last9 logs, traces, metrics, alerts, and dashboards through MCP.
Last9’s MCP server lets your AI assistant query production telemetry from your IDE. Ask questions such as “What’s causing the recent spike in errors?” or “Show me the slowest endpoints from the last hour”, then open the supporting Last9 data from the response.
Use [AI Assistant](/docs/ai/ai-assistant/) for chat in Last9 or [agent skills](/docs/ai/agent-skills/) for instructions your coding agent can follow. To connect your own bot or investigation service, see [Build your own AI SRE](/docs/ai/build-your-own-ai-sre/).
## What is Model Context Protocol?
[MCP](https://modelcontextprotocol.io/introduction) is an open protocol for connecting AI applications to tools and data sources.
Last9 MCP exposes tools to query telemetry, inspect service dependencies, review alerts, and manage dashboards. Your client chooses which tools to call and uses their results to answer your question.
Note
Last9 MCP provides the tools, and your AI client or agent controls which calls need confirmation. Review its tool permissions before enabling actions such as creating, updating, or deleting dashboards.
## Why use Last9 MCP?
Connect Last9 MCP to investigate production behavior alongside your code:
* Query the logs and traces for a failing request.
* Compare service latency, errors, and dependencies over a specific time window.
* Give a coding agent evidence to use when proposing a fix.
Start with the service, environment, and incident window. For a complete investigation workflow, see [Investigate an incident](/docs/ai/investigate-an-incident/).
## Example use cases
### Debug production exceptions
```plaintext
"I'm seeing errors in production. Can you help me understand what's happening?"
```
*Agent uses `get_exceptions` and `get_service_performance_details` to analyze the issue*
### Performance investigation
```plaintext
"My API response times seem slow. What's causing the latency?"
```
*Agent uses `get_service_dependency_graph` and `prometheus_range_query` to identify bottlenecks*
### Trace waterfall analysis
```plaintext
"I have a slow trace ID. Show me where the time is going."
```
*Agent uses `get_trace_waterfall` to return a bounded parent/child waterfall with millisecond timing, self-time, and the slowest spans*
### Compare slow vs fast spans
```plaintext
"What attributes differ between slow and fast requests on checkout-service?"
```
*Agent uses `get_trace_attribute_deviations` with `comparison_mode: latency` to rank attribute values that correlate with slow spans*
### Detect performance regressions
```plaintext
"What services regressed in the last hour compared to the previous hour?"
```
*Agent uses `get_apm_service_deviations` to compare the current window against an equal-duration baseline and return regressions/improvements leaderboards*
### Log analysis for issues
```plaintext
"Find error logs from the user-service in the last 30 minutes"
```
The agent can use `get_service_logs` to read service log lines, or `get_logs` with a LogJSON pipeline to filter and aggregate them.
### Correlate incidents with deployments
```plaintext
"We had performance issues around 2pm. Were there any deployments around that time?"
```
*Agent uses `get_change_events` to check for recent deployments and `get_service_performance_details` to analyze the correlation*
### Database performance investigation
```plaintext
"Which databases are my services hitting, and what are the slowest PostgreSQL queries in prod right now?"
```
*Agent uses `get_databases`, `get_database_queries`, `get_database_slow_queries`, and `get_database_server_metrics` to connect database load, slow queries, and exporter-backed server health*
### Auto-correct typos in entity names
```plaintext
"Can you look up last9-apiii logs"
```
The agent can use `did_you_mean` to suggest matching entity names. Confirm the intended service before querying its logs.
## Prerequisites
Before setting up Last9 MCP, ensure you have:
* Telemetry flowing to your Last9 organization.
* One of the supported clients: Claude Code, Cursor, VS Code, Windsurf, Claude.ai / Claude Desktop, Codex CLI, or ChatGPT
* A Last9 account with access to the organization you want to query. Check your connection settings on the [MCP](https://app.last9.io/mcp) page in Last9.
## Setup
Recommended: use the hosted MCP server
Connect to `https://app.last9.io/api/v4/organizations//mcp` and authorize access with your Last9 account. The hosted server requires no local binary. For your own application, see [MCP for agents](/docs/ai/mcp-for-agents/).
1. **Find your organization slug**
Your org slug is in your Last9 URL when logged in:
```plaintext
https://app.last9.io/v2/organizations//...
```
For example, if your URL contains `/v2/organizations/acme/`, your slug is `acme`.
2. **Configure your IDE**
Choose your client below, replace ``, and complete its OAuth sign-in flow.
* Claude Code
1. Run the following command to add the Last9 MCP server:
```bash
claude mcp add --transport http last9 "https://app.last9.io/api/v4/organizations//mcp"
```
2. Replace `` with your organization slug
3. Type `/mcp` in Claude Code, select the **last9** server, and authenticate
4. After authorizing, check the server’s available tools in your session.
* Cursor
1. Open Cursor → **Settings** → **Cursor Settings** → **MCP**
2. Click **Add New MCP Server**
3. Add the configuration:
```json
{
"mcpServers": {
"last9": {
"type": "http",
"url": "https://app.last9.io/api/v4/organizations//mcp"
}
}
}
```
4. Replace `` with your organization slug
5. Save, then select **Connect** for the server.
6. Click **Connect** → a browser window opens → authorize with your Last9 account
* VS Code
See the [VS Code MCP documentation](https://code.visualstudio.com/docs/agent-customization/mcp-servers) for client settings and permissions.
1. Open the Command Palette (`cmd+shift+P` on macOS / `ctrl+shift+P` on Windows/Linux)
2. Select **MCP: Add Server** → choose **HTTP** as the type
3. Paste the server URL with your organization slug:
```plaintext
https://app.last9.io/api/v4/organizations//mcp
```
4. Enter `last9` as the server name
5. Choose **Global** or **Workspace** scope
6. Complete the OAuth sign-in flow in your browser when VS Code prompts you.
* Windsurf
1. Open Windsurf → **Settings** → **Cascade** → click **Open MCP Marketplace**
2. Click the gear icon (⚙) to open `mcp_config.json`
3. Add the Last9 MCP server configuration:
```json
{
"mcpServers": {
"last9": {
"serverUrl": "https://app.last9.io/api/v4/organizations//mcp"
}
}
}
```
4. Replace `` with your organization slug
5. Save the file and follow Windsurf’s authentication prompt.
6. Complete the OAuth flow in your browser to authorize Last9 access
* Claude.ai / Claude Desktop
> **Note:** Admin access to your Claude organization is required to add custom connectors. For more details, see the [Claude custom connectors guide](https://support.claude.com/en/articles/11175166-get-started-with-custom-connectors-using-remote-mcp).
1. Go to **Settings** → **Connectors** → click **Add custom connector**
2. Enter `last9` as the **Name**
3. Paste the **Remote MCP server URL** with your organization slug:
```plaintext
https://app.last9.io/api/v4/organizations//mcp
```
4. Click **Add**
5. Go to **Customize** → **Connectors** → select **last9** under “Not connected”
6. Click **Connect** and complete the OAuth flow in your browser
* Codex CLI
**Option A: CLI commands**
```bash
codex mcp add last9 --url "https://app.last9.io/api/v4/organizations//mcp"
codex mcp login last9
```
**Option B: manual config** in `~/.codex/config.toml`:
```toml
[mcp_servers.last9]
url = "https://app.last9.io/api/v4/organizations//mcp"
```
Replace `` with your organization slug. After saving manual configuration, run `codex mcp login last9` to authorize access. See the [Codex MCP documentation](https://developers.openai.com/codex/mcp).
* ChatGPT
Use a ChatGPT web workspace that supports custom MCP apps. Your workspace administrator may need to enable developer mode. Check [ChatGPT developer mode availability and permissions](https://help.openai.com/en/articles/12584461-developer-mode-and-full-mcp-connectors-in-chatgpt-beta).
1. **Enable Developer Mode**
Go to **Settings** → **Apps** → **Advanced settings** and enable **Developer mode**, where available.
2. **Create an app**
Go to **Settings** → **Apps** and click **Create**.
3. Enter the app details:
* **Name:** `Last9`
* **Description:** `Query Last9 logs, traces, metrics, alerts, and deployments`
* **MCP server URL:**
```plaintext
https://app.last9.io/api/v4/organizations//mcp
```
Replace `` with your organization slug.
4. Select OAuth authentication, complete the Last9 sign-in flow, and use **Scan Tools** to review the available tools. Finish creating the app.
5. Select the app in the conversation where you want to use it. Try: “What exceptions occurred in the last hour?” Review any tool confirmation requests before proceeding.
3. **Verify the connection**
Once configured, your AI agent will have access to Last9 tools. Try asking: *“What exceptions occurred in the last hour?”* or *“Show me the performance summary for my services.”*
## Using Last9 MCP with OpenAI’s Responses API
Connect the Responses API to the hosted Last9 MCP endpoint. The example below permits only two read tools and skips approval for those tools. Set `OPENAI_MODEL` to a model that supports remote MCP, `LAST9_ORG_SLUG` to your organization slug, and `LAST9_MCP_TOKEN` to an [MCP client token](/docs/ai/mcp-for-agents/#get-an-mcp-token).
```python
import os
from openai import OpenAI
client = OpenAI()
response = client.responses.create(
model=os.environ["OPENAI_MODEL"],
tools=[
{
"type": "mcp",
"server_label": "last9",
"server_url": (
"https://app.last9.io/api/v4/organizations/"
f"{os.environ['LAST9_ORG_SLUG']}/mcp"
),
"authorization": os.environ["LAST9_MCP_TOKEN"],
"allowed_tools": ["get_service_profile", "get_service_logs"],
"require_approval": "never",
}
],
input=(
"Inspect payment-service errors in production over the last 15 minutes. "
"Read its service profile and relevant log lines. "
"Summarize the evidence and any missing information."
),
)
print(response.output_text)
```
Keep the allowlist specific to your task. To require approval, handle the API’s `mcp_approval_request` response before continuing the tool call. See the [OpenAI remote MCP guide](https://developers.openai.com/api/docs/guides/tools-connectors-mcp) for authentication, tool filters, and approval handling.
## Advanced: Self-hosting the MCP server
Run the open-source server locally when you need to manage its process or choose which toolsets it exposes. The server still needs network access to Last9.
**Install:**
```bash
# Homebrew (macOS/Linux)
brew tap last9/tap && brew install last9-mcp
# NPM (cross-platform, including Windows)
npm install -g @last9/mcp-server@latest
```
You can also download platform-specific binaries from [GitHub Releases](https://github.com/last9/last9-mcp-server/releases/latest).
**Get a Refresh Token** (admin required) from [API Access](https://app.last9.io/settings/api-access).
Tip
**One token per developer.** Create a separate refresh token for each individual developer rather than sharing one token across the team. This gives you a clear audit trail and lets you revoke access for a specific person without affecting others.
**Configure your IDE** using the local binary path and `LAST9_REFRESH_TOKEN`:
```json
{
"mcpServers": {
"last9": {
"command": "/opt/homebrew/bin/last9-mcp",
"env": {
"LAST9_REFRESH_TOKEN": ""
}
}
}
}
```
For VS Code’s `.vscode/mcp.json`, use a top-level `"servers"` object keyed by `"last9"`, with `"type": "stdio"`, `"command"`, and `"env"` inside it. See the [VS Code configuration reference](https://code.visualstudio.com/docs/agents/reference/mcp-configuration) and [Last9 MCP server README](https://github.com/last9/last9-mcp-server) for configuration options.
**Toolsets (optional).** By default the server exposes every tool. For automation hosts that only need investigation workflows, set `LAST9_TOOLSETS` (alias `LAST9_MCP_TOOLSETS`) or pass `--toolsets` to limit what appears in `tools/list`:
```json
{
"mcpServers": {
"last9": {
"command": "/opt/homebrew/bin/last9-mcp",
"env": {
"LAST9_REFRESH_TOKEN": "",
"LAST9_TOOLSETS": "investigate"
}
}
}
}
```
Valid toolset names are `logs`, `traces`, `metrics`, `alerts`, `dashboards`, `investigate`, and `all`. Use a comma-separated list. An unset or empty value, or `all`, exposes every tool. Unknown names stop the server at startup. The `investigate` toolset includes logs, traces, metrics, and the discovery tools `did_you_mean`, `get_service_profile`, and `list_datasources`.
**Reference resources.** The server provides five resources: `last9://reference/logjson`, `last9://reference/tracejson`, `last9://reference/service_logs`, `last9://reference/metrics`, and `last9://reference/investigation`. Clients that support MCP resources can discover and read them through `resources/list` and `resources/read`. Tool descriptions include essential query rules. Discover your organization’s field names with `get_log_attributes_for_pipeline` and `get_trace_attributes_for_pipeline`.
Clients that support MCP prompts can discover six guided investigation prompts through `prompts/list`: `scoped-log-attribute-discovery`, `exception-root-cause-investigation`, `investigate-latency-spike`, `diagnose-error-rate`, `analyze-slow-queries`, and `on-call-runbook`. Check the returned prompt definition for its required inputs.
## Available tools
The reference below describes Last9 MCP tools. Availability and parameters depend on your connected server version and configuration. Inspect `tools/list` for its current schemas.
### Observability & APM
1. **`get_exceptions`**: Get server-side exceptions over a specified time range. For log-heavy services, the tool may continue to logs via aggregate-then-read: aggregate to isolate the hot logger, then read that logger’s lines with a `limit` to reach the error text.
View parameters
* `limit` (integer, optional): Maximum number of exceptions to return. Default: 20
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format. Leave empty to use lookback\_minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Leave empty to default to current time
* `service_name` (string, optional): Filter by service name
* `span_name` (string, optional): Name of the span to filter by
* `env` (string, optional): Filter by environment
2. **`get_service_summary`**: Rank services using request counts, requests per minute, and HTTP or gRPC error counts over a time window.
View parameters
* `lookback_minutes` (integer, optional): Number of minutes to look back. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: end\_time\_iso - 1 hour
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
* `env` (string, optional): Environment regex. Default: `.*`
* `sort_by` (string, optional): Ranking field; use the connected tool schema for supported values
* `limit` (integer, optional): Maximum number of services to return
3. **`get_service_environments`**: Get available service environments within a specified time range.
View parameters
* `service_name` (string, optional): Service to find environments for
* `lookback_minutes` (integer, optional): Number of minutes to look back. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: now - 60 minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
Returns available environments for use with other APM tools.
4. **`get_service_performance_details`**: Get detailed performance metrics for a specific service.
View parameters
* `service_name` (string, required): Service name
* `lookback_minutes` (integer, optional): Number of minutes to look back. Default: 60
* `top_n` (integer, optional): Number of results. Default: 10; maximum: 100
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: Now - 60 minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
* `env` (string, optional): Environment filter. Default: `.*`
5. **`get_service_operations_summary`**: Get operations summary for a service like HTTP endpoints, database queries, messaging producer, and HTTP client calls.
View parameters
* `service_name` (string, required): Service name
* `lookback_minutes` (integer, optional): Number of minutes to look back. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: Now - 60 minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
* `env` (string, optional): Environment filter. Default: `.*`
6. **`get_service_dependency_graph`**: Get service dependency graph showing incoming and outgoing dependencies, including infra. Includes throughput, response times and error rates.
View parameters
* `service_name` (string, optional): Name of the service
* `lookback_minutes` (integer, optional): Number of minutes to look back. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: now - 60 minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
* `env` (string, optional): Environment filter. Default: `.*`
7. **`get_change_events`**: Retrieves change events from the `last9_change_events` Prometheus metric to help correlate deployments and system modifications with performance issues or incidents.
View parameters
* `start_time_iso` (string, optional): Start time in RFC3339 format. Defaults to now - lookback\_minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Defaults to current time
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60
* `service_name` (string, optional): Filter by service name
* `env` (string, optional): Environment filter
* `event_name` (string, optional): Specific event type filter (use available\_event\_names to see valid values)
**Returns**:
* `available_event_names`: List of all available event types that can be used for filtering
* `change_events`: Array of timeseries data with metric labels and timestamp-value pairs
* `count`: Total number of change events returned
* `time_range`: Start and end time of the query window
**Common event types**: deployment, config\_change, rollback, scale\_up/scale\_down, restart, upgrade/downgrade, maintenance, backup/restore, health\_check, certificate, database
**Best practices**:
1. First call without event\_name to get available\_event\_names
2. Use exact event name from available\_event\_names for the event\_name parameter
3. Combine with other filters (service\_name, env, time) for precise results
8. **`get_apm_service_deviations`**: Compare APM performance across a current window and an equal-duration baseline. Use for regressions/improvements, incident-vs-prior-period comparisons, and fleet deviation discovery.
View parameters
* `service_name` (string, optional): Omit for fleet scope; provide for one service and its operation correlations
* `env` (string, optional): Filter to one deployment environment
* `lookback_minutes` (integer, optional): Current window length ending now. Default: 60
* `start_time_iso` / `end_time_iso` (string, optional): Explicit current window
* `baseline_start_time_iso` / `baseline_end_time_iso` (string, optional): Equal-duration baseline window; defaults to the immediately preceding period
* `datasource` (string, optional): Select one datasource for the comparison
* `max_services` / `max_operations` (integer, optional): Default: 10, maximum: 10
**Returns**: `regressions` and `improvements` leaderboards, `evidence_quality`, Apdex reconciliation, and a terminal `outcome`. Treat `stable`, `no_data`, and `unsupported_workload_shape` as terminal — answer from the result without automatic follow-up tool calls. V1 supports server-request workloads.
### Database investigation
1. **`get_databases`**: Discover databases from available telemetry. Trace-derived results include database type, host, throughput, p95 latency, error rate, and service counts. Connected servers that support infrastructure or CloudWatch metric discovery can also return databases found through those signals. Metric-only results may not include trace latency or throughput.
View parameters
* `env` (string, optional): Environment regex, such as `prod|staging`
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60; current server limits the window to seven days
* `start_time_iso` (string, optional): Start time in RFC3339 format. Overrides lookback\_minutes
* `end_time_iso` (string, optional): End time in RFC3339 format
**Useful for**:
* Discovering which databases your services are talking to
* Ranking database backends by throughput, latency, and error rate
* Identifying shared databases used by many services
2. **`get_database_slow_queries`**: Find the slowest database operations from traces and, when available, slow-query logs. Results are sorted by duration descending.
View parameters
* `db_system` (string, optional): Database system filter such as `postgresql`, `mysql`, `mongodb`, or `redis`
* `host` (string, optional): Database host filter using `net_peer_name`
* `service_name` (string, optional): Calling service name filter
* `env` (string, optional): Deployment environment filter
* `min_duration_ms` (number, optional): Minimum query duration in milliseconds
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format
* `end_time_iso` (string, optional): End time in RFC3339 format
* `limit` (integer, optional): Maximum number of slow queries to return. Default: 20
**Returns**:
* Query source (`trace` or `log`)
* Trace and span IDs when available
* Service name, database system, query pattern or statement, duration, status, and timestamp
* Slow-query metadata from logs such as plan summaries or rows examined when present
3. **`get_database_queries`**: Get the top query patterns for a specific database, aggregated by operation. Helps identify hot, slow, or error-prone query shapes.
View parameters
* `db_system` (string, required): Database system such as `postgresql`, `mysql`, `mongodb`, or `redis`
* `host` (string, optional): Database host filter using `net_peer_name`
* `env` (string, optional): Deployment environment filter
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format
* `end_time_iso` (string, optional): End time in RFC3339 format
* `sort_by` (string, optional): Sort by `throughput` (default), `latency`, or `errors`
**Returns**:
* `span_name`
* `calls_per_min`
* `avg_latency_ms`
* `p95_latency_ms`
* `error_rate_pct`
4. **`get_database_server_metrics`**: Discover server-side database metrics from exporters and query key health signals such as connection utilization, cache hit ratios, replication lag, and throughput.
View parameters
* `db_system` (string, optional): Focus on a specific database type. Supported values: `postgresql`, `mysql`, `oracle`, `redis`, `mongodb`, `mssql`, `elasticsearch`, `aerospike`
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60
* `start_time_iso` (string, optional): Start time in RFC3339 format
* `end_time_iso` (string, optional): End time in RFC3339 format
**Notes**:
* If `db_system` is omitted, the tool auto-discovers available exporters
* Requires database exporters such as `postgres_exporter`, `mysqld_exporter`, `redis_exporter`, or `mongodb_exporter` to be scraped into Prometheus or Levitate
* Complements client-side trace data with server-side health metrics
### Prometheus integration
1. **`list_datasources`**: List all available datasources configured for your organization. Use this before Prometheus queries to discover valid datasource names.
Returns
* Array of datasource objects, each with:
* `name`: datasource identifier to pass via the `datasource` parameter in Prometheus tools
* `is_default`: `true` for the datasource used when no `datasource` is specified
2. **`prometheus_range_query`**: Execute Prometheus range queries for metrics over a time period.
View parameters
* `query` (string, required): Range query to execute
* `lookback_minutes` (integer, optional): Window ending now when absolute bounds are omitted
* `datasource` (string, optional): Datasource name from `list_datasources`
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: now - 60 minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
3. **`prometheus_instant_query`**: Execute Prometheus instant queries for metrics at a specific point in time.
View parameters
* `query` (string, required): Instant query to execute
* `lookback_minutes` (integer, optional): Minutes before now to evaluate when `time_iso` is omitted
* `datasource` (string, optional): Datasource name from `list_datasources`
* `time_iso` (string, optional): Time in RFC3339 format. Default: Current time
4. **`prometheus_label_values`**: Get all label values for a specific label name.
View parameters
* `match_query` (string, required): Valid PromQL filter query
* `label` (string, required): Label to get values for
* `lookback_minutes` (integer, optional): Window ending now when absolute bounds are omitted
* `datasource` (string, optional): Datasource name from `list_datasources`
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: now - 60 minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
5. **`prometheus_labels`**: Get all available label names.
View parameters
* `match_query` (string, required): Valid PromQL filter query
* `lookback_minutes` (integer, optional): Window ending now when absolute bounds are omitted
* `datasource` (string, optional): Datasource name from `list_datasources`
* `start_time_iso` (string, optional): Start time in RFC3339 format. Default: now - 60 minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Default: Current time
### Log management
1. **`get_logs`**: Runs a LogJSON pipeline to filter, transform, or aggregate logs. Use `get_service_logs` for raw service log lines.
View parameters
* `logjson_query` (array, required): LogJSON pipeline. Read `last9://reference/logjson` for query syntax
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 5
* `start_time_iso` (string, optional): Start time in RFC3339/ISO 8601 format. Use with `end_time_iso` for an absolute time range
* `end_time_iso` (string, optional): End time in RFC3339/ISO 8601 format. Use with `start_time_iso` for an absolute time range
* `limit` (integer, optional): Result limit. Defaults depend on the pipeline shape and the server’s configured cap
* `index` (string, optional): `physical_index:` or `rehydration_index:`
2. **`get_service_logs`**: Retrieves raw log entries for a specific service with advanced filtering capabilities. Useful for debugging issues, monitoring service behavior, and analyzing specific log patterns.
Additional filters include `http_status_class`, `http_status_code`, `http_status_field`, `attribute_filters`, and `index`. Use status-class filtering for groups such as 4xx or 5xx; check the connected schema for accepted values.
View parameters
* `service_name` (string, required): Name of the service to get logs for
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60
* `limit` (integer, optional): Maximum log entries to return. Default: 20
* `env` (string, optional): Environment to filter by. Use `get_service_environments` to get available environments
* `severity_filters` (array, optional): Filter by log severity levels (e.g., `["error", "warn"]`). Uses OR logic
* `body_filters` (array, optional): Filter by log message content (e.g., `["timeout", "failed"]`). Uses OR logic
* `start_time_iso` (string, optional): Start time in RFC3339 format
* `end_time_iso` (string, optional): End time in RFC3339 format
**Filtering behavior:**
* Multiple filter types are combined with AND logic (service AND severity AND body)
* Each filter array uses OR logic (matches any pattern in the array)
3. **`get_drop_rules`**: Gets drop rules for logs, which determine what logs get filtered out from reaching Last9.
4. **`add_drop_rule`**: Adds a new drop rule to filter out specific logs at Last9 Control Plane
View parameters
* `name` (string, required): Name of the drop rule
* `filters` (array, required): List of filter conditions to apply. Each filter has:
* `key` (string, required): The key to filter on. Only attributes and resource.attributes keys are supported. For resource attributes, use format: `resource.attributes[key_name]` and for log attributes, use format: `attributes[key_name]`. Double quotes in key names must be escaped
* `value` (string, required): The value to filter against
* `operator` (string, required): The operator used for filtering. Valid values: “equals”, “not\_equals”
* `conjunction` (string, required): The logical conjunction with the other filters. Valid values: “and”
5. **`get_log_attributes`**: Returns available log attribute names existing during the specified time window, grouped by category. Useful for discovering what attributes can be used for filtering and querying logs.
View parameters
* `lookback_minutes` (integer, optional): Number of minutes to look back from now for the time window. Default: 15
* `start_time_iso` (string, optional): Start time in RFC3339 format. Leave empty to use lookback\_minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Leave empty to default to current time
* `region` (string, optional): AWS region to query. Leave empty to use default from configuration
* `index` (string, optional): `physical_index:` or `rehydration_index:`
**Returns**: Log attributes grouped into two categories:
* Log Attributes: Standard log fields like service, severity, body, level, etc.
* Resource Attributes: Resource-related fields prefixed with “resource\_” like resource\_k8s.pod.name, resource\_service.name, etc.
6. **`get_log_attributes_for_pipeline`**: Returns log fields present after applying a pipeline, each with the exact `filter_field` for `get_logs` conditions. Scoped to your pipeline — use after a filter stage and before building `get_logs` queries.
View parameters
* `pipeline` (array, required): In-progress pipeline, such as a `ServiceName` filter stage
* `lookback_minutes` (integer, optional): Default: 15
* `start_time_iso` / `end_time_iso` (string, optional): RFC3339 time bounds
* `region` (string, optional): Region to query
* `index` (string, optional): `physical_index:` or `rehydration_index:`
**Returns**: Each entry includes `name`, `filter_field` (use directly in `get_logs`), `hint`, and optional `source`/`sample_coverage`. Body-derived fields (`source: body`) require a parse stage before filtering.
### Traces management
1. **`get_traces`**: Execute advanced trace queries using JSON pipeline syntax for complex filtering and aggregation. This tool provides powerful querying capabilities for traces using a pipeline-based approach with filters, aggregations, and transformations.
View parameters
* `tracejson_query` (array, required): JSON pipeline query for traces. Fetch the full DSL from the `last9://reference/tracejson` resource or discover fields with `get_trace_attributes_for_pipeline` first
* `start_time_iso` (string, optional): Start time in RFC3339 format
* `end_time_iso` (string, optional): End time in RFC3339 format
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 60
* `limit` (integer, optional): Maximum number of results to return. Default: 5000
**Notes:**
* Existence checks use `{"$neq": [field, ""]}` — `$exists` and `$notnull` are not supported
* `aggregate` and `window_aggregate` pipelines run as a single request (not chunked)
* A `408` response means the window is too wide — narrow the time range and retry
2. **`get_service_traces`**: Retrieve traces from Last9 by trace ID or service name. Get specific traces either by providing a trace ID for a single trace, or by providing a service name to get all traces for that service within a time range.
View parameters
* `trace_id` (string, optional): Specific trace ID to retrieve. Cannot be used with service\_name
* `service_name` (string, optional): Name of service to get traces for. Cannot be used with trace\_id
* `lookback_minutes` (integer, optional): Number of minutes to look back from now. Default: 4320 for `trace_id`, 60 for `service_name`
* `start_time_iso` (string, optional): Start time in RFC3339 format. Leave empty to use lookback\_minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Leave empty to default to current time
* `limit` (integer, optional): Maximum number of traces to return. Default: 10
* `env` (string, optional): Environment filter. Use `get_service_environments` to get available environments
**Usage rules:**
* Exactly one of `trace_id` or `service_name` must be provided (not both, not neither)
* Use `lookback_minutes` or ISO time bounds with either lookup. ISO bounds override `lookback_minutes`
Returns trace data including trace IDs, spans, duration, timestamps, and status information.
3. **`get_trace_attributes`**: Identify all available trace attributes within a specified time window for use in filtering and querying. Returns the global tag catalog.
View parameters
* `lookback_minutes` (integer, optional): Number of minutes to look back from now for the time window. Default: 15
* `start_time_iso` (string, optional): Start time in RFC3339 format. Leave empty to use lookback\_minutes
* `end_time_iso` (string, optional): End time in RFC3339 format. Leave empty to default to current time
* `region` (string, optional): AWS region to query. Leave empty to use default from configuration
4. **`get_trace_attributes_for_pipeline`**: Returns trace attributes present after applying a pipeline, each with the exact `filter_field` for `get_traces` conditions. Scoped to your pipeline — use after a filter stage and before filtering on attribute keys.
View parameters
* `pipeline` (array, required): In-progress pipeline, such as a `ServiceName` filter stage
* `lookback_minutes` (integer, optional): Default: 15
* `start_time_iso` / `end_time_iso` (string, optional): RFC3339 time bounds
* `region` (string, optional): Region to query
**Returns**: Each entry includes `name`, `semantic_name`, `type`, and `filter_field` ready to use in `get_traces` conditions.
5. **`get_trace_attribute_values`**: Fetch distinct values for a single trace attribute. Use after `get_trace_attributes` or `get_trace_attributes_for_pipeline` to see what values exist (environments, HTTP methods, team names, etc.).
View parameters
* `tag_name` (string, required): Trace tag name
* `pipeline` (array, optional): Pipeline to filter the spans used for value discovery
* `region` (string, optional): Region to query
Uses a fixed recent discovery window.
6. **`get_trace_waterfall`**: Retrieve one exact trace as a bounded parent/child waterfall with millisecond timing, interval-correct self-time, slowest spans, and largest self-time contributors. Does not compute a critical path or claim root cause.
View parameters
* `trace_id` (string, required): Exact trace ID
* `environment` (string, optional): Exact deployment environment
* `start_time_iso` / `end_time_iso` (string, optional): RFC3339 time bounds
* `lookback_minutes` (integer, optional): Default: 4320 (for exact trace lookup)
* `selected_span_id` (string, optional): Include attributes, events, and links for this span only
* `max_spans` (integer, optional): Default: 500, maximum: 1000
**Returns**: An `investigation-evidence/v1` envelope with the waterfall under `data`, plus `evidence_quality`, truncation warnings, and graph integrity warnings (cycles, orphans, duplicate spans). An empty result has `evidence_quality: insufficient` — widen the window or verify the trace ID before concluding the trace does not exist.
7. **`get_trace_attribute_deviations`**: Compare attribute-value distributions between two bounded span cohorts and rank supported differences. Use for slow vs fast, error vs non-error, or two equal-duration time windows. Results describe correlation, not cause.
View parameters
* `comparison_mode` (string, required): `latency`, `errors`, or `time`
* `service_name` (string, required): Exact service name
* `environment` (string, required): Exact `deployment.environment` value
* `operation` (string, optional): Exact operation/span name
* `filters` (array, optional): Trace JSON filter conditions — discover valid fields with `get_trace_attributes_for_pipeline` first
* `candidate_attributes` (array, optional): Up to 8 attribute names; omit for bounded auto-discovery
* `latency_threshold_ms` (number, required for `latency` mode): Positive threshold in milliseconds
* `start_time_iso` / `end_time_iso` (string, optional): Target window in RFC3339
* `lookback_minutes` (integer, optional): Alternative target lookback ending now. Default: 15, maximum: 15
* `baseline_start_time_iso` / `baseline_end_time_iso` (string, required for `time` mode): Non-overlapping baseline window equal in duration to the target window
* `minimum_cohort_size` (integer, optional): Default: 100, minimum: 20
* `minimum_value_support` (integer, optional): Default: 20, minimum: 10
* `limit` (integer, optional): Default: 10, maximum: 10
**Returns**: Full-denominator shares, percentage-point deltas, representative trace IDs, and `evidence_quality`. Requires the trace-analysis capability to be enabled for your tenant.
### Alert management
Use `get_alert_groups` to discover alert groups and `get_entity_alert_rules` to list rules for a selected entity.
1. **`get_alert_config`**: Get all configured alert rules from Last9. Supports typed filters and free-text search.
View parameters and returns
**Optional filters:**
* `rule_id`, `search_term`, `rule_name`, `severity`, `rule_type` (`static` or `anomaly`)
* `alert_group_name`, `alert_group_type`, `data_source_name`, `tags`
* `only_without_notification_channel`: Rules whose alert group has no per-entity channel binding (Alert Studio “Not configured”)
* `notification_channel_types`: Rules with a per-entity channel of any listed type (e.g. `slack`, `email`, `pagerduty`)
* `notification_channel_names`: Rules with a per-entity channel matching any listed name (AND-combined with other `notification_channel_*` filters on the same binding row)
* `notification_channel_severities`: Rules with a per-entity channel matching any listed severity (`breach` or `threat`)
**Returns per rule:**
* Alert rule ID, name, primary indicator, entity ID, state, severity, algorithm
* Alert group `name`, `data_source`, and `tags` when resolved
* **Notification Channels**: configured types in dashboard order, or “Not configured”
* **Notification Channel Bindings**: each binding row (type, name, severity) with snooze/in\_use flags
* Timestamps for creation/updates
2. **`get_alerts`**: Get currently active alerts from the Last9 monitoring system.
View parameters and returns
Parameters:
* `time_iso` (string, optional): Evaluation time in RFC3339 format
* `timestamp` (integer, optional): Deprecated Unix timestamp alias
* `window` (integer, optional): Time window in seconds. Default: 900 seconds, range: 1-3600
* `lookback_minutes` (integer, optional): Window in minutes when `window` is omitted. Range: 1-60
Returns:
* Alert rule details
* Alert state and severity
* Firing timestamps
* Rule configurations
* Metric degradation information
* Group labels and annotations
3. **`get_notification_channels`**: Get all notification channel configurations from Last9.
Returns
Returns all notification channels as a table with the following columns:
* `id`, `name`, `type`
* `service_fqid`: per-entity alert-group binding ID
* `global`: whether the channel applies to all services
* `in_use`: whether the channel is actively used in an alert rule
* `send_resolved`: whether resolved alerts trigger a notification (`true` / `false` / `null` if not set)
* `snoozed_until`: UTC timestamp if the channel is snoozed, `-` otherwise
* `severity`, `priority`
* `services`: comma-separated `namespace/name` pairs, `-` if the channel is global
4. **`get_alert_rule_state`**: Get historical firing state (1/0) per alert rule over a time range, grouped by `rule_id`.
View parameters
* `start_time` (integer, required): Unix epoch start of the range (inclusive)
* `end_time` (integer, required): Unix epoch end of the range (inclusive)
* `step` (integer, required): Resolution in seconds between samples
* `alert_group_id` (string, optional): Filter by alert group ID
* `rule_name` (string, optional): Regex filter on rule name
* `alert_group_name` (string, optional): Regex filter on alert group name
* `label_filters` (string, optional): Comma-separated `key=value` label filters
* `state` (string, optional): Filter by state (e.g. `firing`)
**Returns**: JSON map of `rule_id` → `[{timestamp, is_firing}]`. Sample count is capped at 100.
### Custom dashboards
1. **`list_dashboards`**: List all custom dashboards in your Last9 organization.
Returns
* JSON array of dashboard summaries: `id`, `name`, and metadata
* `reference_url` in MCP metadata linking to the dashboards index in the Last9 UI
2. **`get_dashboard`**: Get the full definition of a custom dashboard by ID.
View parameters and returns
Parameters:
* `id` (string, required): Dashboard UUID
* `region` (string): Region for panel query population. Optional when a default datasource region is configured
Returns:
* Full dashboard JSON including `name`, `panels[]`, and `metadata`
* Each panel includes `layout`, `visualization.type`, and `queries[]`
* `reference_url` in MCP metadata linking directly to the dashboard
3. **`create_dashboard`**: Create a new custom dashboard with panels and queries.
View parameters
* `dashboard` (object, required): Dashboard definition with `name` and `panels[]`. Each panel requires `name`, `layout` (`x`, `y`, `w`, `h`), `visualization.type`, and `queries[]`. A panel `version` defaults to `1` when omitted
* `metadata` (object, optional): Dashboard metadata — `_category` and `_type` fields (e.g. `{"_category":"custom","_type":"metrics"}`)
Returns the created dashboard JSON with its assigned `id` and a `reference_url` to open it in the Last9 UI.
4. **`update_dashboard`**: Update an existing custom dashboard by ID.
View parameters
* `id` (string, required): Dashboard UUID to update
* `dashboard` (object, required): Full replacement dashboard body (same shape as `create_dashboard`)
* `metadata` (object, optional): Replacement metadata
Readonly system dashboards return a 403 error. Returns updated dashboard JSON with `reference_url`.
5. **`delete_dashboard`**: Delete a custom dashboard by ID.
View parameters
* `id` (string, required): Dashboard UUID to delete
Readonly system dashboards cannot be deleted. Returns a `reference_url` to the dashboards index.
6. **`list_dashboard_snapshots`**: List frozen point-in-time snapshots for a dashboard.
View parameters
* `dashboard_id` (string, required): Dashboard UUID
**Returns**: Snapshot metadata (`id`, `name`, `expires_at`). Use `get_dashboard_snapshot` for full panel data.
7. **`get_dashboard_snapshot`**: Get a frozen dashboard snapshot by ID, including panel data at capture time.
View parameters
* `id` (string, required): Snapshot UUID
**Returns**: Full frozen snapshot with `dashboard_definition`, `panel_data`, `time_range`, and `variables`.
8. **`delete_dashboard_snapshot`**: Delete a frozen dashboard snapshot by ID.
View parameters
* `id` (string, required): Snapshot UUID to delete
### Entity discovery
Use `get_service_profile` before choosing telemetry tools for a service. It returns the service’s available signals and investigation context. Supply the required `service_name` and, optionally, a `datasource`.
1. **`did_you_mean`**: Suggests correct entity names when you’re unsure of the exact spelling. Use this proactively before querying with a name that might be a typo, abbreviation, or partial match.
View parameters
* `query` (string, required): The name to search for — can be a partial name, misspelling, or abbreviation
* `type` (string, optional): Restrict suggestions to a specific entity type. Supported values: `service`, `environment`, `host`, `database`, `k8s_deployment`, `k8s_namespace`, `job`
Returns up to 3 closest matches with similarity scores (0–100%) from the Last9 catalog, covering services, environments, hosts, databases, Kubernetes workloads, and more.
**When to use:**
* Before calling `get_service_logs`, `get_service_traces`, `get_service_performance_details`, etc. with a service name that might be misspelled (e.g. `"paymnt-svc"`, `"prod-srvice"`)
* When a previous tool call returned empty results for a given entity name
* When the user provides an ambiguous or abbreviated name (e.g. `"the payment thing"` or `"prod env"`)
**Example results:**
* `query="paymnt-svc"` → `payment-service (92%, service)`
* `query="prod"` → `production (89%, environment)`, `prod-eu (82%, environment)`
## Demos
1. Fixing a recent exception
[YouTube video player](https://www.youtube.com/embed/AQH5xq6qzjI?si=FTrs41Ph2PQkZ1Jq)
2. Optimizing logs for a service
[YouTube video player](https://www.youtube.com/embed/0M-XG63ILXk?si=yHXYMugA7v94DIaK)
3. Creating an RCA basis recent issues in the production environment
[YouTube video player](https://www.youtube.com/embed/Rcg-77GabAA?si=S_094pspCmmj3-B7)
4. Analyze background worker processes
[YouTube video player](https://www.youtube.com/embed/aZxoK4b071g?si=inXxvqj3GBdKUMQ6)
## Best practices
* **Name the service and environment.** Use `get_service_profile` to identify the available telemetry before choosing investigation tools.
* **Provide the incident window.** Prefer absolute UTC start and end times when returning to an earlier incident.
* **Discover fields before filtering.** Use `get_log_attributes_for_pipeline` and `get_trace_attributes_for_pipeline` to find valid field names.
* **Choose a trace tool for the question.** Use `get_trace_waterfall` for one trace’s timing and `get_trace_attribute_deviations` to compare groups of spans.
* **Limit automation tools.** Set a read-tool allowlist in your agent. Self-hosted servers can also use `LAST9_TOOLSETS=investigate` to expose investigation tools.
***
## Troubleshooting
* **“Last9 tools not available”**: Verify your IDE configuration and restart the application
* **OAuth flow not completing**: Ensure you are logged in to [app.last9.io](https://app.last9.io) before authorizing. If redirected to a 404, try logging in to the dashboard first and then re-initiating the OAuth flow from your IDE
* **“Authentication failed”** or **“401 Unauthorized”**: Reauthorize a hosted OAuth connection. For programmatic access, check the MCP client token. For a local server, check `LAST9_REFRESH_TOKEN`.
* **“No data returned”**: Ensure your services are sending telemetry to Last9 and try broader time ranges
* **“Connection issues”**: Double-check:
* Your organization slug is correct. Find it in `app.last9.io/v2/organizations//...`.
* The URL format: `https://app.last9.io/api/v4/organizations//mcp`
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Last9 MCP for AI agents
> Connect an AI agent or service to Last9 MCP with bearer authentication and Python examples.
Use Last9’s MCP server to query telemetry from a Python AI agent, such as an incident bot or on-call assistant. For chat in Last9, use [AI Assistant](/docs/ai/ai-assistant/). For instructions your coding agent can follow, see [agent skills](/docs/ai/agent-skills/), or see [Build your own AI SRE](/docs/ai/build-your-own-ai-sre/) to connect your own bot or investigation service.
Use an MCP client token for programmatic access from agents and services. For IDE setup with browser sign-in, see [Last9 MCP](/docs/ai/mcp/) and the [MCP](https://app.last9.io/mcp) page in Last9.
## Authentication
Two modes are available:
| Mode | Best for | How it works |
| ------------------ | ------------------------------ | --------------------------------------------------------------------------------- |
| Hosted MCP + OAuth | Developers in IDEs | Sign in with a Last9 account through the browser |
| MCP token (Bearer) | Agents, services, CI pipelines | Generate a client token; pass as `Authorization: Bearer ` in every request |
### Get an MCP token
1. Open **Query Tokens** in your Last9 organization.
2. Click **New Token** → Token Type: **Client** → Client Type: **MCP**
3. Copy the token and store it in your secrets manager.
The MCP server URL is:
```plaintext
https://app.last9.io/api/v4/organizations//mcp
```
Find your organization slug in your Last9 dashboard URL: `app.last9.io/v2/organizations//...`.
## Team token management
Note
Use OAuth for interactive IDE sessions and MCP client tokens for services such as agents, bots, and pipelines.
| Scenario | Recommendation |
| --------------------------------------- | ------------------------------------------------------------------------------ |
| Developer IDEs | Use individual OAuth sign-in. |
| Shared SRE bot / on-call assistant | Keep a separate token for the bot in your secrets manager. |
| CI pipelines or automation scripts | Keep a separate token for each pipeline so it can be rotated independently. |
| Multiple team members sharing one token | Use separate credentials to avoid disrupting everyone when a token is rotated. |
Review token access when ownership of a service changes. Rotate a token if someone who had access to it leaves the team.
Note
Authentication determines access to Last9. Your AI client or agent determines which MCP calls need confirmation, so configure its tool permissions before allowing dashboard changes or other write actions.
For questions about rate limits or high-volume agent workloads, contact .
## Python agent examples
### Anthropic SDK (Claude)
Install `anthropic` and set `ANTHROPIC_API_KEY`, `ANTHROPIC_MODEL`, `LAST9_ORG_SLUG`, and `LAST9_MCP_TOKEN`. Choose a Claude model that supports the [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector). The example enables two read tools using the current connector beta:
```python
import os
import anthropic
client = anthropic.Anthropic()
response = client.beta.messages.create(
model=os.environ["ANTHROPIC_MODEL"],
max_tokens=4096,
system="You are an SRE assistant. Investigate issues using Last9 observability data.",
messages=[
{
"role": "user",
"content": "Inspect payment-service errors in production over the last 15 minutes. Report evidence and missing information.",
}
],
mcp_servers=[
{
"type": "url",
"url": f"https://app.last9.io/api/v4/organizations/{os.environ['LAST9_ORG_SLUG']}/mcp",
"name": "last9",
"authorization_token": os.environ["LAST9_MCP_TOKEN"],
}
],
tools=[{
"type": "mcp_toolset",
"mcp_server_name": "last9",
"default_config": {"enabled": False},
"configs": {
"get_service_profile": {"enabled": True},
"get_service_logs": {"enabled": True},
},
}],
betas=["mcp-client-2025-11-20"],
)
print("\n".join(block.text for block in response.content if block.type == "text"))
```
Expand the tool allowlist to match your investigation. Handle tool failures and incomplete responses before publishing a report.
### LangChain / LangGraph
LangChain provides MCP support through `langchain.mcp` in `langchain[mcp]>=1.4.0`. The API is in beta. See its [MCP migration guide](https://docs.langchain.com/oss/python/migrate/langchain-mcp-adapters) if you use the older `langchain-mcp-adapters` package.
```python
import asyncio
import os
from fastmcp import Client
from langchain.mcp import MCPAdapter
from langchain.agents import create_agent
async def run_sre_agent(question: str) -> str:
url = f"https://app.last9.io/api/v4/organizations/{os.environ['LAST9_ORG_SLUG']}/mcp"
client = Client(url, auth=os.environ["LAST9_MCP_TOKEN"])
async with MCPAdapter(client) as adapter:
available_tools = await adapter.list_tools()
allowed_names = {"get_service_profile", "get_service_logs"}
tools = [tool for tool in available_tools if tool.name in allowed_names]
agent = create_agent(os.environ["LANGCHAIN_MODEL"], tools)
result = await agent.ainvoke(
{"messages": [{"role": "user", "content": question}]}
)
return result["messages"][-1].content
if __name__ == "__main__":
answer = asyncio.run(
run_sre_agent("Inspect payment-service errors in production over the last 15 minutes. Report evidence and missing information.")
)
print(answer)
```
Install the required packages:
```bash
pip install "langchain[mcp,anthropic]>=1.4.0"
```
Set `LANGCHAIN_MODEL` to an `anthropic:` supported by your account, and set `ANTHROPIC_API_KEY`, `LAST9_ORG_SLUG`, and `LAST9_MCP_TOKEN`.
### OpenAI Responses API
See [Last9 MCP → Using with OpenAI’s Responses API](/docs/ai/mcp/#using-last9-mcp-with-openais-responses-api) for the OpenAI example with Bearer token auth.
## Building an on-call bot
Call an agent from your alert or chat handler with the original question, service, environment, and absolute incident window. Keep each incident’s context separate, set a time and tool-call budget, and return incomplete status when required data is missing.
Before sending a report, check tool errors and separate confirmed findings from possible causes. Keep remediation behind your normal review process. Refer to [Build your own AI SRE](/docs/ai/build-your-own-ai-sre/) for the complete design and validation steps.
## Key tools for agent workflows
The MCP server exposes all Last9 observability tools. The most useful for agent workflows:
| Tool | What it returns |
| --------------------------------- | ------------------------------------------------------------------ |
| `get_service_performance_details` | Latency p95, error rate, throughput for a service |
| `get_exceptions` | Aggregated evidence of server-side exceptions |
| `get_service_dependency_graph` | Dependency throughput, response-time, and error metrics |
| `get_apm_service_deviations` | Regressions/improvements vs an equal-duration baseline window |
| `get_trace_waterfall` | Bounded parent/child waterfall for one trace with timing/self-time |
| `get_trace_attribute_deviations` | Attribute values that differ between slow/fast or error cohorts |
| `get_alerts` | Currently firing alert rules and severity |
| `get_logs` | LogJSON pipeline results, including filtered logs and aggregates |
| `get_service_logs` | Raw service log lines with severity and body filters |
| `get_service_profile` | Available telemetry signals and context for a service |
| `get_change_events` | Recent deployments and config changes (correlate with incidents) |
| `prometheus_range_query` | Run any PromQL expression over your metrics |
| `did_you_mean` | Fuzzy-match entity names to avoid empty results from typos |
For the full reference, see [Available Tools](/docs/ai/mcp/#available-tools) on the main MCP page.
***
## Troubleshooting
* **`401 Unauthorized`**
Check that:
* The `Authorization` header is `Bearer ` (not `Basic`, not the token alone)
* The token is an **MCP-type** Client token from Query Tokens.
* **Tools return empty results**
Time-window defaults vary by tool. For example, `get_logs` defaults to 5 minutes, while an exact trace lookup defaults to 4320 minutes. Pass an explicit window when investigating an incident:
```python
# In tool parameters passed by the agent
{"lookback_minutes": 360}
```
If the service name returns no results, have the agent call `did_you_mean` first to resolve the correct name.
* **Rate limit errors**
Each organization has rate limits for its endpoints. Limit concurrent requests across all agent instances using the organization. For workloads with many requests, contact to discuss limits.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Use Last9 AI in Slack
> Connect Last9 to Slack and investigate production issues with your team in an incident thread.
Mention `@Last9` in Slack to ask about your services, alerts, logs, and traces. The assistant replies in a thread, where you can ask follow-up questions and share evidence with your team.
```text
@Last9 Investigate HTTP 5xx errors for checkout-api in production
over the last 30 minutes. Confirm the service and data source,
identify affected routes, and include supporting evidence links.
```
Replace the example service with your own. For a historical incident, give explicit start and end times with a time zone.
## Prerequisites
* Check that AI access is enabled for your Last9 organization. An organization admin can open [**AI Settings**](https://app.last9.io/ai-settings) and check **Enable Last9 AI**.
* Confirm that the relevant telemetry is available in Last9.
* Check that you have permission to install or approve apps in your Slack workspace.
* Use a Last9 account with the same email address as your Slack account. Last9 uses your Slack email to identify your account.
## Setup
1. [Sign in to Last9](https://app.last9.io) and open [**Slack App**](https://app.last9.io/slack-app).
2. Click **Connect Slack Workspace**. Allow pop-ups for Last9 if your browser blocks the authorization window.
3. Select the intended Slack workspace, review the requested permissions, and authorize the app.
4. Invite the app to the channel where you want to investigate:
```text
/invite @Last9
```
5. Mention `@Last9` with a question that includes the service and time window. Check that the response refers to the intended service and environment.
The Slack App page shows the workspace connection status. Use **Re-authorize Slack** if you need to renew the app’s authorization.
Note
Start the setup from the Slack App page in Last9 so the authorization request includes your organization and account details.
## Investigate in a thread
Mention `@Last9` in each follow-up, and keep questions for the same incident in the same thread:
```text
@Last9 Which requests failed in the incident window? Show a representative
request or trace ID and distinguish total counts from sampled logs.
```
```text
@Last9 Check the related traces and logs for the selected request. What is
confirmed, which causes are still possible, and what evidence is missing?
```
```text
@Last9 Recheck the last 15 minutes before writing the incident summary.
State the exact query window and verify successful requests as
well as the error rate.
```
Open the evidence links in Last9 to inspect the query, filters, and time window.
For the complete workflow, see [Investigate an incident with AI](/docs/ai/investigate-an-incident/).
For team participation, account requirements, and sharing AI Assistant conversations, see [Collaboration mode](/docs/ai/collaboration-mode/).
## Use an alert as the starting point
The Last9 Slack app also supports alert notification channels. Configure delivery with [Slack notification integration](/docs/slack-integration/), then mention `@Last9` in the alert’s thread and ask it to investigate the alert window.
```text
@Last9 Investigate the alert. Use the service and time window in
the alert, check supporting telemetry, and list confirmed findings
and remaining questions.
```
Installing the app and asking a question does not configure recurring checks. Use [alert rules](/docs/alert-rules/) to define the conditions you want Last9 to monitor.
## Review proposed actions
If an investigation proposes a configuration change and presents an approval request, inspect the operation and arguments before approving it. A proposed action or a written recommendation is not evidence that a change has been executed.
In the incident summary, state which actions your team performed, which the assistant completed, and which are still proposed.
## Channel access and shared information
Invite the app to each channel where you want to use it, including private channels. Anyone with access to the channel can read the answers and evidence posted in a thread, so choose the channel before asking about production telemetry.
See [AI data handling](/docs/ai/#privacy-and-security) for what an investigation can include, and contact for organization-specific requirements.
***
## Troubleshooting
| Problem | What to check |
| --------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- |
| The authorization window does not open | Allow pop-ups for Last9, then click **Connect Slack Workspace** again. |
| Slack setup does not complete | Confirm the selected workspace and your permission to install apps. Restart from the [Slack App](https://app.last9.io/slack-app) page in Last9. |
| `@Last9` does not reply | Check the workspace connection, invite the app to the channel, and mention it explicitly. Ask an admin to check AI access. |
| Last9 does not recognize your account | Confirm that your Slack email matches your Last9 account email. Ask your organization admin to add your account if needed. |
| The answer refers to the wrong service | Provide the exact service, environment, and data source, then ask the assistant to confirm them before querying again. |
| The answer is incomplete | Ask which queries failed, returned samples, or found no data. Check the time window and follow the evidence links. |
| An old answer no longer reflects the incident | Ask for a fresh query window and a new recovery check in the thread. |
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Alert Monitor
> View a live, auto-updating stream of every firing alert across your metrics and log Alert Rules in the Last9 Alert Monitor.
The **Alert Monitor** is a live, auto-updating stream of every alert currently firing across all your Alert Rules — metrics and log rules alike. It is the default screen when you open **Alerting**.
## Viewing Firing Alerts
Each row shows the **Alert Group / Alert Rule** name, **State**, **Firing Since**, **Severity**, and **Algorithm**. Expand a row to see the firing labelsets. For Threshold rules, each labelset also shows its **Worst** value and the **Condition** that triggered it.
Use the controls along the top to focus the view:
* **Search** by alert group, alert rule, or labelset.
* **Group By** to switch between an ungrouped stream and a grouped view — for example, when one rule fires across dozens of labelsets, grouping collapses them under that rule so you see which rules are affected instead of scrolling every individual fire.
* **Severity** and **Algorithm** filters to narrow to **Breach** / **Threat**, or to an algorithm family — **Threshold** or **Anomaly** (which includes Adaptive).
* **Acknowledgement** filter to separate alerts someone has taken (**Ack’d**) from the ones still waiting for a responder (**Not Ack’d**).
* **Show resolved alerts** to include alerts that have recently recovered.
* The time range, refresh, and auto-refresh interval controls on the top right keep the stream current.
## Alert Details
Click any alert to open its details in place. The panel always shows **Last Triggered At**, along with the parameters used to evaluate the rule, which vary by algorithm:
* **Threshold** — the **Condition**, the **Worst Window** value, and the **Sensitivity** (for example, *3 bad min out of 5*).
* **Anomaly** — for Adaptive rules, the **tolerance** and **window**; for legacy anomaly rules, the sensitivity.
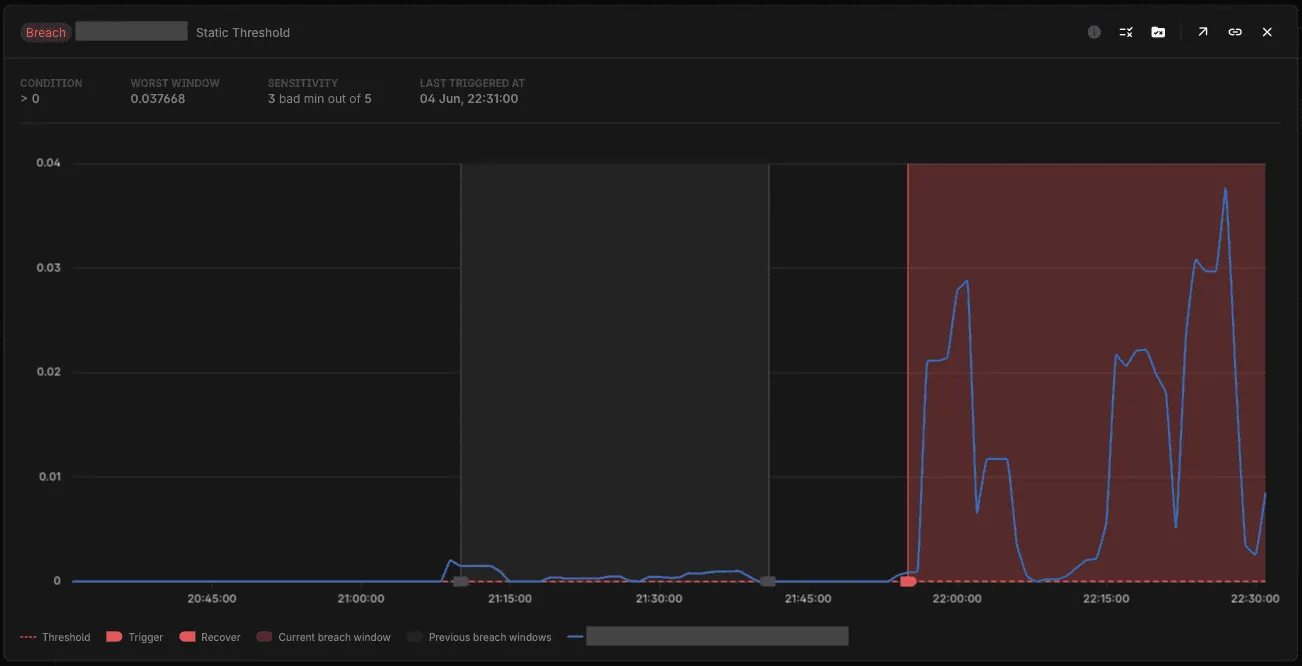
The chart plots the last 2 hours of the rule’s query. It marks each **Trigger** and **Recover** point and shades the breach windows (the current one plus any **Previous breach windows**), so you can tell whether this is a one-off or a recurring problem. Threshold rules plot the query against a flat threshold line.
Adaptive rules render the learned band instead, shading the region the rule treats as normal so you can see where the query broke out of it.

From the panel header you can copy a direct link to the alert, jump to the underlying [Alert Rule](/docs/alert-rules/) and its [Alert Group](/docs/alert-rules/#alert-groups-view), or open the query in its explorer to investigate further — the Metrics Explorer for metrics rules, the Logs Explorer for log rules.
## Acknowledging Alerts
Every firing rule in the monitor can be **acknowledged**, which records you as the owner of that alert so the rest of the team knows who is on it. Acknowledge from the row’s actions menu or from the alert details header, optionally muting the rule in the same action, and reassign or release ownership from the same menu. Rows and the details header then show who owns the alert.
[Acknowledge Alerts](/docs/acknowledge-alerts/) covers the options, who can use them, and how ownership is released.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Alert Rules and Groups
> Browse, filter, and manage Alert Rules and Alert Groups from a single rules-first page.
An **Alert Rule** evaluates a query against a condition on a schedule, and generates an alert when the condition is met. Rules are organized into **Alert Groups** — containers that share a data source and the notification settings their rules use.
The **Rules** page lists every Alert Rule in your org in a single table, so you can see what is configured, what is firing, and who owns it.
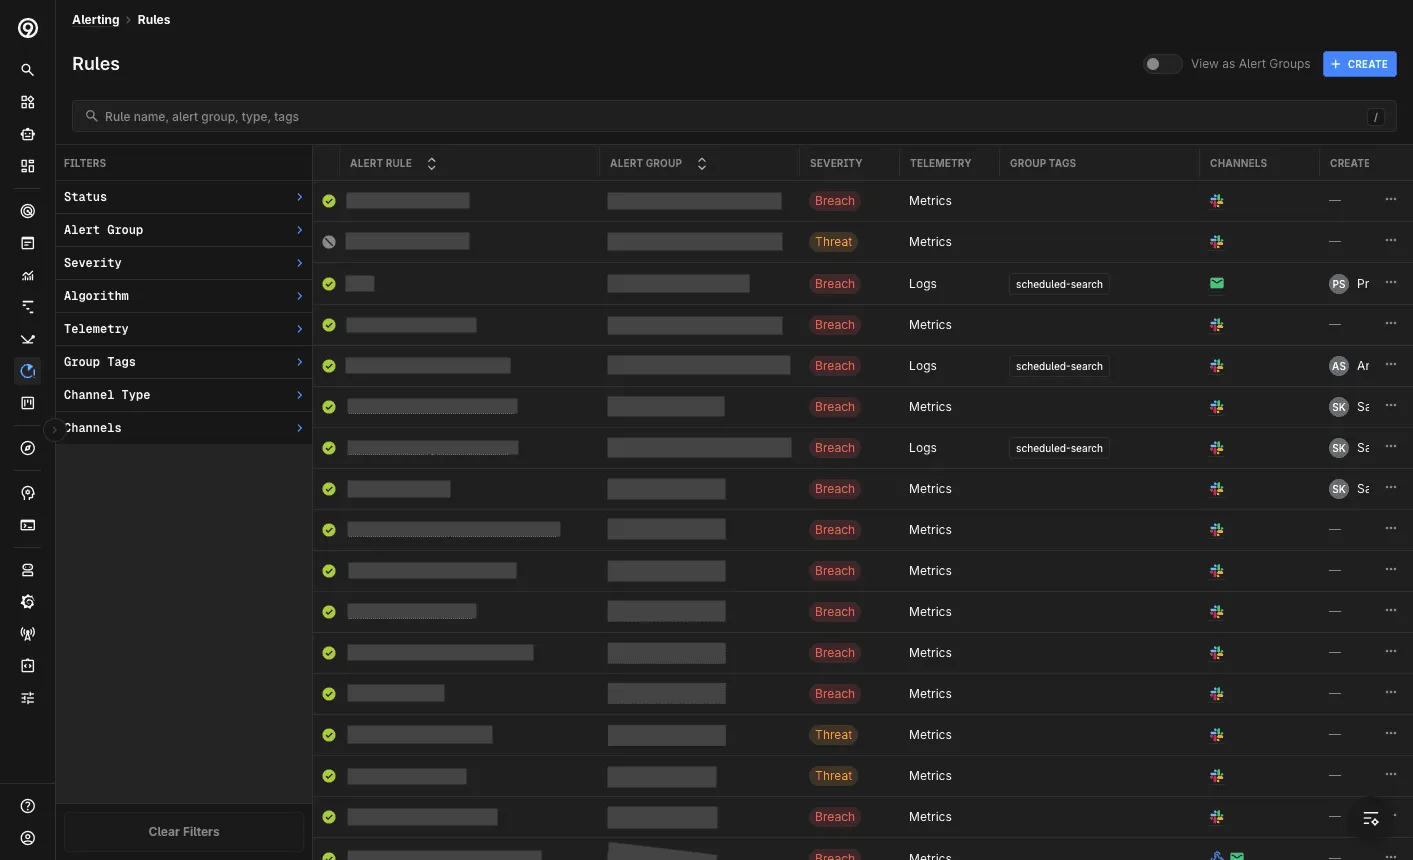
## Alert Rules View
The default view is **rules-first**: each row is a single Alert Rule, showing its **Alert Rule** name, the **Alert Group** it belongs to, **Severity**, **Telemetry** type, **Channels**, and **Created by**. Long names truncate with a tooltip, and your search term is highlighted in the name cell.
### Filtering
The filter panel on the left narrows the table by **Status**, **Alert Group**, **Severity**, **Algorithm**, **Telemetry**, **Group Tags**, **Channel Type**, and **Channels**. Each filter defaults to all-checked; hover a value to **Only** it or re-select **All**. Use **Clear Filters** to reset.
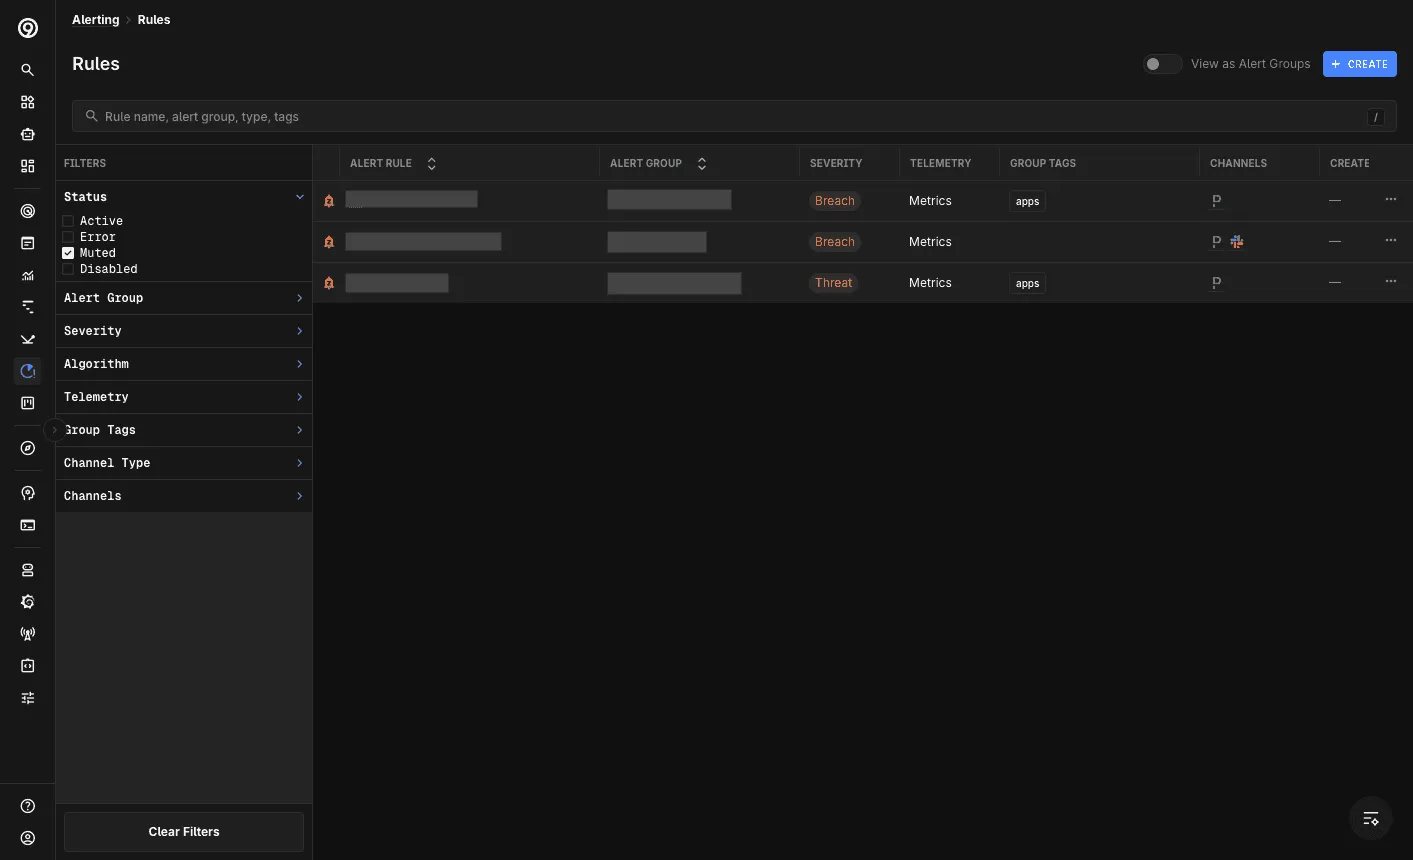
### Row Actions
Each rule’s actions menu offers:
* **Edit** — open the rule in the [Alert Rule editor](/docs/creating-an-alert-rule/).
* **Duplicate** — create a copy of the rule.
* **Disable** — stop the rule from evaluating and notifying.
* **Delete** — permanently remove the rule.
**Disable** and **Delete** are distinct, separately-confirmed actions, and are available for system-managed and deprecated-algorithm rules as well.
### Creating a Rule
Click **Create** to open the [Alert Rule editor](/docs/creating-an-alert-rule/), where you choose the telemetry type, build the query, set the condition, and preview when the rule would fire.
## Alert Groups View
An **Alert Group** is an organizational container for related Alert Rules. A group categorizes rules (for example, node alerts or pod alerts), shares a **data source**, and owns the **Notification Channels** and notification settings that its rules use.
Toggle **View as Alert Groups** in the top right to switch from the rules view to a grouped view, where each row is a group with its **Telemetry** type, **No. of Rules** (with a count of any disabled rules), **Group Tags**, **Channels**, and **Created by**.
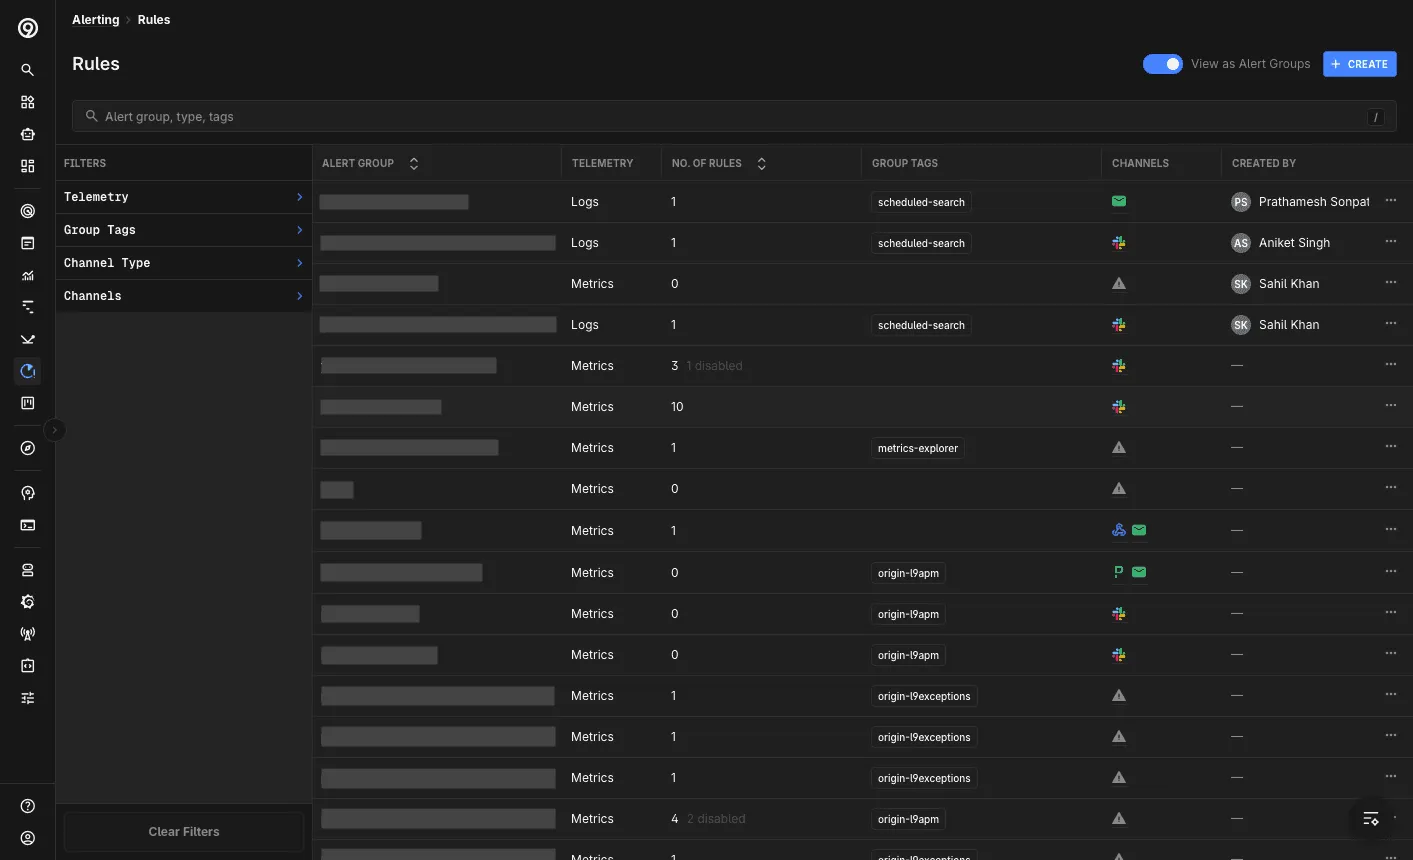
This view filters by the group-level facets only — **Telemetry**, **Group Tags**, **Channel Type**, and **Channels**. From a group’s actions menu you can also **duplicate** or **delete** it; deleting a group removes all of its Alert Rules and the alerts they generated.
Select a group to open its **Settings** modal, organized into four tabs.
### General
* **Group basics** — the group **name**, its **Data source** (changing the data source may break existing rules in the group), and a **See all alert rules in this group** shortcut.
* **Alert rule controls** — **Alert rules enabled** to turn the group’s rules on or off, and **Mute notifications** to snooze the group (for example, *Muted indefinitely*).
* **Labels**, **Details**, and **Links** — collapsible cards for adding metadata, descriptive details, and external links (runbooks, dashboards, repos) to the group.
* **Manage as code** — groups can also be managed via GitOps with [Declarative Alerting via IaC](/docs/alerting-via-iac/).
### Channels
Channels are configured per severity — separately for **Threat** and **Breach** notifications — and apply to every rule in the group.
For each channel type (Email, Opsgenie, PagerDuty, Slack, Webhook), select a configured [Notification Channel](/docs/notification-channels/) and toggle it on. For Slack, you can also add an **Also Mention** to tag a person or group. Ensure at least one Notification Channel is configured before assigning it here.
### Settings
The Settings tab controls how often Last9 re-notifies your channels while an alert stays firing.
* **Override defaults** — by default the group uses system defaults; turn this on to set group-level values.
* **Repeat while firing** — re-send notifications until the alert stops firing; turn off to notify once per firing.
* **Repeat interval (seconds)** — how long to wait between repeats.
* **Maximum repeats** — stop after this many repeats per firing; use `-1` for no limit.
See [Repeat Notification Interval](/docs/repeat-notification-interval/) for details.
### Group Label Filters
Group Label Filters are available for metrics Alert Groups only. They are automatically applied to all rules in the group for the set data source. Optionally **override the default data source**, then add one or more filter conditions (key, operator, value).
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Alert Timing & Delivery Reference
> Understand exactly when your alerts fire, repeat, and resolve across notification channels. Quick reference for alert timing behavior with Threshold, Adaptive, and Anomaly alerts, and SLO violations.
Get alerts when you need them. Here’s exactly when notifications fire, repeat, and resolve across your channels.
Note
**New alert rules need 5 minutes to bootstrap** before they start processing.
## Quick Reference
Threshold, Adaptive, Anomaly, and log Alert Rules all share the same delivery timing:
* **First alert:** 2 minutes after the condition is met (t+2)
* **Repeat alerts:** Every 61 minutes while active
* **Resolution:** 11 minutes after the condition clears
Note
**SLO alerts** differ: first alert at t+4, repeats every 16 minutes, resolution 31 minutes after recovery. Email is not supported as an SLO channel.
## How Alert Timing Works
Once the condition is met at timestamp `t`, here’s the timeline:
```plaintext
t: Condition met (CPU spikes, error rate jumps, log match)
t+1: Last9 confirms and generates the alert
t+2: Notification hits your channel
t+61: Reminder if still firing
recovery+11: Resolution
```

Note
`t` is when the condition is **observed** inside Last9, not when it occurred in the real world. Data ingestion (scrape / remote-write for metrics, log-ingestion delay for logs) and the rule’s evaluation or search frequency add latency before `t`. For log rules, the bad-minutes window does not apply — it is fixed at 1 out of 1.
## Notification Channels
All alert types deliver to every channel — Slack, PagerDuty, OpsGenie, Webhook, and Email — with the same timing. The only exception is **SLO alerts**, which do not support Email.
## Why These Delays?
* **Processing time:** Last9 needs 1-3 minutes to ingest data, evaluate the rule, and confirm the condition
* **Delivery buffer:** 1-minute buffer accounts for network latency and channel processing
* **Resolution delays:** Prevents flapping alerts when conditions briefly recover then fail again
## Example
**Scenario:** API response time spikes at 1:59 PM
* **2:01 PM:** Last9 confirms the breach
* **2:02 PM:** Webhook fires, Slack notification arrives
* **3:01 PM:** Reminder if still alerting
* **When fixed + 11 min:** Resolution notification
## Changing the Repeat Interval
The repeat frequencies above are the defaults. You can configure a custom interval, cap the number of reminders, or switch to **notify-once** (one notification per firing episode) on a per-alert-group basis.
See [Repeat Notification Interval](/docs/repeat-notification-interval/) for configuration steps.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Alerting
> Everything you need to know to start alerting on your metrics and logs with Last9.
Last9 Alerting lets you detect problems across your telemetry and route notifications to the people and tools that need to act. You define **Alert Rules** that evaluate a query on a schedule, see firing alerts live in the **Alert Monitor**, and deliver notifications through **Channels** like Slack, PagerDuty, and email.
Alerting on anomalies
For new anomaly-detection rules, start with [Adaptive Alerting](/docs/adaptive-alerting/), the supported option for detecting deviations from a learned metric baseline. Adaptive runs on metrics; for log or trace signals, first create [LogMetrics](/docs/streaming-aggregations/#transforming-logs-to-metrics-last9-logmetrics) or [TraceMetrics](/docs/streaming-aggregations/#transforming-traces-to-metrics-last9-tracemetrics).
## Types of Alerts
Each Alert Rule alerts on **Metrics** or **Logs**. Use the no-code **Builder**, or write the query directly in PromQL (metrics) or LogQL (logs). To alert on traces, convert them to metrics with TraceMetrics.
On the [Rules](/docs/alert-rules/) page, **Telemetry** is one of the filters you can use to narrow the list.
Log rules and Scheduled Search
A log Alert Rule and a [Scheduled Search](/docs/scheduled-search/) map to each other in both directions. Scheduled Search as a standalone surface will be deprecated in favor of log Alert Rules.
## Navigating Alerting
Alerting is organized into three sections, accessible from the sidebar:
* **Monitor:** A live, auto-updating stream of every firing alert across all your rules — metrics and logs. Click any alert to open its details in place, including previous fires, bounds, and a link to the underlying rule. [Learn more](/docs/alert-monitor/). From here you can also [acknowledge](/docs/acknowledge-alerts/) an alert to record who is on it.
* **Rules:** A rules-first table of every Alert Rule with its status, telemetry type, severity, and creator. Create and edit rules with a live preview of when the rule would fire. Toggle to a grouped view to manage [Alert Groups](/docs/alert-rules/#alert-groups-view) and their settings. [Learn more](/docs/alert-rules/).
* **Channels:** Manage [Notification Channels](/docs/notification-channels/) — the destinations Last9 sends alert notifications to.
## Creating Your First Alert
1. Create an [Alert Rule](/docs/creating-an-alert-rule/) — choose Metrics or Logs, set a condition, and preview when it would fire.
2. Organize rules into [Alert Groups](/docs/alert-rules/#alert-groups-view) and configure group-level settings.
3. Add a [Notification Channel](/docs/notification-channels/) so alerts reach Slack, PagerDuty, email, or a webhook.
4. Watch firing alerts in the [Alert Monitor](/docs/alert-monitor/), and [acknowledge](/docs/acknowledge-alerts/) the ones you pick up.
Prefer a gitops workflow? See [Declarative Alerting via IaC](/docs/alerting-via-iac/).
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Declarative Alerting via IaC
> Last9 supports configuring alerts and notifications automatically using a Python-based SDK tool which takes care of infrastructure changes
Configurations for alerting and notifications for observability at scale are hard to start, maintain and fix manually, just like provisioning infrastructure at scale. With infrastructure changes, it’s important that the observability stack also catch up with it to avoid the chances of issues because of a lack of observability or black swarm events. Last9 has introduced.`l9iac` tool to solve the exact same problem.
## Installation
Last9’s IaC (Infrastructure as Code) tool is available as a Docker image, providing a consistent and isolated environment for automating entity creation and alert configuration.
1. **Pull the Docker Image**
```bash
docker pull last9system/iac:latest
```
The image is available on [DockerHub](https://hub.docker.com/repository/docker/last9system/iac/general).
2. **Prepare Your Working Directory** Create a directory containing:
* Your IaC YAML files
* `config.json` with your refresh tokens ([see file structure](#configuration-file-structure))
* Space for the state lock file
3. **Run the Docker Container**
```bash
docker run --name l9iac -d -v : last9system/iac:
```
Example:
```bash
docker run -d -v /home/user/iac-files:/app/rules last9system/iac:2.4.2
```
> 💡 **Note**: If using Docker Desktop, ensure file sharing is enabled for the volume mount.
4. **Execute IaC Commands**
```bash
docker exec -it l9iac -mf -c
```
Example:
```bash
docker exec -it bcdea6660fd4 l9iac -mf /app/rules/alert-rules.yaml -c /app/rules/config.json plan
```
## Configuration File Structure
The IaC tool requires a `config.json` file with the following structure:
```json
{
"api_config": {
"read": {
"refresh_token": "",
"api_base_url": "https://app.last9.io/api/v4",
"org": ""
},
"write": {
"refresh_token": "",
"api_base_url": "https://app.last9.io/api/v4",
"org": ""
},
"delete": {
"refresh_token": "",
"api_base_url": "https://app.last9.io/api/v4",
"org": ""
}
},
"state_lock_file_path": "state.lock" // Should be in the same directory as model_file and config_file
}
```
### Important Notes
* The `refresh_token` values can be obtained from the [API Access](https://app.last9.io/api-access) page in the Last9 dashboard ([know more](/docs/getting-started-with-api/))
* The `` can be obtained from the app’s URL: `app.last9.io/v2/organizations/`
* For on-premise Last9 setups, contact to get the correct `api_base_url`
* The `state_lock_file_path` should be accessible from the directory where you run the IaC commands
## Quick Start
1. Create a *YAML* as per your alert rule configuration
**Example**: notification\_service\_am.yaml
```yaml
# notification_service_am.yaml
entities:
- name: Notification Backend Alert Manager
type: service_alert_manager
data_source: prod-cluster
entity_class: alert-manager
external_ref: unqiue-slug-identifier
indicators:
- name: availability
query: count(sum by (job, taskid)(up{job !~ "ome.*"}) > 0) / count(sum by (job, taskid) (up{job=~".*vmagent.*", job !~ "ome.*"})) * 100
- name: loss_of_signal
query: 'absent(up{job !~ "ome.*"})'
alert_rules:
- name: Availability of notification service should not be less than 95%
description: The error rate (5xx / total requests) is what defines the availability, lower value means more degradation
indicator: availability
less_than: 99.5
severity: breach
bad_minutes: 3
total_minutes: 5
group_timeseries_notifications: false
annotations:
team: payments
description: Error Rate described as number of 5xx/throughput
runbook: https://notion.com/runbooks/payments/error_rates_fixing_strategies
```
2. Prepare the configuration file for running the IaC tool
The configuration file has the following structure. It is a JSON file.
```json
{
"api_config": {
"read": {
"refresh_token": "",
"api_base_url": "https://app.last9.io/api/v4",
"org": ""
},
"write": {
"refresh_token": "",
"api_base_url": "https://app.last9.io/api/v4",
"org": ""
},
"delete": {
"refresh_token": "",
"api_base_url": "https://app.last9.io/api/v4",
"org": ""
}
},
"state_lock_file_path": "state.lock"
}
```
* The `refresh_token` can be obtained from the API Access page from the Last9 dashboard. You need to have `refresh_tokens` for all 3 operations - read, write and delete as the `l9iac` tool will perform all these 3 actions while applying the alert rules.
* The `` is your organization’s unique slug in Last9. It can be obtained from the API access page of Last9 dashboard.i
* The default `api_base_url` is `https://app.last9.io/api/v4`. If you are on an on-premise setup of Last9, contact to get the `api_base_url`.
* The `state_lock_file_path` is name of the file where `l9iac` will store the state lock of current alerting state(on the same lines of terraform state.lock).
3. Run the following command to do a dry run for the changes
```shell
l9iac -mf notification_service_am.yaml -c config.json plan
```
4. Run the following command to apply the changes
```shell
l9iac -mf notification_service_am.yaml -c config.json apply
```
Tip
We will provision the GitOps flow that will run `apply` command once changes are merged to the master branch in the GitHub repo. Contact for more details.
## Schema
Here is the complete schema for generating the above `.yaml` file:
### Entities
| Field | Type | Unique | Required | Description |
| ---------------------------------------------------- | --------------- | ------ | -------- | --------------------------------------------------------------------------------------------------------------------- |
| name | string | false | true | Name of the entity (alert manager) |
| type | string | false | true | Type of the entity |
| external\_ref | string | true | true | External reference for the entity, it’s a unique slug format identifier for each alert manager |
| [adhoc\_filter](#common-rule-filters-adhoc-filters) | object | false | optional | List of common rule filters for the entity |
| [alert\_rules](#alert-rules) | array | false | optional | List of alert rules for the entity |
| data\_source | string | false | optional | Data source |
| data\_source\_id | string | false | optional | The ID of the data source |
| description | string | false | optional | Description of the entity |
| entity\_class | string | false | optional | Denotes the class of the entity. Supported values: `alert-manager` |
| [indicators](#indicators) | array | false | optional | List of indicators for the entity |
| labels | object | false | optional | List of key value pairs of group label names and values |
| [links](#links) | array | false | optional | List of links associated with the entity |
| namespace | string | false | optional | The namespace of the entity |
| [notification\_channels](#notification-channels) | string OR array | false | optional | List of notification channels applicable to the entity |
| tags | array | false | optional | List of tags for the entity |
| team | string | false | optional | The team that owns the entity |
| tier | string | false | optional | Tier of the entity |
| [ui\_readonly](/docs/alert-rules/#alert-groups-view) | boolean | false | optional | Disable any sort of edits to the alert group from the UI |
| workspace | string | false | optional | Workspace of the entity |
| renotify\_enabled | boolean | false | optional | Whether to repeat notifications while the alert stays firing. `false` = notify-once. Inherits org default if omitted. |
| renotify\_interval\_seconds | integer | false | optional | Seconds between repeat notifications. Inherits org default (3600) if omitted. Must be ≥ 1. |
| renotify\_occurrences | integer | false | optional | Max repeat notifications per firing episode. `-1` = unlimited. Inherits org default if omitted. |
### Common Rule Filters (Adhoc Filters)
| Field | Type | Unique | Required | Description |
| ------------ | ------ | ------ | -------- | ------------------------------------------------- |
| labels | object | false | required | List of key value pairs of label names and values |
| data\_source | string | false | required | Defaults to entity’s data source |
### Alert Rules
| Field | Type | Unique | Required | Description |
| -------------------------------- | ---------- | ------ | -------- | -------------------------------------------------------------------------------------------- |
| name | string | true | required | Rule name that describes the alert |
| indicator | string | false | required | Name of the indicator |
| bad\_minutes | integer | false | required | Number of minutes the indicator must be in a bad state before alerting |
| total\_minutes | integer | false | required | Total number of minutes the indicator is sampled over |
| description | string | true | optional | Description for an alert rule that is included in the alert payload |
| expression | string | false | optional | Alert rule expression, to be used only for pattern-based alerts |
| greater\_than | number | false | optional | Alert triggers when the indicator value is greater than this |
| greater\_than\_eq | number | false | optional | Alert triggers when the indicator value is greater than or equal to this |
| less\_than | number | false | optional | Alert triggers when the indicator value is less than this |
| less\_than\_eq | number | false | optional | Alert triggers when the indicator value is less than or equal to this |
| equal\_to | number | false | optional | Alert triggers when the indicator value is equal to this |
| not\_equal | number | false | optional | Alert triggers when the indicator value is not equal to this |
| group\_timeseries\_notifications | boolean | false | optional | If multiple impacted time series in an alert need to be grouped as one notification or not |
| is\_disabled | boolean | false | optional | Whether the alert is disabled or not |
| label\_filter | map/object | false | optional | Mapping of the variables present in the indicator query and their pattern for the alert rule |
| mute | boolean | false | optional | If alert notifications need to be muted or not |
| [runbook](#runbook) | | false | optional | Runbook link to be included in the alert payload |
| severity | string | false | optional | Can be a `threat` or `breach` |
#### Runbook
| Field | Type | Unique | Required | Description |
| ----- | ------ | ------ | -------- | ------------------------------------------------ |
| link | string | false | required | Runbook link to be included in the alert payload |
### Indicators
| Field | Type | Unique | Required | Description |
| ------------ | ------ | ----------------------------------------- | -------- | ------------------------------------ |
| name | string | true, uniqueness enforced at entity level | required | Name of the indicator |
| query | string | false | required | PromQL query for the indicator |
| data\_source | string | false | optional | Data Source of the indicator (Last9) |
| description | string | false | optional | Description of the indicator |
| unit | string | false | optional | Unit of the indicator |
### Links
| Field | Type | Unique | Required | Description |
| ----- | ------ | ------ | -------- | ------------------------ |
| name | string | false | required | Display name of the link |
| url | string | false | required | URL of the link |
### Notification Channels
| Field | Type | Unique | Required | Description |
| -------- | ----------------------- | ------ | -------- | ------------------------------------------------------------------------------------------------- |
| name | string | false | required | Name of the notification channel |
| type | string | false | required | Type of notification channel. Allowed values: `slack`, `pagerduty`, `opsgenie`, `generic_webhook` |
| mention | string OR list (string) | false | optional | Only applicable to Slack. The user(s) to tag in the alert message |
| severity | string | false | optional | Severity of the alerts sent through this channel. Allowed values: `threat`, `breach` |
Before a notification channel can be used in IaC, it needs to be configured. Please see [Notification Channels](/docs/notification-channels/) for more details.
## Supported Macros by IaC
* `low_spike (tolerance, metric)`
* `high_spike (tolerance, metric)`
* `decreasing_changepoint (tolerance, metric)`
* `increasing_changepoint (tolerance, metric)`
* `increasing_trend (tolerance, metric)`
* `decreasing_trend (tolerance, metric)`
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Alerting on RUM Metrics
> PromQL alert patterns for mobile and web RUM — HTTP error rates, latency thresholds, app crashes, and ANR detection using trace_client_count, trace_client_duration, and trace_internal_count.
Last9 [RUM SDKs](/docs/real-user-monitoring/) emit three families of gauge metrics derived from spans. The same data powers [Discover → Applications](/docs/discover-applications/) for ad-hoc exploration; this guide covers turning those signals into alerts. All are gauge metrics — use `sum_over_time` for counting and `avg_over_time` for smoothing, not `rate()` or `increase()`.
## Metric reference
| Metric | Covers | Key labels |
| ----------------------- | ---------------------------------------------- | --------------------------------------------------------------------------------- |
| `trace_client_count` | HTTP requests made by the app (network spans) | `service_name`, `span_name`, `http_status_code`, `http_method`, `env` |
| `trace_client_duration` | HTTP request durations — precomputed quantiles | `service_name`, `span_name`, `http_status_code`, `http_method`, `quantile`, `env` |
| `trace_internal_count` | App lifecycle, screens, errors, ANR, resources | `service_name`, `span_name`, `status_code`, `env` |
### `http_status_code` vs `status_code`
`http_status_code` on `trace_client_count` / `trace_client_duration` is the HTTP response code the device received (`"200"`, `"404"`, `"503"`). Use this for HTTP-level alerting.
`status_code` on `trace_internal_count` is the OTel span status (`STATUS_CODE_ERROR` / `STATUS_CODE_UNSET`). Use this for app-level error alerting (crashes, ANRs).
### `trace_client_duration` quantiles
`quantile` label values: `avg`, `p50`, `p90`, `p95`, `p99`. These are precomputed — query them directly by label. No `histogram_quantile()` needed.
Duration values are in **milliseconds**.
***
## Alert patterns
### 1. HTTP error count (4xx / 5xx)
Alert when users are receiving error responses from any backend endpoint.
```promql
sum(
sum_over_time(
trace_client_count{
service_name="",
http_status_code=~"[45].."
}[30m]
)
)
```
Threshold: tune to your baseline. Start with `> 10` and adjust based on traffic. Use a shorter window (`[5m]`) for high-traffic production apps.
### 2. HTTP error ratio
Alert when a significant fraction of requests are failing. More stable than raw counts for apps with variable traffic.
```promql
sum(sum_over_time(trace_client_count{service_name="", http_status_code=~"[45].."}[30m]))
/
sum(sum_over_time(trace_client_count{service_name=""}[30m]))
```
Threshold: `> 0.05` for 5% error rate.
### 3. Per-endpoint error breakdown
Identifies which specific API endpoint is failing, useful for routing alerts to the right team.
```promql
sum by (span_name) (
sum_over_time(
trace_client_count{
service_name="",
http_status_code=~"[45].."
}[30m]
)
)
```
### 4. API latency — p95 threshold
`trace_client_duration` holds precomputed quantiles per endpoint. Query the `p95` label directly.
```promql
avg_over_time(
trace_client_duration{
service_name="",
quantile="p95",
http_status_code="200"
}[30m]
)
```
To find the worst-performing endpoint across your app:
```promql
max by (span_name) (
avg_over_time(
trace_client_duration{
service_name="",
quantile="p95",
http_status_code="200"
}[30m]
)
)
```
Threshold: set in milliseconds, e.g. `> 3000` for 3 s.
Note
WebSocket connections (`http_status_code="101"`) appear as long-lived client spans and will skew p95 values significantly — some exceeding 45 s. Add `http_status_code="200"` to latency queries to exclude them.
### 5. App crashes and exceptions (mobile)
The SDK attaches exceptions as events on the active View span and marks it `STATUS_CODE_ERROR`. Alert on View spans in error state to catch crashes and unhandled exceptions.
```promql
sum(
sum_over_time(
trace_internal_count{
service_name="",
span_name="View",
status_code="STATUS_CODE_ERROR"
}[30m]
)
)
```
Threshold: `> 0` for zero-tolerance, or tune to baseline.
Note
A standalone `exception` span is only emitted at early app startup before any screen is active. In normal operation, exceptions attach to View spans — always use the View + `STATUS_CODE_ERROR` pattern above.
### 6. ANR rate (Android)
App Not Responding events are emitted as standalone spans by the SDK’s watchdog thread when the main thread is blocked beyond the configured threshold (default: 5 s).
```promql
sum(
sum_over_time(
trace_internal_count{
service_name="",
span_name="ANR detected"
}[1h]
)
)
```
Threshold: `> 0` — any ANR is a user-facing freeze and warrants investigation.
Tip
ANRs are sparse events. Use a `[1h]` window so the alert fires within an hour of the first occurrence. A `[5m]` window will miss infrequent ANRs between scrapes.
***
## Filtering by environment
All metrics carry an `env` label populated from `deployment.environment` set at SDK init. Add it to any query to scope alerts to production only:
```promql
sum(
sum_over_time(
trace_client_count{
service_name="",
env="production",
http_status_code=~"[45].."
}[30m]
)
)
```
***
## Configuring the alert in Last9
1. Go to **Alerting → Alert Groups** and create or open an Alert Group for your app.
2. Add an **Indicator** with the PromQL above as the query.
3. Set the **threshold** and **bad minutes / total minutes** window.
4. Optionally add dynamic annotations using `{{ $labels.span_name }}` to include the failing endpoint in notifications.
See [Configuring an Alert](/docs/creating-an-alert-rule/) for the full walkthrough.
***
## Troubleshooting
* **Alert never fires despite visible errors in dashboards**
You’re likely using `rate()` or `increase()`. RUM metrics are gauges, not counters — these functions return 0 or `NaN`. Switch to `sum_over_time(...[window])` for counting and `avg_over_time(...[window])` for smoothing.
* **p95 latency values are absurdly high (30s+)**
WebSocket connections show up as long-lived client spans with `http_status_code="101"` and skew quantiles. Add `http_status_code="200"` (or exclude `"101"`) to latency queries.
* **Crash alert based on `span_name="exception"` never triggers**
A standalone `exception` span is only emitted at early app startup. In normal operation, exceptions attach to the active View span and mark it `STATUS_CODE_ERROR`. Alert on `span_name="View"` + `status_code="STATUS_CODE_ERROR"` instead.
* **ANR alert is flaky or misses events**
ANRs are sparse. A `[5m]` window will miss occurrences between scrapes. Use `[1h]` so the alert fires within an hour of the first ANR.
* **Production alert also fires on staging traffic**
Add the `env` label to the query (e.g., `env="production"`). The label is populated from `deployment.environment` at SDK init — if it’s empty, set it in your SDK configuration.
* **Error ratio query returns `NaN`**
The denominator is zero — no traffic in the window. Wrap with `or vector(0)` on the numerator, or alert only when the denominator exceeds a minimum traffic floor.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Allowed Domains
> Configure which email domains can sign up to your Last9 organization.
Allowed Domains define which email domains can sign up to your Last9 organization when it is in **Open Access** mode. Based on the email ID of the first user from your organization who signed up, everyone with an email matching the same root domain is added to the same Last9 account, and that first user becomes the associated admin.
If your organization uses multiple email domains (for example after a rebrand or acquisition), admins can add additional allowed domains directly from the UI.
## Managing Allowed Domains
1. Navigate to [Settings > Allowed Domains](https://app.last9.io/settings/allowed-domains)
2. Click **Add Domain** and enter the domain (for example `acme.com`)
3. Click **Save**
Any user with an email matching an allowed domain can sign up and access the organization, provided the organization is in Open Access mode. In [Invite Only Mode](/docs/users/#invite-only-mode), only explicitly invited users can sign in regardless of domain.
Note
Only admins can add or remove allowed domains. To change the primary root domain or the associated admin, contact .
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Anomaly Algorithms (Legacy)
> Reference for Last9's legacy Anomaly algorithms (anomalous pattern detection) and guidelines on when to use them.
Deprecated for new rules
These Anomaly algorithms can no longer be selected for **new** Alert Rules — use the **Adaptive** algorithm instead (see [Adaptive Alerting](/docs/adaptive-alerting/) and [Creating an Alert Rule](/docs/creating-an-alert-rule/#metrics--adaptive)). Existing rules keep evaluating and can still be edited.
## Supported algorithms
Last9 supports four Anomaly algorithms: **High Spike**, **Low Spike**, **Increasing Changepoint**, and **Decreasing Changepoint**. Each matches one kind of pattern and fires when it sees it.
### Spikes
A spike is a sudden jump or drop over a short window. Both variants compare each point against the last 60 minutes to decide whether the change is large enough to flag.
* **High Spike** — sudden jumps. Good for signals like 4xx counts, throughput, and edge hits.
* **Low Spike** — sudden drops. Good for signals like CPU utilization, cache hit rate, and availability.
#### Eligible signals
**High Spike**
 
**Low Spike**
  
### Changepoints
A changepoint is a sustained shift to a new level — a lasting change in pattern, not a one-off spike. A point is flagged when it sits too far from the last hour of data; a single jump (or a few) won’t trigger it.
* **Increasing Changepoint** — a sustained shift up to a higher level.
* **Decreasing Changepoint** — a sustained shift down to a lower level.
#### Eligible signals
  
## Configuring sensitivity
Each Anomaly algorithm takes a sensitivity value from 0 to 10 (decimals are accepted). The lower the value, the more sensitive the algorithm — so it triggers on smaller deviations. The rule editor’s preview simulates triggers against recent data as you adjust the query, algorithm, and sensitivity, so you can find a balance you’re comfortable with before saving.
## Choosing an algorithm
Use a pattern-matching algorithm only when a human looking at the plot can clearly mark where alerts should and shouldn’t fire. If you can’t spot the deviation by eye, no algorithm will.
1. **Define normal.** Look at the signal over a relevant span and mark where it deviates enough to alert.
2. **Identify the pattern.** Spikes and level shifts differ by signal — a sharp CPU spike may be normal, the same on a business metric may not. Know the process behind the signal.
3. **Prefer PromQL when it fits.** If the deviation can be expressed as relative values, percentages, or rollups, write it in PromQL. For example, to alert when a signal leaves the min/max of its 15-minute medians over the last 2 days (±20%):
```text
s < min_over_time(median_over_time(s)[15m])[2d]*0.8 || s > max_over_time(median_over_time(s)[15m])[2d]*0.8
```
where `s` is the signal metric.
4. **Otherwise, use an algorithm.** If the pattern can’t be expressed that way, pick the algorithm that matches it — and know its limits.
## When an Anomaly algorithm isn’t the fit
A pattern-matching algorithm only works when a human looking at the plot can clearly mark where alerts should and shouldn’t fire. Use an Anomaly algorithm for a **specific** behavior — a spike or a changepoint. For everything else, reach for a **static threshold** or **[Adaptive Alerting](/docs/adaptive-alerting/)** (the simpler, recommended path for general anomaly detection).
### Use a static threshold
For signals that sit at fixed or discrete values, or stay idle with occasional activity — a spike or trend algorithm would alert on every blip:

Mostly zero with sparse spikes.

Bursts around a fixed level with idle gaps.

A handful of discrete states (here 0, 1, 2) — alert on a specific value.
### Use Adaptive
For noisy or drifting signals that still have a learnable baseline — Adaptive models the normal band and flags deviations from it:
Continuously noisy with no fixed pattern.
Noisy, with a baseline that drifts over time.

A level that grows or steps up over time — a fixed threshold would constantly trip, but Adaptive tracks the moving baseline.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Audit Trail
> Track changes to your Last9 configuration — who did what and when — with filters by user, resource type, and action, plus CSV export
The Audit Trail records changes to your Last9 configuration — who did what and when. Use it to answer questions like “who edited this alert rule,” “when was this token created,” or “who logged in last week.”
Navigate to [Settings > Audit Trail](https://app.last9.io/settings/audit-trail) to view it. Admin access is required.
## What Gets Recorded
Each event captures the timestamp, the user who performed the action, the action itself, the resource type, and the affected resource. Recorded activity includes:
* **Logins** — every user sign-in
* **Tokens** — creation of access tokens, refresh tokens, and cluster tokens
* **Alerting** — alert rules and KPIs created or updated, with the entity they belong to, and [alert acknowledgements](/docs/acknowledge-alerts/) claimed, reassigned, or released
* **Control Plane** — drop rules and remapping settings created or changed
* **Users** — role changes and user management actions
The resource types and actions available in the filters reflect the activity that has actually occurred in your organization.
## Filtering Events
The left sidebar filters the event table by:
* **User** — one or more organization members
* **Resource Type** — e.g. Alert Rule, Access Token, Refresh Token, Drop Rule
* **Action** — e.g. Create Alert Rule, Update Alert Rule, Login
Combine filters with the **resource name search** and the **time range picker** to narrow to a specific change — for example, all alert rule updates by one user in the last 24 hours.
Click any column header to sort. Where a resource belongs to an entity (such as an alert rule on a service), the entity is shown alongside the resource.
## Exporting
Click **Download CSV** to export the currently filtered events for compliance reviews or offline analysis. The table paginates with **Load More**; the export covers the filtered result set.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Azure AD / Microsoft Entra ID SSO
> Security permissions and authentication details for signing in to Last9 with Microsoft Azure AD / Entra ID.
Last9 supports signing in with Microsoft Entra ID (formerly Azure Active Directory) using standard OpenID Connect (OIDC) authentication with minimal, user-scoped permissions.
Key Security Point
Last9 uses **only delegated permissions** scoped to the signed-in user. It does not request application-level permissions and cannot access your organization’s directory.
## Permissions Requested
Last9 requests the following **delegated permissions** from Microsoft Graph API:
| Permission | Type | Description | Admin Consent Required |
| ----------- | --------- | ----------------------------- | ---------------------- |
| `email` | Delegated | View user’s email address | No |
| `openid` | Delegated | Sign users in (enables OIDC) | No |
| `profile` | Delegated | View user’s basic profile | No |
| `User.Read` | Delegated | Sign in and read user profile | No |
All four are delegated permissions, meaning Last9 acts on behalf of the signed-in user and can only access that user’s own data. None require admin consent.
For official Microsoft documentation, see the [Microsoft Graph Permissions Reference](https://learn.microsoft.com/en-us/graph/permissions-reference).
## What Last9 Cannot Access
Last9 does **not** request any application-level or directory-scoped permissions. This means it cannot:
* Read other users’ profiles (`User.Read.All` — not requested)
* Access your organization’s directory data (`Directory.Read.All` — not requested)
* Modify any user or directory data (`User.ReadWrite.All`, `Directory.ReadWrite.All` — not requested)
* Read group memberships (`Group.Read.All` — not requested)
## How to Verify Permissions
### In the Microsoft Entra Admin Center
1. Sign in to [Microsoft Entra admin center](https://entra.microsoft.com)
2. Go to **Identity** → **Applications** → **Enterprise applications**
3. Search for and select **“Last9”**
4. Click **Permissions** under Security
5. Verify only delegated permissions (`email`, `openid`, `profile`, `User.Read`) are listed
The Permissions page shows separate **Admin consent** and **User consent** tabs. Last9 should only appear under user consent with the four permissions listed above.
## Access Control
Your organization retains full control over who can access Last9 through Entra ID SSO.
* **You control access**: Only users you authorize in Entra ID can sign in to Last9
* **Revocation**: When you disable or delete a user’s Entra ID account, they cannot initiate new sign-ins to Last9. Existing sessions may remain active until the access token expires (typically \~1 hour) unless [Continuous Access Evaluation](https://learn.microsoft.com/en-us/entra/identity/conditional-access/concept-continuous-access-evaluation) is enabled
* **No standalone accounts**: Users authenticate through your identity provider — Last9 does not maintain separate credentials
### Conditional Access
Entra ID [Conditional Access](https://learn.microsoft.com/en-us/entra/identity/conditional-access/overview) policies apply to Last9 sign-ins. This includes MFA requirements, location-based restrictions, device compliance, and sign-in risk policies.
### Restricting Access to Specific Users
To restrict Last9 to only assigned users, set **“Assignment required?”** to **Yes** on the Last9 Enterprise Application. When enabled, only users explicitly assigned to the application can sign in. See [Restrict an app to a set of users](https://learn.microsoft.com/en-us/entra/identity-platform/howto-restrict-your-app-to-a-set-of-users).
Offboarding
When an employee leaves your organization, disabling or deleting their Entra ID account (standard offboarding) prevents them from signing in to Last9. No additional steps are required.
***
## Troubleshooting
If you have questions about Last9’s Entra ID integration or need assistance verifying permissions, please contact us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io).
# Cardinality Explorer
> Identify metrics and labels impacted by cardinality.
Cardinality Explorer helps you understand how the cardinality for metrics in a Cluster is trending. This powerful feature enables you to diagnose cardinality-related challenges with your metrics.
## Using Cardinality Explorer
To view an individual metric’s cardinality contribution:
1. Navigate to **Control Plane** → **Cardinality Explore** & Select the Cluster you wish to explore  A report with all your metrics in the selected date is generated. When the current day is selected, the data shown in the table will continue to update throughout the day.
The report also highlights metrics if they have crossed or are nearing their cardinality quota limits:
* Metrics in Red have crossed their daily cardinality quota
* Metrics in Amber have crossed 80% of their daily cardinality quota
2. To view how an individual metric is contributing towards the Cluster’s cardinality, click on a metric from the table:  You can use this detail view to diagnose issues with the selected metric using:
* **Cardinality Trend:** Using this graph you can observe how the cardinality of the selected metric has trended over the last 7 days. A sudden spike or a dip may indicate unexpected changes to the cardinality of this metric
* **Cardinality Details: V**iew all the metric’s label names and their top 5 occurring label values for a selected date. Using this, you can find which labels contribute to the metric’s cardinality growth. When the current day is selected, the reported cardinality and labels shown will continue to update throughout the day
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Change Events
> Track deployment and configuration change events in Last9 to correlate them with service performance, error rates, and reliability metrics.
## Why Change Events Matter?
Deployments, config tweaks, and third-party changes move your system in ways telemetry alone can’t explain. Change events record those moments so you can line a latency spike or error burst up against what changed.
## Sending Change Events
Send an event to Last9’s HTTP API with a `start` or `stop` state. Last9 converts it into a metric named `last9_change_events` that you can query with PromQL, alert on, and see as markers on charts.
```shell
curl -XPUT https://app.last9.io/api/v4/organizations/{org_slug}/change_events \
--header 'Content-Type: application/json' \
--header 'X-LAST9-API-TOKEN: Bearer ' \
--data-raw '{
"timestamp": "2024-01-15T17:57:22+05:30",
"event_name": "new_deployment",
"event_state": "start",
"data_source_name": "{your_cluster_name}",
"attributes": {
"service_name": "frontend",
"deployment_environment": "production",
"version": "v2.1.4",
"team": "platform",
"change_type": "hotfix"
}
}'
```
Tip
Refer to the [Getting Started with API](/docs/getting-started-with-api/) guide to obtain the token required for the change events API.
### API Parameters
| Field | Description | Required |
| ------------------ | ---------------------------------------------------------------------------------------------------------- | -------- |
| `timestamp` | ISO8601 formatted timestamp of the event. Defaults to current time if not provided | No |
| `event_name` | Custom event identifier. Added as a label to the resulting time series | Yes |
| `event_state` | `start` or `stop` — marks when deployments/changes begin and complete. Defaults to `start` if not provided | No |
| `attributes` | Key-value pairs used as labels while converting the change event to a metric | No |
| `value` | Sample value for the datapoint. Defaults to `1` for a `start` event and `2` for a `stop` event | No |
| `data_source_name` | Last9 cluster to store the events in. Defaults to the cluster designated for change events | No |
Only `attributes` becomes labels. The API adds `event_name` and `event_state` itself, so every other label on a `last9_change_events` series came from what you sent in `attributes`.
Note
**Important:** Set `service_name` in `attributes` to your APM service name exactly, or events won’t appear as markers on any chart. They are still stored and queryable without it. `service` is accepted as an alias.
Set the environment in `attributes` too. Use either `deployment_environment` or `env` — the first of the two carrying a non-empty value wins, checked in that order. An empty value falls through, so `deployment_environment: ""` with `env: "production"` still resolves to production. Discover scopes the markers by this value.
Caution
Store events in the same cluster as the metrics you want to correlate them with. Markers are only found in the cluster the charts query.
## Where Change Events Appear
Events render as markers along the bottom of every timeseries chart on these surfaces:
| Surface | Scoped by service | Scoped by environment |
| ----------------------------- | -------------------------------- | --------------------- |
| **Discover** → **Services** | The service you are viewing | The **Env** selector |
| **Discover** → **Exceptions** | No — every service | The **Env** selector |
| **Dashboards** | The dashboard’s service variable | No |
### Scoping by Environment
On both Discover surfaces the **Env** selector filters the markers as well as the charts, so a production screen never shows an alpha deploy:
| Env selector | Markers shown |
| ------------ | -------------------------------------------- |
| A named env | Only events carrying that environment |
| **All** | Every event, whatever environment it carries |
| **Not Set** | Only events where neither attribute is set |
Dashboards have no **Env** selector, so dashboard panels are not scoped by environment. They scope by the service variable only.
On **Exceptions** the service stays unscoped on purpose — a spike in exceptions is often caused by a deploy to a different service — so you see every service’s events for the selected environment.
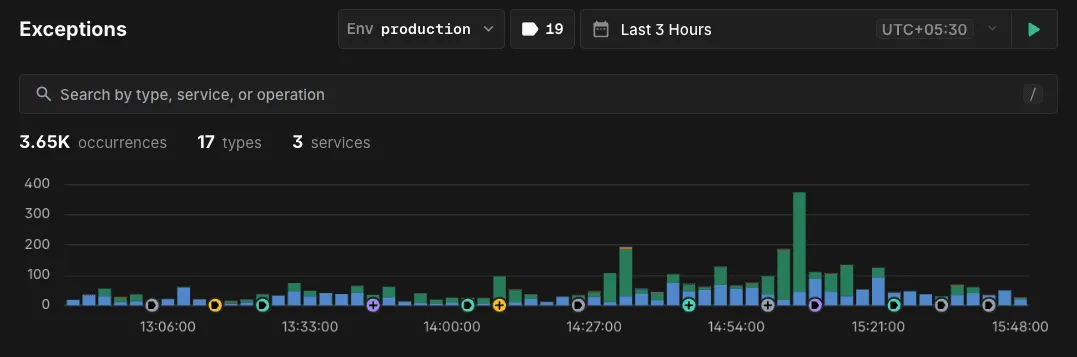
### Reading the Markers
Each marker is a coloured circle at the event’s timestamp, coloured by what Last9 infers from `event_name`:
| Order | Marker | Matched in `event_name` |
| ----- | --------------------- | ---------------------------------------------------------------------------------------------------------- |
| 1 | Amber — feature flag | `flag`, `launchdarkly`, `toggle`, `experiment` |
| 2 | Violet — deploy | `deploy`, `release`, `rollout`, `rollback`, `build`, `version` |
| 3 | Teal — infrastructure | `scal`, `restart`, `reboot`, `config`, `terraform`, `migration`, `maintenance`, `infra`, `node`, `cluster` |
| — | Slate — other | Anything else |
Three rules decide the colour:
* **Each term is a substring, not a whole word.** `redeploy` is violet and `reconfigure` is teal. The teal term is the stem `scal`, so `autoscale`, `downscale`, and `node_autoscale_up` all match it.
* **Matching ignores case.** `Deploy_Start` and `deploy_start` get the same colour.
* **The first row that matches wins, in the order above.** `flag_rollout_deploy` is amber, not violet, because the feature flag row is checked first.
Hover a marker for the event name, its timestamp, and every attribute you sent. Attribute values print exactly as you sent them, so case-sensitive identifiers like `INC-2291`, `v2.15.0-rc3`, and `last9-api` read back unchanged.
Markers too close together to draw apart collapse into one carrying a plus icon; zoom in to split them. A collapsed marker whose events do not all share one colour renders slate.
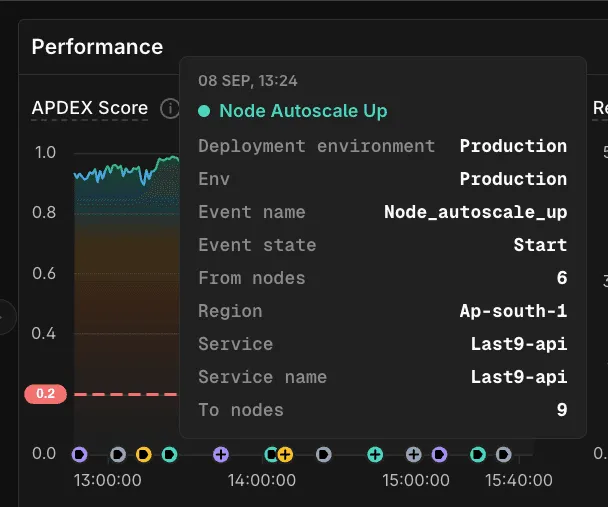
### Showing and Hiding Markers
The change events toggle sits next to the time picker in the page header.
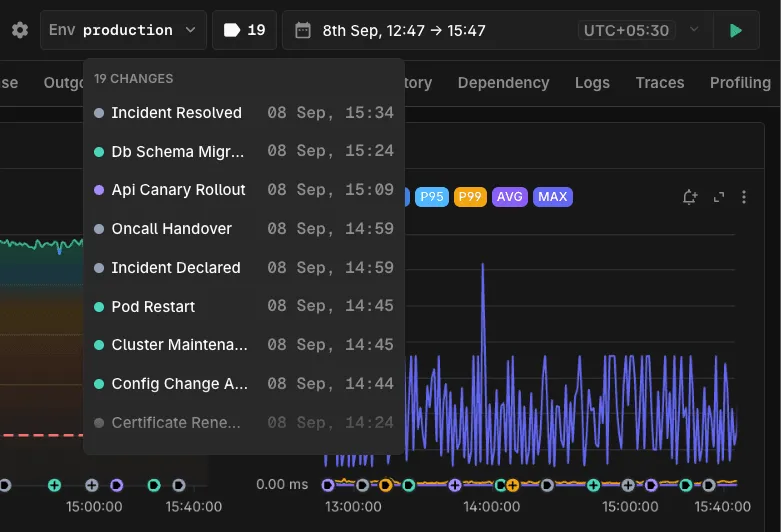
* Click it to show or hide markers on every chart at once. The state persists in the page URL, including on shared links.
* The count is events in the current range. Read it rather than counting markers — grouped markers hide their own number.
* Hover it for the full list, most recent first.
### Change Events on Dashboards
A dashboard takes its service from a variable. Markers appear only when the dashboard has a variable with **Type** set to **Label** and **Target** set to `service` or `service_name`. Static variables do not work — their values never resolve against your metrics.
See [Using Dashboards](/docs/using-dashboards/) for how to add one.
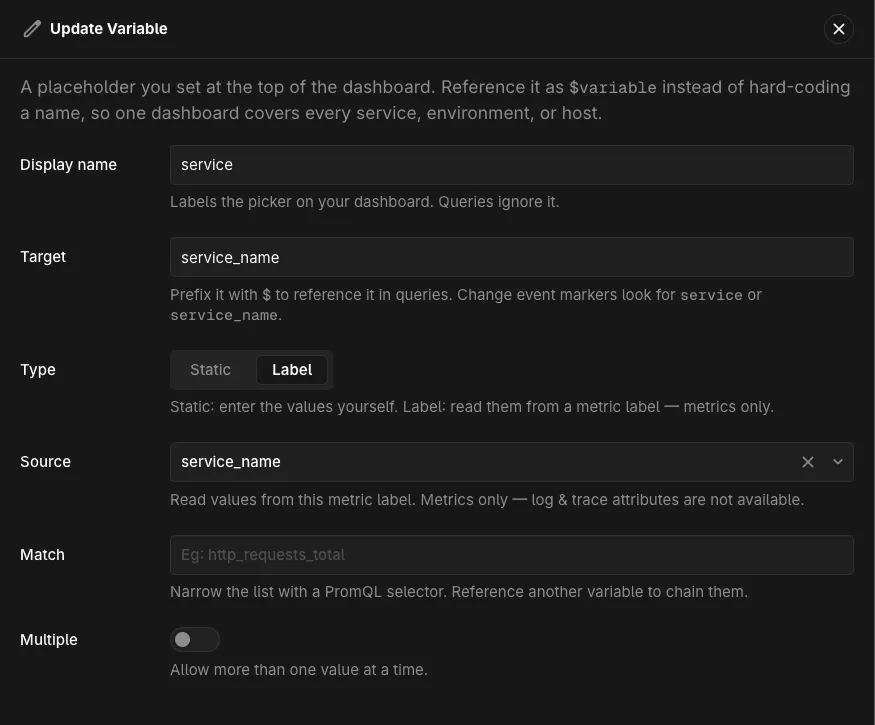
## Querying Change Events
`last9_change_events` is a metric like any other, so you can chart and slice it in [Metrics Explorer](/docs/metrics-explorer/):
```promql
last9_change_events{event_name="new_deployment", deployment_environment="production"}
```
## Event Naming Best Practices
Use consistent, descriptive names for your events:
* `deployment_start` / `deployment_complete` — for application deployments
* `config_update_redis` — for configuration changes
* `feature_flag_toggle` — for feature flag changes
* `db_migration_start` / `db_migration_complete` — for database migrations
Tip
`event_name` also decides the marker colour on charts. Keeping a word like `deploy`, `flag`, or `config` in the name gets the event the right colour instead of the neutral fallback. See [Reading the Markers](#reading-the-markers).
Add meaningful context through attributes:
```json
{
"service": "frontend",
"service_name": "frontend",
"deployment_environment": "production",
"version": "v2.1.4",
"team": "platform",
"change_type": "hotfix"
}
```
## Migrating to Last9 Change Events
If you’re already tracking deployments with another observability tool, the table below maps common concepts to their Last9 equivalents. This makes it straightforward to replace your existing deployment event calls with the Last9 API.
### Concept Mapping
| Concept in other tools | Last9 equivalent |
| ------------------------------------------------ | ---------------------------------------------------------------------------- |
| Events API / Custom Events / DORA Deployment API | `PUT /api/v4/organizations/{org_slug}/change_events` |
| Deployment markers / Annotations / Markers | Change Events with `event_state: start` and `event_state: stop` |
| `version` / `commit` / `build_id` tag | `attributes.version` |
| `service` / `entityGuid` / dataset slug | `attributes.service_name` |
| `env` / `environment` tag | `attributes.deployment_environment` |
| Event tags / dimensions / properties | `attributes` (any key-value pairs) |
| GraphQL mutations / typed deployment fields | Single REST `PUT` with flexible JSON body |
| Visual-only annotations on dashboards | PromQL-queryable metric (`last9_change_events`) with automatic chart markers |
| Region annotations / time-range markers | Separate `start` and `stop` events for the same `event_name` |
### What’s Different in Last9
* **Events become metrics.** Unlike visual-only annotations or markers, Last9 converts every change event into a Prometheus metric (`last9_change_events`). This means you can query, alert, and build recording rules on deployment events using PromQL — not just view them on a chart.
* **No entity pre-registration required.** Some tools require the target service to already exist before you can record a deployment against it. Last9 accepts events for any `service_name` immediately.
* **No timestamp restrictions.** Some tools limit event timestamps to 18–24 hours in the past. Last9 accepts any valid ISO8601 timestamp.
* **Automatic chart correlation.** When `service_name` matches your APM service, change events appear as markers on every chart for that service, with no manual dashboard configuration.
* **Flexible attributes instead of rigid schemas.** Instead of fixed fields like `deploymentType` or `entityGuid`, Last9 uses open-ended `attributes`. Add any key-value pairs relevant to your workflow (`team`, `change_type`, `rollback`, `ticket_id`, etc.).
### Example: Replacing an Existing Integration
If you’re currently sending deployment events via a `POST` to another provider’s API, the migration is typically a one-line change in your CI/CD pipeline. If you’re using GitHub Actions, the [Last9 Deployment Marker action](https://github.com/marketplace/actions/last9-deployment-marker) handles this for you without any custom `curl` steps.
```shell
# Replace your existing deployment event call with:
curl -XPUT https://app.last9.io/api/v4/organizations/{org_slug}/change_events \
--header 'Content-Type: application/json' \
--header 'X-LAST9-API-TOKEN: Bearer ' \
--data-raw '{
"event_name": "deployment",
"event_state": "start",
"attributes": {
"service_name": "'"$SERVICE_NAME"'",
"deployment_environment": "'"$DEPLOY_ENV"'",
"version": "'"$GIT_SHA"'",
"team": "'"$TEAM"'"
}
}'
```
## Native Integrations for Change Events
* [LaunchDarkly](/docs/integrations/others/launchdarkly/)
* [GitHub Actions](/docs/integrations/ci-cd/github-actions/)
***
## Troubleshooting
* **The toggle shows `0`.** On a dashboard, check for a **Label** variable targeting `service` or `service_name` — Static variables do not work. Otherwise widen the time range, or confirm the events landed in the cluster your charts query.
* **Events are queryable in PromQL but no markers appear.** The `service_name` on the event must equal your APM service name exactly, including case. Confirm what your event carries:
```promql
last9_change_events{event_name="your_event_name"}
```
If the name is right, check the toggle — the hidden state persists in the URL, including on shared links.
* **Alerting when an entity is stuck in a state.** Send a `start` event when an entity enters the state and a `stop` event when it leaves, then alert on how long it has been since the `start`. The expression returns nothing once the `stop` event arrives, so the alert resolves itself, per entity.
```promql
(
time() - timestamp(
last9_change_events{event_name="", state="", event_state="start"}[]
)
)
unless on()
last_over_time(
last9_change_events{event_name="", state="", event_state="stop"}[]
)
```
Set the alert threshold in seconds — `greater than 14400` for 4 hours.
* **Size the lookback larger than the longest stuck time you want to catch.** Each event is a single sample with no refresh, so it ages out of a short window: the series vanishes from the result and the alert silently stops firing while the entity is still stuck. A job stuck for 20 hours is invisible to `[12h]` and caught by `[48h]`. Roughly 3–4× the threshold works:
| Alert threshold | Minimum lookback |
| --------------- | ---------------- |
| 1h | 6h |
| 4h | 12h |
| 12h | 48h |
| 24h | 72h |
* **Push the start event exactly once, in real time.** `last_over_time` returns the most recent sample, so a re-pushed start event resets the elapsed time to near zero — the usual cause of an alert reading `0` or a small constant. Backdated timestamps past the database’s backfill limit are also rewritten to the ingestion time.
* **Use `count_over_time` for heartbeat-style start events.** If your system re-pushes the start event periodically rather than once on entry, count the 1-minute windows the entity spent stuck instead. Set the threshold in minutes — `greater than or equal to 240` with a `[4h:1m]` subquery for 4 hours.
```promql
count_over_time(
(
last_over_time(
last9_change_events{event_name="", state="", event_state="start"}[5m]
)
unless on()
last_over_time(
last9_change_events{event_name="", state="", event_state="stop"}[5m]
)
)[:1m]
)
```
* **Keep Group Timeseries Notifications disabled** (the default) so each entity fires and resolves on its own. With it enabled, the resolved notification waits for every entity to clear, so one long-stuck job suppresses it for all the others.
If a `stop` event never arrives — a job crashes without cleanup — the alert keeps firing until one is pushed.
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Clusters
> Overview of Clusters
## Cluster Overview
To start using Last9 you need at least one Cluster, from which you read and write metric data. In this document, we dive deep into all things related to a cluster.
To get up and running fast, see our [Quick Start Guide](/docs/onboard/).
Think of a Cluster as a logically separated, Prometheus API-compatible data source for all your metric data. You can create as many Clusters as you want, the number of clusters has no impact on your billing.
It is typically recommended that you create Clusters for each of your environments. Example: Production Cluster, Staging Cluster, etc.
## Creating a New Cluster
To create a Cluster:
1. Navigate to **Home** → **Levitate** 
2. Click the *Launch Cluster* button to launch the setup wizard 
3. Select the AWS region you would like to deploy the cluster in. This should ideally be the same region as your application
4. Give the Cluster a descriptive name
5. Optionally, add a description which will be displayed on the Cluster Overview screen 
6. Press the **Create** to create your new Cluster As the Cluster gets created, you will be presented with an access token that is automatically created. This token is required to start writing & reading data to the Cluster. Tokens are only shown once, so please copy or download credentials (or you can always create another token from Cluster settings).  Your new Cluster is now ready to receive metrics.
7. To start writing data to this new Cluster, please follow the Write Data steps start writing data from Kubernetes, Prometheus, AWS/CloudStream or quickly try out by running a local demo environment  Using the **Test Config** button you can verify if your Last9 cluster has started receiving data. Click the **Next** button to start reading data/querying metrics from your Cluster.
See our guides on how you can send data from [Prometheus](#), [OpenTelemetry](#), [VMAgent](#), or other various s[Integrations](#) supported. 8. To start reading metrics from your new Cluster you can use Managed Grafana which comes included with every plan.
Alternatively, you can use the provided **Read URL** to read data using any Prometheus HTTP API Compatible tool like AlertManager, your own Grafana, KEDA, etc. See the guide on [how to connect your own Grafana](/docs/grafana-config/) with a Last9 cluster. 
***
## Managing a Cluster
### Cluster Usage and Performance
Last9 provides the following tools to observe the Cluster’s performance:
* [Cluster Health Dashboard](#cluster-health-dashboard) - Performance & usage metrics report
* [Query Logs](#query-logs) - Identify slow-running queries
#### Cluster Usage
 Usage for each cluster is reported in *Samples Ingested*. A **sample** refers to a single data point in a time series.
Usage for each Cluster can be viewed from the Cluster’s details page. For more granular and historical usage, see the Cluster Health dashboard’s Sample Ingested panel.
#### Cluster Quotas
There are no *per-cluster* limits in Last9. You are billed for usage across all Clusters combined. The ingestion rate, read query rate, and data retention quotas are applied for all the data across all clusters.
#### Default Cluster Quotas
Last9’s default cluster quotas are fairly generous. In certain cases, keeping in mind performance and cost impacts, we may be able to increase a quota after a discussion with your team.
#### Write Quotas
| Type | Base Quota | Reset Period | Note |
| -------------------------------------------- | ---------- | ------------ | ------------------------ |
| Per Time Series Cardinality | 1M | Per Hour | Can be raised on request |
| Per Time Series Cardinality | 20M | Per Day | Can be raised on request |
| Streaming Aggregation Cardinality | 3M | Per Hour | Can be raised on request |
| Ingestion Concurrency | 20K | Per Second | Can be raised on request |
| Number of Metrics Aggregated in one Pipeline | 1 Metric | Per Query | Cannot be changed |
#### Read Quotas
| Type | Base Quota | Note |
| ------------------------------------------ | ---------- | ------------------------ |
| Time Series Scanned Per Query — Blaze Tier | 5M | Cannot be changed |
| Time Series Scanned Per Query — Hot Tier | 10M | Cannot be changed |
| Samples Scanned Per Query | 100M | Cannot be changed |
| Query Time Range — Blaze Tier | 2 Hours | Can be raised on request |
| Query Time Range — Hot Tier | 35 Days | Can be raised on request |
If you wish to change your quotas, please raise a request by emailing us on:
### Cluster Health Dashboard
Every Last9 Cluster comes with its own Health dashboard. To view the Health dashboard, navigate to the Cluster details page and click on the **View Health** link in the performance card. 
The following Cluster Performance Metrics are available in the health dashboard: 
* **Write Success** - Total successful write requests
* **Write Error** - Total failed write requests
* **Samples Ingested** - Total number of samples ingested
* **Write Availability** - Percentage of write requests successful
* **Write Latency** - Write request latency
* **Lag** - Pending samples waiting to be indexed (in bytes)
* **Read Success** - Total successful write requests
* **Read Errors** - Total failed read requests
* **Cardinality Limited** - Metrics whose cardinality has been limited
* **Read Latency** - Query Latency
* **Cardinality Limiter (Early Warning)** - Metrics whose cardinality is about to be limited
* **Bytes Dropped** - Samples permanently failed to be indexed (in bytes)
***
## Query Logs
Query Logs helps identify slow-running queries so that you can debug and optimize your PromQL.
Query Logs displays slow queries in the last 24 hours, which were successfully executed but have taken more than 1000ms (ie one second) to execute. 
When a slow query is identified the following details are displayed:
* **Timestamp** - Time when the query was executed
* **Query** - PromQL along with the query’s time range and query resolution step width
* **Latency** - approximate time taken for the query to execute
* **Token** Name - the name of the token used to query
* **Tier** - storage tier that was used for this query
***
## Cluster Settings
### Tokens
Tokens provide a mechanism for access management for your clients. We generate a default token when the Cluster is created for the first time
#### Creating a New Token
1. Navigate to the Cluster that you wish to create a token for: **Control Plane** → **Tokens** 
2. Click **New Token** 
3. Provide a descriptive **Token Name** the access **Scope** (Write Only, Read Only, Read & Write) and click **Create**
4. Copy the generated token since it will be visible only once. This token can now be used along with the Read or Write URL (depending on the Scope selected) 
#### Delete a Token
To delete/revoke a token:
1. Navigate to the Cluster that you wish to revoke a token from: \*\*Control Plane → \*\*Tokens\*\*
2. Click the **…** button and select Delete 
Note:
* This action cannot be undone, once deleted tokens cannot be recovered
* Tokens can only be deleted by your organization’s admin
### Write & Read Data
Refer to the list of available [Integrations](/docs/integrations/) that can be used to start writing and reading data to a Last9 Cluster.
### Access Policies
Last9 has built-in data-tiering capabilities based on retention policies. Access policies let you define policies to control which token or client can query a specified data tier.
See our in-depth guide on how you can leverage this powerful feature - Guide on Access Policies
#### To define a new access policy:
1. Navigate to **Control Plane** → **Access Policies**  Every cluster comes with a default access policy pre-configured.
2. To define a new policy click the Create button  Provide the following details:
* Policy Name: Give a descriptive name for this access policy
* Token: Select a specific Token for which this access policy is applied or select *Any*
* Query Client: We can identify traffic from known clients or select Any for the policy to apply from any client
* Tier: Select the Tier from which the queries will be served for this policy
And click **Create**
3. Your new access policy will be applied instantly 
#### To delete an Access Policy :
1. Select the **…** button beside the access policy you wish to delete 
2. Select **Delete** from the menu
Do Note:
* Access policies can only be deleted by the admin user(s) of your org
* Deleting an access policy may limit or lock access for a client or token, please be mindful before deleting
### Macros
Macros lets you define PromQL queries as reusable functions and use them as abstracted metric names across Grafana, Alert Manager, or the CLI
We cover how to define and use Macros in detail in [guide on PromQL Macros](/docs/promql-macros/)
#### Enabling Macros:
1. Navigate to **Control Plane** → **Macros** 
2. Write/Paste your Macro function and Click Save  We perform validation once you click Save  Once validated, we will save your Macro function. Do note that it will take upto 5 minutes for new Macros to be available for querying 
#### Deleting Macros:
1. Navigate to **Control Plane** → **Macros** 
2. Click the delete icon and click confirm
Note:
* Deleted Macros will impact any queries and dashboards where the macro functions were used
* Deleted Macros may be available for queries up to 5 minutes after they have been deleted
### Streaming Aggregation
Streaming aggregation is a powerful metric cardinality that is built-in with Last9. Refer to our [Guide on Streaming Aggregation](/docs/streaming-aggregations/) for an in-depth tutorial
# Control Plane
> Manage your data, its configurations, and its lifecycle.
## Introduction

Last9’s Control Plane offers a first-class citizen experience for developers to manage their data, its settings, and its lifecycle. This document provides an overview of the main features and functionalities available in the Control Plane user interface.
## Tools and Configurations
## [Ingestion](/docs/control-plane-ingestion/)
[Configurations for how your data is ingested into Last9](/docs/control-plane-ingestion/)
## [Storage](/docs/control-plane-storage/)
[Defaults and controls for storing and using your telemetry data](/docs/control-plane-storage/)
## [Query](/docs/control-plane-query/)
[Configure query reusability, reads, and pattern match alerts.](/docs/control-plane-query/)
## [Analytics](/docs/control-plane-analytics/)
[Understand and debug system usage and performance](/docs/control-plane-analytics/)
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Analytics
> Control Plane tools to understand and debug system usage and performance.
## Cardinality Explorer

While Last9 offers [superior defaults](/docs/managing-high-cardinality/) on per-metric per-day cardinality, you may need to identify the metrics and its labels that are impacted. Cardinality Explorer helps you understand how the cardinality for metrics and its labels is trending. This enables you to diagnose cardinality-related challenges with your metrics. [Read more](/docs/cardinality-explorer/) on how to use the Cardinality Explorer interface.
## Slow Query Logs

Quickly identify which queries are taking the longest to debug and optimize them. These queries could be originating from either Last9’s alerting, managed Grafana explore/dasboards, or from your own read workfloads. You can change the latency values on the filter to see slower queries, but the minimum is queries taking longer than 1 second. By default, logs are displayed for the last 1 hour, but the window can be customized to a maximum of last 24 hours.
## Health Dashboard

While Last9 provides an SLA of 99.9% writes and 99.5% reads, you can also view the health of Last9 by clicking on Health Dashboard. You are redirected to a system-generated Grafana dashboard with panels for availability, successes/errors, latencies, lags, bytes dropped, and more.
## Usage

View the ingestion trend and usage breakdown for your telemetry data by total and types (log, span, and metric events). By default, a summary of the last 30 days is displayed. You can select an area on the chart to zoom in or you can click on the icon in each date row of the breakdown table to view an hourly breakdown. You can also click on “Download CSV” to get a hourly breakdown for the last 30 days.
### What is an Event?
Usage numbers are shown as Total Events. Each log line, trace span, and metric sample that is ingested by Last9 is considered an event. The number of events is calculated at the ingestion layer, before the data is used by any of the ingestion pipelines like [Streaming Aggregation](/docs/control-plane-ingestion/#streaming-aggregations), [Sensitive Data](/docs/control-plane-ingestion/#sensitive-data), [Forward](/docs/control-plane-ingestion/#forward), and [Drop](/docs/control-plane-ingestion/#drop).
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Cold Storage
> Learn how to configure AWS S3 cold storage for log archival and cost optimization with Last9
Automatically archive logs older than 14 days to S3 for cost-effective storage and on-demand rehydration. You can configure cold storage for all services or only specific services.
Note
The default log retention period in Last9 is 14 days. To modify this retention period for your specific needs, please reach out to our support team at .
## Setup
1. **Create IAM Role** with permissions to the S3 bucket:
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": [
"s3:PutObject",
"s3:GetObject",
"s3:ListBucket",
"s3express:CreateSession"
],
"Resource": [
"arn:aws:s3:::",
"arn:aws:s3:::/*"
]
}
]
}
```
2. **Add Trust Relationship**:
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"Service": "s3.amazonaws.com",
"AWS": "arn:aws:iam::"
},
"Action": "sts:AssumeRole"
}
]
}
```
3. Make sure that the role session expiry is set to **minimum 4 hours**.
Note
Contact Last9 support for LAST9\_STORAGE\_USER ARN.
4. **Enable Cold Storage** Navigate to the **Buckets** tab in [Cold Storage](https://app.last9.io/control-plane/cold-storage) and add your bucket name and role ARN.

5. Once the cold storage is enabled, you can rehydrate the logs on demand. Read the [Rehydration](/docs/control-plane-rehydration/) guide for more details.
## Service-Level Backup Configuration
Navigate to the **Backups** tab in [Cold Storage](https://app.last9.io/control-plane/cold-storage) to configure which services you want to back up.
You have three options:
1. **Default (toggle off):** Data is backed up at index-level granularity only — you cannot rehydrate individual services.
2. **All Services:** Enable the **Service Level Backup** toggle and select **All Services**. All services are backed up and you can rehydrate individual services.

3. **Only Selected Services:** Enable the **Service Level Backup** toggle, select **Only Selected Services**, and pick the specific services you want to back up.

Click **Save Configuration** after making your selection.
Note
While creating a Rehydrated Index, if service-level backup is available for your selected time range, you can choose which specific services to rehydrate.
### Benefits of Service-Level Backup
* **Targeted cost optimization:** Save money where it makes sense without compromising on critical services
* **Service-appropriate retention:** Match data lifecycle to each service’s actual needs
* **Strategic resource allocation:** Invest observability resources based on service priority
* **Simplified compliance:** Apply different retention rules only where legally necessary
***
## Troubleshooting
Need help? Join our [Discord](https://discord.com/invite/Q3p2EEucx9) or email .
# Access Cold Storage Logs via AWS Athena
> Learn how to query and analyze your cold storage logs in S3 using AWS Athena's SQL interface
Last9 automatically backs up your logs to a configured S3 bucket via [Cold Storage](/docs/control-plane-cold-storage/). This doc will show you how to access and query these archived logs using AWS Athena, allowing you to perform powerful SQL-based analysis on your historical data.
## Create a database on Athena
```sql
CREATE DATABASE last9;
```
## Create a table in the database
```sql
CREATE EXTERNAL TABLE last9.logs (
`timestamp` bigint,
`traceid` string,
`spanid` string,
`traceflags` int,
`severitytext` string,
`severitynumber` int,
`servicename` string,
`body` string,
`resourceschemaurl` string,
`resourceattributes` array>,
`scopeschemaurl` string,
`scopename` string,
`scopeversion` string,
`scopeattributes` array,
`logattributes` array>
)
ROW FORMAT SERDE
'org.apache.hadoop.hive.ql.io.parquet.serde.ParquetHiveSerDe'
STORED AS INPUTFORMAT
'org.apache.hadoop.hive.ql.io.parquet.MapredParquetInputFormat'
OUTPUTFORMAT
'org.apache.hadoop.hive.ql.io.parquet.MapredParquetOutputFormat'
LOCATION
's3://customer_s3_bucket/snappy-files/'
TBLPROPERTIES ('parquet.compression'='SNAPPY');
```
## Export AWS Profile
Before running the script, ensure your AWS profile is properly configured with appropriate permissions to access both your source and destination S3 buckets, as well as Athena.
## Move logs to Athena from backup S3 bucket
Save the following Python script as `insert_data_into_athena.py`.
```python
import argparse
import boto3
import os
import pandas as pd
import tempfile
import lz4.frame
from botocore.exceptions import ClientError
class ParquetProcessor:
def __init__(self):
"""Initialize the processor using AWS credentials from environment"""
self.s3_client = boto3.client('s3')
self.athena_client = boto3.client('athena')
self.temp_dir = tempfile.mkdtemp()
def download_from_s3(self, bucket_name, prefix):
"""Download all .parquet.lz4 files from the specified S3 path"""
downloaded_files = []
try:
print(f"Searching in bucket: {bucket_name}")
print(f"Using prefix: {prefix}")
paginator = self.s3_client.get_paginator('list_objects_v2')
for page in paginator.paginate(Bucket=bucket_name, Prefix=prefix):
if 'Contents' in page:
print("\nObjects found:")
for obj in page['Contents']:
print(f"Key: {obj['Key']}")
if obj['Key'].endswith('.parquet.lz4'):
print(f"Found matching file: {obj['Key']}")
local_file = os.path.join(self.temp_dir, os.path.basename(obj['Key']))
self.s3_client.download_file(bucket_name, obj['Key'], local_file)
downloaded_files.append(local_file)
else:
print("No 'Contents' in this page")
if not downloaded_files:
print("No .parquet.lz4 files were found")
return downloaded_files
except ClientError as e:
print(f"Error downloading files: {e}")
return []
def decompress_lz4(self, file_path):
"""Decompress .parquet.lz4 file to .parquet"""
try:
output_file = file_path.replace('.lz4', '')
print(f"Decompressing {file_path} to {output_file}")
with open(file_path, 'rb') as compressed:
compressed_data = compressed.read()
decompressed_data = lz4.frame.decompress(compressed_data)
with open(output_file, 'wb') as decompressed:
decompressed.write(decompressed_data)
os.remove(file_path)
print(f"Successfully decompressed to {output_file}")
return output_file
except Exception as e:
print(f"Error decompressing file {file_path}: {e}")
return None
def convert_to_snappy(self, file_path):
"""Convert decompressed parquet to Snappy compression"""
try:
df = pd.read_parquet(file_path)
df.to_parquet(file_path, compression='snappy')
return file_path
except Exception as e:
print(f"Error converting file {file_path}: {e}")
return None
def upload_to_s3(self, bucket, prefix, file_path):
"""Upload a file to S3"""
try:
file_name = os.path.basename(file_path)
s3_key = os.path.join(prefix.rstrip('/'), file_name)
print(f"Uploading {file_path} to s3://{bucket}/{s3_key}")
self.s3_client.upload_file(file_path, bucket, s3_key)
return True
except Exception as e:
print(f"Error uploading file: {e}")
return False
def cleanup_local_files(self, snappy_files):
"""Clean up temporary local files"""
for file in snappy_files:
try:
os.remove(file)
except Exception as e:
print(f"Error removing file {file}: {e}")
os.rmdir(self.temp_dir)
def process_files(self, source_bucket, source_prefix, snappy_destination, athena_results_location=None):
"""Main process to handle the complete workflow"""
# Download LZ4 files
lz4_files = self.download_from_s3(source_bucket, source_prefix)
if not lz4_files:
print("No .parquet.lz4 files found")
return
# Decompress LZ4 files
decompressed_files = []
for file in lz4_files:
decompressed_file = self.decompress_lz4(file)
if decompressed_file:
decompressed_files.append(decompressed_file)
if not decompressed_files:
print("No files were successfully decompressed")
return
# Convert to Snappy
snappy_files = []
for file in decompressed_files:
snappy_file = self.convert_to_snappy(file)
if snappy_file:
snappy_files.append(snappy_file)
if not snappy_files:
print("No files were successfully converted to Snappy")
return
# Upload to snappy destination
dest_bucket = snappy_destination.split('//')[1].split('/')[0]
dest_prefix = '/'.join(snappy_destination.split('//')[1].split('/')[1:])
for file in snappy_files:
if not self.upload_to_s3(dest_bucket, dest_prefix, file):
print(f"Failed to upload {file}")
continue
# Cleanup local files
self.cleanup_local_files(snappy_files)
print("Processing completed successfully")
if __name__ == "__main__":
parser = argparse.ArgumentParser(description='Process .parquet.lz4 files and upload to S3')
# S3 and Athena configuration
parser.add_argument('--source-bucket', required=True, help='Source S3 bucket name where parquet.lz4 (last9 saves archives)')
parser.add_argument('--source-prefix', required=True, help='Source S3 prefix path where parquet.lz4 files are stored')
parser.add_argument('--snappy-destination', required=True, help='S3 path for converted snappy files')
parser.add_argument('--athena-results', required=True, help='S3 path for Athena query results')
args = parser.parse_args()
processor = ParquetProcessor()
processor.process_files(
source_bucket=args.source_bucket,
source_prefix=args.source_prefix,
snappy_destination=args.snappy_destination,
athena_results_location=args.athena_results
)
```
The script `insert_data_into_athena.py` is used to process `.parquet.lz4` files from the backup bucket and upload them to a separate S3 location for processing in Athena.
### Help Command
Run the following command to see all available options and parameters:
```bash
python insert_data_into_athena.py --help
```
### Usage
```plaintext
usage: insert_data_into_athena.py [-h] --source-bucket SOURCE_BUCKET
--source-prefix SOURCE_PREFIX --snappy-destination SNAPPY_DESTINATION --athena-results ATHENA_RESULTS
Process .parquet.lz4 files and upload to S3
options:
-h, --help show this help message and exit
--source-bucket SOURCE_BUCKET Source S3 bucket name where parquet.lz4
(where Last9 saves backup files)
--source-prefix SOURCE_PREFIX Source S3 prefix path where parquet.lz4 files are stored
--snappy-destination SNAPPY_DESTINATION
S3 path for converted snappy files
--athena-results ATHENA_RESULTS S3 path for Athena query results
```
### Example Command
Here’s a sample command that processes files from your backup bucket to prepare them for Athena queries:
```bash
python insert_data_into_athena.py \
--source-bucket last9_backup_bucket \
--source-prefix "path/to/file/" \
--snappy-destination "s3://customer_s3_bucket/snappy-files" \
--athena-results "s3://customer_s3_bucket/athena-results/"
```
In this example:
* `last9_backup_bucket` is your source bucket containing the archived logs
* `path/to/file/` is the directory path where your .parquet.lz4 files are located
* `s3://customer_s3_bucket/snappy-files` is where the converted files will be stored
* `s3://customer_s3_bucket/athena-results/` is where Athena will store query results
## Check result on Athena
After the data has been uploaded, you can query it using Athena with the following SQL:
```sql
SELECT * FROM last9.logs;
```
This will retrieve all logs from the `last9.logs` table, allowing you to verify that your data has been successfully uploaded and is accessible through Athena.
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Drop
> Drop unwanted telemetry at ingestion layer using Control Plane

Order of Last9's pipeline processing.
[Drop](https://app.last9.io/control-plane/drop) lets you discard unwanted telemetry that you don’t want to store and query, at runtime — no code changes, no redeploys, no policy updates. For example, if you need debug logs during an incident, just remove the drop rule. It’s a faster, simpler alternative to code-level governance.
Data Loss Warning
Dropped data is **not ingested** and **cannot be recovered**. Always use the preview button to verify your filters match the intended data before saving.
## Create a Drop Rule
Head to the [Control Plane](https://app.last9.io/control-plane/drop) and click **NEW RULE**.

### Step 1: Select Telemetry Type
Choose the type of telemetry you want to drop:
| Telemetry | Filter By |
| ----------- | --------------------------------------- |
| **Metrics** | Metric name only |
| **Logs** | Attributes and resource attributes |
| **Traces** | Span attributes and resource attributes |
### Step 2: Define Filters
Add one or more filter conditions. Multiple filters are combined using **AND** logic — all conditions must match for data to be dropped.

#### Filter Operators
| Operator | Symbol | Description |
| ---------- | ------ | ------------------------------------------ |
| Equals | `==` | Exact match |
| Not Equals | `!=` | Does not match |
| Regex | `=~` | Pattern matching using regular expressions |
#### Filter Keys (Logs & Traces)
For logs and traces, filter keys use the OpenTelemetry attribute format:
* `attributes["key"]` — Span or log attributes (e.g., `attributes["http.status_code"]`)
* `resource.attributes["key"]` — Resource-level attributes (e.g., `resource.attributes["service.name"]`)
### Step 3: Preview & Verify
Before saving, use the preview button to verify matching data. The button label changes based on telemetry type:
* **Metrics**: Click **VIEW IN DASHBOARD** → Opens Grafana with matching metric query
* **Logs**: Click **VIEW LOGS** → Opens Logs Explorer with matching filters
* **Traces**: Click **VIEW TRACES** → Opens Traces Explorer with matching filters
### Step 4: Name & Save
Give your rule a unique name and click **SAVE**. Rule names must be unique within your organization.
Note
Drop rules take **1-2 minutes** to take effect after saving.
## Examples
### Drop debug logs from development environment
| Field | Value |
| --------- | ------------------------------------------------------------------ |
| Telemetry | Logs |
| Filter 1 | `resource.attributes["deployment.environment"]` `==` `development` |
| Filter 2 | `attributes["level"]` `==` `debug` |
### Drop health check traces
| Field | Value |
| --------- | --------------------------------------------- |
| Telemetry | Traces |
| Filter | `attributes["http.route"]` `=~` `.*/health.*` |
### Drop specific metric
| Field | Value |
| --------- | ---------------------------------- |
| Telemetry | Metrics |
| Filter | Name `==` `go_gc_duration_seconds` |
## Manage Existing Rules
All your drop rules are displayed in a table below the create form. To manage a rule:
1. Click the **three-dot menu** (⋮) on the rule row
2. Select an action:
* **Edit**: Opens the rule in the form for modification
* **Delete**: Removes the rule (requires confirmation)
Note
Deleting a drop rule resumes ingestion of previously dropped data. Changes take **1-2 minutes** to take effect.
## Constraints
* **Unique names**: Each drop rule must have a unique name
* **AND logic only**: Multiple filters are combined with AND (all must match)
* **Ingestion limits**: Your organization may have limits on the total number of ingestion rules
* **Regex validation**: When using the `=~` operator, the value must be a valid regular expression
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Forward
> Forward telemetry data to object storage backends without storing it in Last9

Order of Last9’s pipeline processing.
The Forward feature allows you to send telemetry data directly to external object storage like AWS S3 without storing it in Last9. This is particularly useful for compliance data that needs long-term storage but isn’t frequently queried.
Access the [Forward](https://app.last9.io/control-plane/forward) feature in your Control Plane.
## Prerequisites
Before creating forward rules, you’ll need:
* An AWS S3 bucket configured for Last9 access
* IAM AssumeRole permissions set up for Last9
* Understanding of which telemetry data you want to forward
## Configure AWS S3 Backend
1. Navigate to your Control Plane → [Cold Storage](https://app.last9.io/control-plane/cold-storage)
2. Configure your S3 bucket details and IAM AssumeRole ARN
3. Save the configuration

Learn more about setting up [IAM AssumeRole for AWS S3](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user.html) in AWS documentation.
## Create Forward Rules
Forward rules determine which telemetry data gets sent to your configured storage backend.
1. In your Control Plane, navigate to **Forward** and click **New Rule**
2. Configure matching filters using `==` or `!=` operators to specify which data to forward
3. Click **View Logs** to preview which data matches your filters
4. Save your forward rule once you’ve verified the filter criteria and added an identifiable rule name

### Filter Configuration
Use matching filters to specify exactly which data to forward:
* **Equal (`==`)**: Forward data that matches the specified value
* **Not equal (`!=`)**: Forward data that doesn’t match the specified value
**Example filters:**
```plaintext
service.name == "payment-service"
log.level != "debug"
```
Data that matches forward rules is **not stored in Last9** and cannot be recovered. Always verify your filters using “View Logs” before saving.
## Supported Data Types
Forward currently supports:
* **Logs**: Application logs, system logs, structured log data, etc
**Supported storage backends:**
* AWS S3 (with more backends planned)
## Multiple Forward Rules
You can create multiple forward rules for different data types or services. Each rule operates independently and can forward to different storage backends.
## Best Practices
* Start with specific filters to avoid forwarding more data than intended
* Use the preview feature to verify your filter logic before enabling rules
* Monitor your S3 storage costs as forwarded data accumulates
* Consider data retention policies for your S3 bucket
* Test forward rules with non-critical data first
Note
Forwarded telemetry is automatically compressed and stored in `.gz` format in your configured storage backend.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Ingestion
> Control Plane tools to configure for how your data is ingested into Last9.
Ingestion is the second pillar of our telemetry data platform, Last9. Once you‘ve [instrumented](/docs/integrations/) your system, controls over how your telemetry data flows in to Last9 do a fair bit of heavy lifting.
## Ingestion Tokens

Ingestion Tokens authenticate your applications when sending telemetry data to Last9. These tokens control what data can be sent and from which origins, ensuring secure data collection.
A system-generated ingestion token is created when you signup — this token is used in the setup wizard to help you configure sending data to Last9. System-generated tokens cannot be deleted.
Note
Only Admins can create and delete ingestion tokens. Integration credentials and tokens are masked for non-admin users. See [Users](/docs/users/) for details on role-based permissions.
## Access Policies

Setup how various clients access your data — depending on the client type and token used, you can control from which tier (blaze, hot, cold) your data is queried. We recommend alerting workloads to always use the Blaze Tier and reporting workfloads to use the Cold Tier. [Read more](/docs/access-policies/) on how to configure these policies.
## Streaming Aggregations

Streaming Aggregations allow you to transform data in real-time at the ingestion layer before it is stored in Last9. They enable you to generate scoped metrics on runtime without any instrumentation changes and improve performance of your read queries by controlling cardinality of the new metrics. [Read more](/docs/streaming-aggregations/) on how to configure these aggregations.
***
Note
The following configurations are applied in the same sequence as presented. Your telemetry data is first scanned for sensitive data, then matching data is forwarded, and then any matching data is dropped. These configurations allow you to not make any instrumentation level changes and give you a more run-time control.
## Sensitive Data

Redact sensitive data from your telemetry data at time of ingestion. Currently supported:
* Telemetry Type: Logs
* Actions: Redact (default), No Action
Last9 provides built-in scan rules for PII like emails, phone numbers, and credit card numbers. While the default action is to redact, you can also choose to take no action. This is particularly helpful when you just want to attach additional labels to the telemetry.
Configured rules are applied in a sequential order. Once saved, you can drag-and-drop to reorder the rules.
## Forward

While data after applicable retention periods can be moved to your configured S3 bucket for [Cold Storage](/docs/control-plane-storage/#cold-storage), you can also configure rules with `==` and `!=` matching filters to forward incoming data directly to your cold storage without being ingested and stored. To verify the filters before saving the rule, you can click on “View in Dashboard”.
Do note, this data will not be available for querying when forwarded, but once [rehydrated](/docs/control-plane-storage/#rehydration), it can be queried.
Supported telemetry types: Logs and Traces.
## Drop

You can configure rules with `==` and `!=` matching filters to drop incoming data. Do note, this data is not ingested and cannot be recovered as well. To verify the filters before saving the rule, you can click on “View in Dashboard”.
Supported telemetry types: Logs, Metrics and Traces.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Query
> Control Plane tools for query-level configurations.
## Macros

They work in a way that is similar to how SQL developers use stored procedures. Macros take full advantage of the time-tested best practices of functions, abstractions, and reusability to replace cumbersome and error-prone methods.
Simplify your PromQLs that are reused often to avoid repition of code, and improve abstractions and readability. [Read more](/docs/promql-macros/) on how to configure these macros.
## Scrape Interval
Set this to the typical scrape and evaluation interval configured in your agent’s config file. If you set this to a greater value than your agent’s config file interval, the embedded Grafana in Explore will evaluate the data according to this interval and you will see less data points.
Notes:
* Defaults to 1m.
* This does not change your agent’s scrape interval.
## Read Data

If you’re looking to use your stored telemetry data outside of Last9’s [Alerting](https://app.last9.io/alert-studio) or [Managed Grafana](https://app.last9.io/explore), you can refer to the Read Data settings to configure your choice of visualization tool.
For additional settings on how to configure your own Grafana to use Last9 as a datasource, [read this](/docs/grafana-config/).
## Scheduled Search

Create periodic searches on telemetry data and set alerts when patterns are found or missing. [Read more](/docs/scheduled-search/) on how configure these alerts.
Supported telemetry types: Logs, and Traces coming soon.
## Query Tokens

Query Tokens provide read-only access to your telemetry data for external visualization tools like Grafana, alerting systems, and custom applications.
A system-generated query token is created when you signup — this token is used to set up dashboard templates, including the Health Dashboard. System-generated tokens cannot be deleted.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Rehydration
> Rehydrate logs from cold storage to query historical data beyond your retention period
Rehydration allows you to retrieve logs from your cold storage back into Last9 for querying. This feature enables you to access historical log data that’s beyond your organization’s retention period.
Access the [Rehydration](https://app.last9.io/control-plane/rehydration) feature in your Last9 Control Plane.

## Prerequisites
Before you can rehydrate logs, ensure that:
* [Cold Storage](/docs/control-plane-cold-storage/) is enabled for your organization
## Creating a Rehydrated Index
1. Navigate to [Rehydration](https://app.last9.io/control-plane/rehydration) in the Control Plane
2. Click **New Rehydrated Index** to open the configuration modal
3. Configure your rehydration settings:
1. **Select Source**: Select from available indexes (typically “Default Index”) 
2. **Add Definition**: 
* **Time Range**: Choose a time period from before your retention period. If your organization has a 14-day retention, you can only select dates older than 14 days
* **Services to Rehydrate**: If service-level backup is enabled in your cold storage, you can select specific services to rehydrate instead of all logs
* **Estimated Size**: Review the estimated compressed size of data to be rehydrated
3. **Set Destination Details**: 
* **Rehydrated Index Name**: Provide a descriptive name for easy identification
* **Send Notification When Ready** (Optional): If you have email channels configured in your organization settings, you can enable notifications to receive updates when the rehydration job completes
4. Click **Rehydrate Index** to start the process
The rehydration job will appear in your index list with an “Index is being rehydrated” status.
## Understanding Rehydrated Index States

Your rehydrated indexes can have several different states:
* **Index is being rehydrated**: Process is currently running
* **Available**: Index is ready for querying, shows availability window
* **Expired**: Index has passed its retention period and is no longer queryable
* **Failed**: Rehydration process encountered an error and needs to be retried
## Querying Rehydrated Data
Once your rehydration is complete and shows “Available” status:
1. Click the **View in Logs** button next to your rehydrated index
2. This opens the Log Explorer with:
* Your rehydrated index pre-selected
* Time range set to the last 5 minutes of your rehydrated data window
3. You can now modify the time range and apply filters to explore your rehydrated data
4. Click on Run Query or use the `cmd/ctrl + enter` shortcut
Note
When querying a rehydrated index, the [time range picker](/docs/time-range-picker/) is restricted to the index’s time window. You will only be able to select time periods that fall within the rehydrated data range.
## Managing Rehydrated Indexes
Each rehydrated index includes management options accessible through the more (⋯) menu:
* **Rehydrate**: Create a new rehydration job for the same time period
* **Delete**: Remove the rehydrated index to free up storage
## Best Practices
* **Selective Rehydration**: When service-level backup is available, rehydrate only the services you need to reduce processing time and storage costs
* **Naming Convention**: Use descriptive names that include the date range and purpose, such as `incident_analysis_june_2025` or `compliance_audit_q1_2025`
* **Time Range Planning**: Remember that you can only rehydrate data from before your retention period. Plan accordingly when investigating incidents or conducting analysis
***
## Troubleshooting
* **Index Failed to Rehydrate**: If you see a “Failed — Rehydration Process Failed, Please Retry” message, select “Retry” from the more (⋯) menu or try creating a new rehydration job with the same parameters. If the issue persists, contact support
* **No Data Available**: Ensure your cold storage contains data for the selected time range and that the time range is before your retention period
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Remapping
> Transform and standardize your logs and traces data by extracting and mapping fields for better searchability and analysis.

Order of Last9’s pipeline processing.
[Remapping](https://app.last9.io/control-plane/remapping) allows you to standardize your **logs and traces** data by extracting fields and mapping them to consistent formats. This powerful feature helps you normalize data across different services and sources, making your telemetry more searchable and easier to analyze.
Note
Remapping works identically for both logs and traces. The same rules and configurations apply to both telemetry types.
Tip
Remapping configurations are real-time and do not need any instrumentation or code changes, nor any re-deployment.
Remapping consists of two primary functions:
1. **Extract**: Pull specific fields or patterns from your log lines
2. **Map**: Transform extracted fields into standardized formats
This capability is valuable for scenarios like:
* Normalizing different service names across your infrastructure
* Standardizing severity levels from various sources (ERROR, err, Fatal, 500)
* Creating consistent environment labels (prod, production, prd)
* Extracting structured data from JSON or pattern-based logs
* Maintaining consistent field naming conventions
## Attribute Priority Order
When mapping multiple source attributes to a single target attribute, the **order of preference is left to right**. The system evaluates attributes in sequence and uses the first non-empty value found.
**Example:** If you configure Service mapping with three source attributes:
| Position | Source Attribute | Value |
| -------------- | ---------------------------- | ---------------- |
| 1st (leftmost) | `attributes["service_name"]` | `""` (empty) |
| 2nd | `attributes["app_name"]` | `"checkout-api"` |
| 3rd | `resource["service.name"]` | `"checkout"` |
**Result:** Service is set to `"checkout-api"` because it’s the first non-empty value when evaluated left to right.
Tip
When adding multiple source attributes, place your preferred/most reliable source first (leftmost) in the list.
## Working with Remapping
### Extract

1. Navigate to [Control Plane > Remapping](https://app.last9.io/control-plane/remapping)
2. Select the “Extract” tab
3. View existing extraction rules in the table showing:
* Name: Descriptive name of the extraction rule
* Method: JSON or Pattern Match extraction method
* Scope: Which lines the extraction applies to
* Fields/Pattern: Which fields or patterns to extract
* Action: How the extracted data is handled (Upsert/Insert)
* Active Since: When the rule was activated
4. Click ”+ NEW RULE” to create a new extraction rule
#### Creating a New Extraction Rule
1. Select “Extraction Method”:
* **JSON:** Extract fields from structured JSON logs
* **Pattern Match:** Use regex patterns to extract fields from unstructured logs
2. Choose “Extraction Scope”:
* **All Lines:** Apply extraction to every log line
* **Lines that match:** Apply only to lines matching specific criteria
3. Field(s) to Extract:
1. For JSON method:
* Select the field(s) to extract
* Example fields: requestId, thread\_id, logger\_name, etc.
2. For Pattern Match method:
* Enter the regex pattern in “Pattern to Extract” field
* Example: `timeseries:\s*(?P\d+)`
4. Set “Action” to “Upsert” (update if exists, insert if not) or “Insert”
5. Choose “Extract Into” option:
* **Log Attributes:** Adds fields to the log’s searchable attributes
* **Resource Attributes:** Adds fields to the resource’s metadata
6. Optionally add a “Prefix” to extracted field names
* Example: “ec2\_” would transform “id” to “ec2\_id”
7. Enter a descriptive “Rule Name”
8. Click “SAVE” to activate the rule
### Map

1. Navigate to [Control Plane > Remapping](https://app.last9.io/control-plane/remapping)
2. Select the “Map” tab
3. View “Remap Fields” section with existing mappings
4. Map common fields to standardized formats:
* **Service:** Map various service names to consistent values
* Example: `attributes["service_name"]`
* **Severity:** Map different log levels to standard severity
* Example: `attributes["level"]` and `attributes["levelname"]`
* **Deployment Environment:** Map environment indicators
* Select from available attributes
5. Preview the mapping results in the “Preview (Last 2 mins)” section below
* SERVICE: How service names appear after mapping
* SEVERITY: Standardized severity levels
* DEPLOYMENT ENV: Normalized environment names
* LOG ATTRIBUTES: Other log details
* RESOURCE ATTR: Resource-related information
6. After configuring mappings, click “SAVE”
## Example Use Cases
### Logs
1. **Standardizing Service Names**: Map various service identifiers to consistent names
* Raw values: “auth-svc”, “auth\_service”, “authentication”
* Mapped to: “authentication-service”
2. **Normalizing Severity Levels**: Create consistent severity levels across sources
* Raw values: “ERROR”, “err”, “Fatal”, “500”
* Mapped to: “ERROR”
3. **Extracting Thread Information**: Pull thread details from logs for better filtering
* Extract fields: thread\_id, thread\_name, thread\_priority
* Makes thread-based troubleshooting more efficient
4. **Environment Consistency**: Standardize environment naming
* Raw values: “dev”, “development”, “preprod”, “staging”
* Mapped to consistent environment names
### Traces
1. **Service Name Standardization**: Ensure consistent service names across spans
* Source attributes: `resource["service.name"]`, `attributes["service"]`
* Map to standardized service names for cleaner service maps
2. **Deployment Environment**: Tag traces with environment information
* Source: `resource["deployment.environment"]`, `attributes["env"]`
* Standardize to: “production”, “staging”, “development”
3. **Span Operation Normalization**: Consistent operation naming across services
* Different frameworks may use varying conventions for span names
* Map to consistent operation names for easier filtering in [Traces Explorer](/docs/traces-explorer/)
## Tips for Effective Remapping
* **Start Simple:** Begin with the most common fields you search by
* **Use Consistent Naming:** Follow a naming convention for all mapped fields
* **Check Preview Results:** Use the preview section to verify your mappings work as expected
* **Mind the Order:** Attributes are evaluated left to right—place your most reliable source first
* **Use JSON When Possible:** JSON extraction is more reliable for structured logs
* **Test Pattern Matches:** Validate regex patterns before implementing them
* **Apply to Both Signals:** The same remapping rules work for both logs and traces
***
## Troubleshooting
If your remapping rules aren’t working as expected:
1. Check the extraction pattern syntax for errors
2. Verify field names match exactly what appears in your logs
3. Ensure your extraction scope is appropriate
4. Look at the preview to confirm data is flowing as expected
5. Try simplifying complex regex patterns
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Sensitive Data
> Redact sensitive data from telemetry at ingestion layer using Control Plane

Order of Last9's pipeline processing.
[Sensitive Data](https://app.last9.io/control-plane/sensitive-data) automatically detects and redacts personally identifiable information (PII) and other sensitive data from your telemetry at ingestion time — no code changes, no redeploys, no policy updates. For example, if customer phone numbers start appearing in your logs, just create a redaction rule to automatically replace them with asterisks. It’s a faster, simpler alternative to code-level data sanitization.
## Create new sensitive data rule
Head to the Control Plane and create a new Sensitive Data Rule.

You can configure rules to scan for different types of Personal Identifiable Information (PII) including email addresses, phone numbers, and credit card numbers. When sensitive data is detected, you can choose to redact it (replace with asterisks) or take no action. Additional labels can be attached to matching samples for filtering and alerts.

## Configuration Options
### Telemetry Data
Currently supported telemetry type is **logs only**. All samples for the selected telemetry data will be scanned using the configured rules.
### Scan Rules
Choose which types of sensitive data to detect:
* **Email** - Detects email addresses in your log data
* **Phone Number** - Identifies phone numbers across various formats
* **Credit Card Number** - Finds credit card numbers and payment card data
### Actions
Available actions for detected sensitive data:
* **Redact** - Replace matching sensitive data with asterisks (**\***)
* **No Action** - Detect and label but don’t modify the data
### Additional Labels
Add custom labels (key:value pairs) to samples containing sensitive data. These labels can be used for filtering, alerting, and downstream processing. Common examples:
* `sensitive_data: true`
* `redacted: true`
* `pii_type: phone`
## Supported Telemetry Types
Currently supported telemetry type is **logs**. Support for metrics and traces will be added in future releases.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Storage
> Control Plane tools for defaults and configuring how your telemetry data is stored and re-used.
## Sampling, Tiering, and Retention
1. **Sampling:** Last9 applies no sampling on your data to ensure an accurate representation of your system’s health.
2. **Data Tiering:** Last9 offers automated data tiering by default for your metrics data, including ones generated by the traces-to-metric and logs-to-metric pipelines.
* *Blaze Tier:* Last 2 hours
* *Hot Tier:* Last 28 days
* *Cold Tier:* As per your Cold Storage
3. **Retention:** Metrics data is retained for 90 days by default with cold storage for backup. Logs and Traces data is retained for 14 days with cold storage for backup and on-demand rehydration.
## Cold Storage

For your logs and traces, Last9 currently offers an integration with your AWS S3 bucket to store data older than 15 days. This data will be available for on-demand rehydration to run queries and report on.
Read the [Cold Storage](/docs/control-plane-cold-storage/) guide for more details.
## Rehydration
The historical logs can be rehydrated for later consumption as needed. You can rehydrate based on a time range filter.
Additionally for live debugging use cases, Last9 performs automatic rehydration of logs upto 10M log lines when the requested time range is beyond the retention period.
Read the [Rehydration](/docs/control-plane-rehydration/) guide for more details.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Create a GCP service account with read-only access
> Step by step guide to create a GCP service account with read-only access for monitoring
## Objective
A service account is required to access GCP environment resources for monitoring. This doc provides step by step information on creating a GCP service account with monitoring read-only access.
Once you have created the account, share the configuration with Last9 team so that the monitoring data can be sent to [Last9](https://last9.io/).
## Prerequisites
* Go to the Google Cloud Console ([console.cloud.google.com](https://console.cloud.google.com/)) account
* Select the project in which you want to create the service account
* Click on the “IAM & Admin” tab in the left navigation menu
* Click on the “Service Accounts” tab 
Note
For a GCP Project, ensure that you have access to create credentials and grant permissions.
## Creating Service Account
* Click on the “Create Service Account” button
* Enter following details
1. Service Account Name: `last9-monitor`
2. Service Account ID: `last9-monitor`
3. Service Account Description: *Allows Last9 API access to read resource metadata and monitoring data*
* Click on the “Create and Continue” button 
## Monitoring Viewer Role
Grant Permissions to this Service Account with Role as `Monitoring Viewer`.

Grant other users internal to your organization access to this Service Account(Optional) 
## Generate Credentials
* Click on the newly created Service Account to view more details 
* Create a new Service Account Key  
* Share the downloaded key with your Last9 team
# Creating an Alert Rule
> A step-by-step guide to creating metrics and log Alert Rules in Last9 using the rule editor with a live firing preview.
You create and edit both **metrics** and **log** rules in the Alert Rule editor. It pairs a live preview, which simulates when the rule would have fired against recent data, with a **Query**, **Condition**, **Notifications**, and **Rule Settings** form.
## Picking an Alert Group
From the [Rules](/docs/alert-rules/) page, click **Create**. You first pick the [Alert Group](/docs/alert-rules/#alert-groups-view) the rule belongs to:
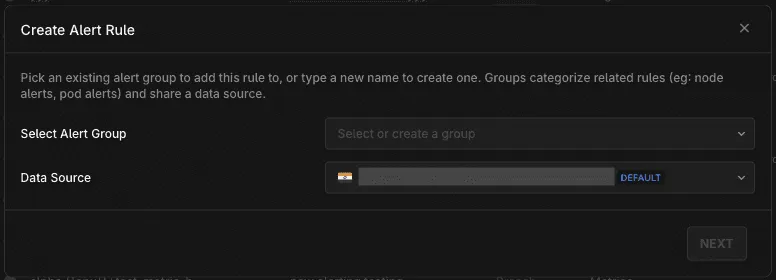
* **Select Alert Group** — choose an existing group, or type a new name to create one. Groups categorize related alerts (for example, node alerts or pod alerts) and share a data source.
* **Data Source** — the metrics source the rule queries. It is inherited from the group; the group’s default is marked accordingly.
Click **Next** to open the editor. To edit an existing rule, use the **Edit** row action on the Rules page instead.
## Query
Choose the telemetry type — **Metrics** or **Logs** — from the dropdown at the top of the Query section. Each type offers two modes:
* **Builder** — a guided, no-code way to construct the query in stages.
* **PromQL** / **LogQL** — write the query directly, with auto-complete suggestions.
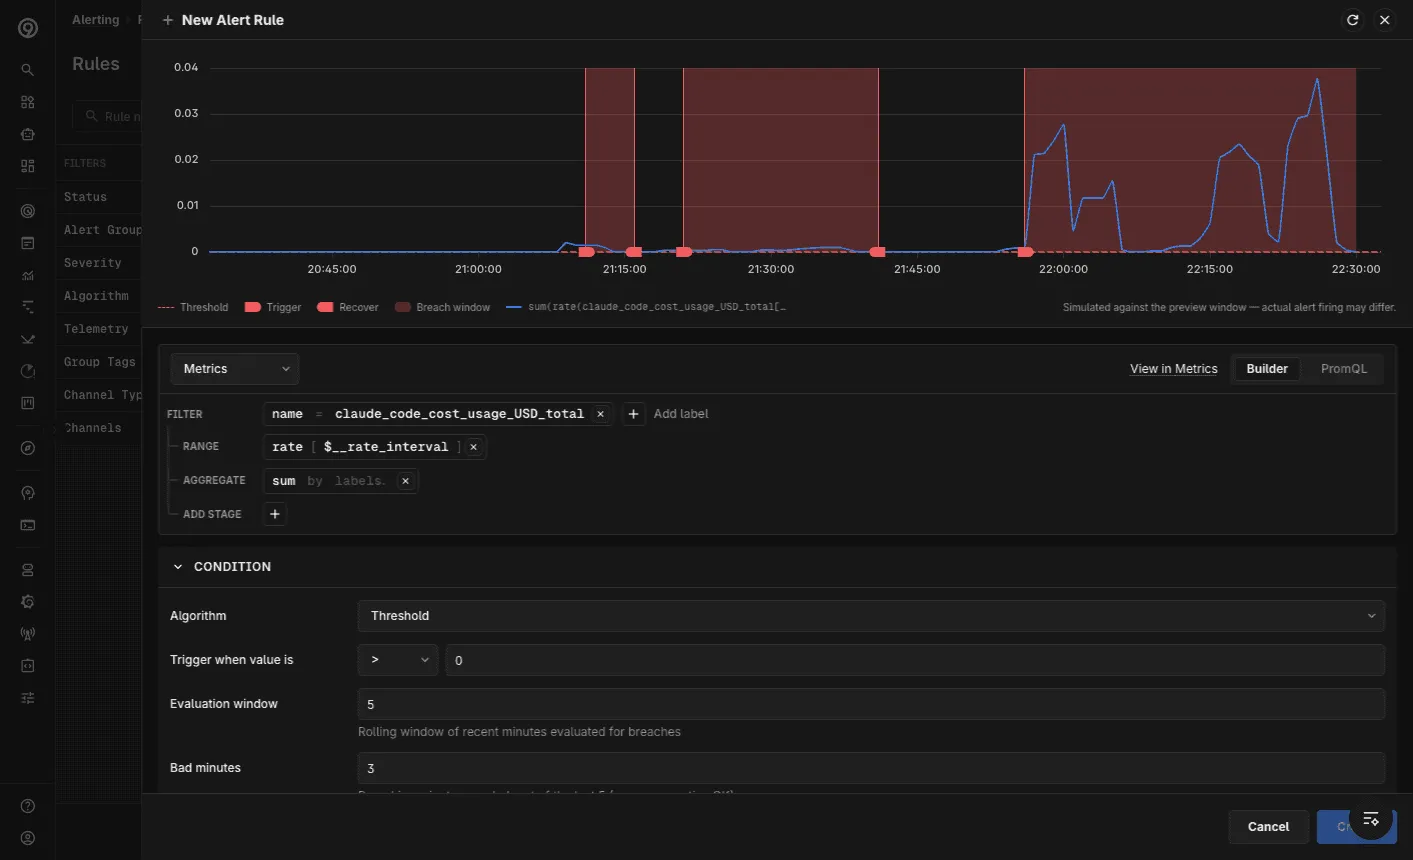
For **metrics**, the [Builder](/docs/metrics-explorer/#builder-mode) composes stages like **Filter**, **Range**, and **Aggregate**; it supports a set of common functions, so for more complex functions or multi-metric queries, use PromQL. For **logs**, the [Builder](/docs/logs-query-builder/) composes a **Filter** and an **Aggregate** stage (count, group-by, timeslice, and unit), and you can choose the log **Index**. Use **View in Metrics** / **View in Logs** to open the query in the corresponding explorer.
### Override Label Filters
For **metrics** rules in **PromQL** mode, if the query uses variables an **Override Label Filters** section appears. The variables and their default operators are inherited from the query; set a value for each, and switch the operator if this rule needs different matching. Operators are `=`, `!=`, `=~`, and `!~`.
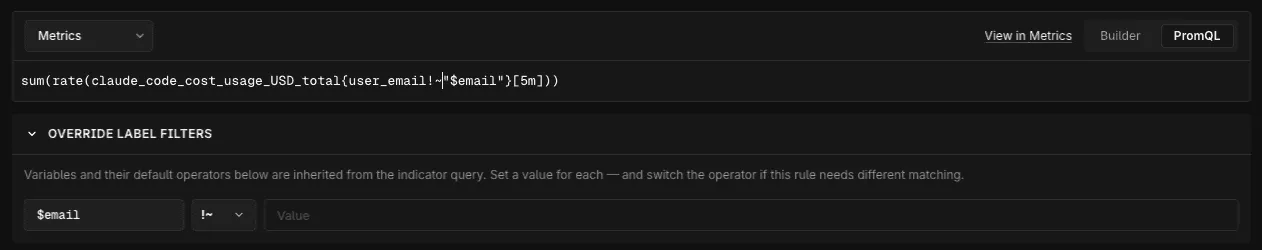
## Condition
The Condition section defines when the rule fires.
### Metrics — Threshold
Select the **Threshold** algorithm to fire on a fixed value:
* **Trigger when value is** — an operator (`>`, `>=`, `<`, …) and a value.
* **Evaluation window** — the rolling window, in minutes, of recent data evaluated for breaches.
* **Bad minutes** — the number of breaching minutes needed within that window before the rule fires. They need not be consecutive.
Requiring several bad minutes within a rolling window filters out momentary spikes.
### Metrics — Adaptive
Select the **Adaptive** algorithm to fire on deviation from a baseline learned from historical data, instead of a fixed threshold:
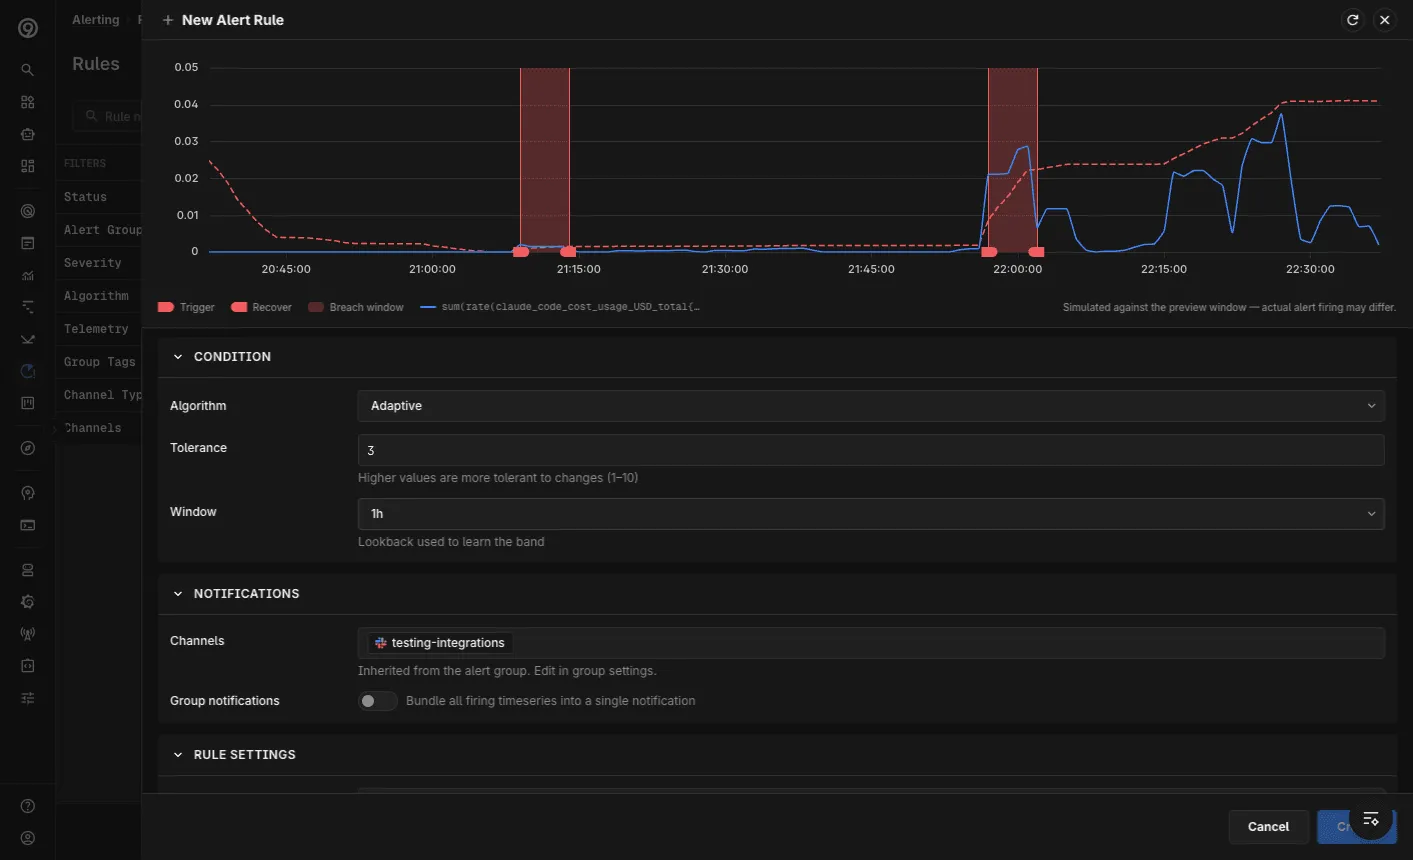
* **Tolerance** — how tolerant the rule is to change, from 1–10. Higher values are more tolerant.
* **Window** — the lookback used to learn the band (for example, `1h`).
The preview renders the learned band so you can see what the rule treats as anomalous. See [Adaptive Alerting](/docs/adaptive-alerting/) for the statistical model.
Deprecated anomaly algorithms
Legacy Anomaly algorithms (high/low spike, level change, and so on) can no longer be selected for **new** rules — use **Adaptive** instead. Existing rules using these algorithms continue to evaluate and can still be edited. See the [Anomaly Algorithms (Legacy)](/docs/anomaly-algorithms/) guide.
### Logs
For log rules, the condition is a **Trigger when value is** operator and value, plus a **Frequency** — how often the rule runs. The frequency is derived automatically from the query’s timeslice.
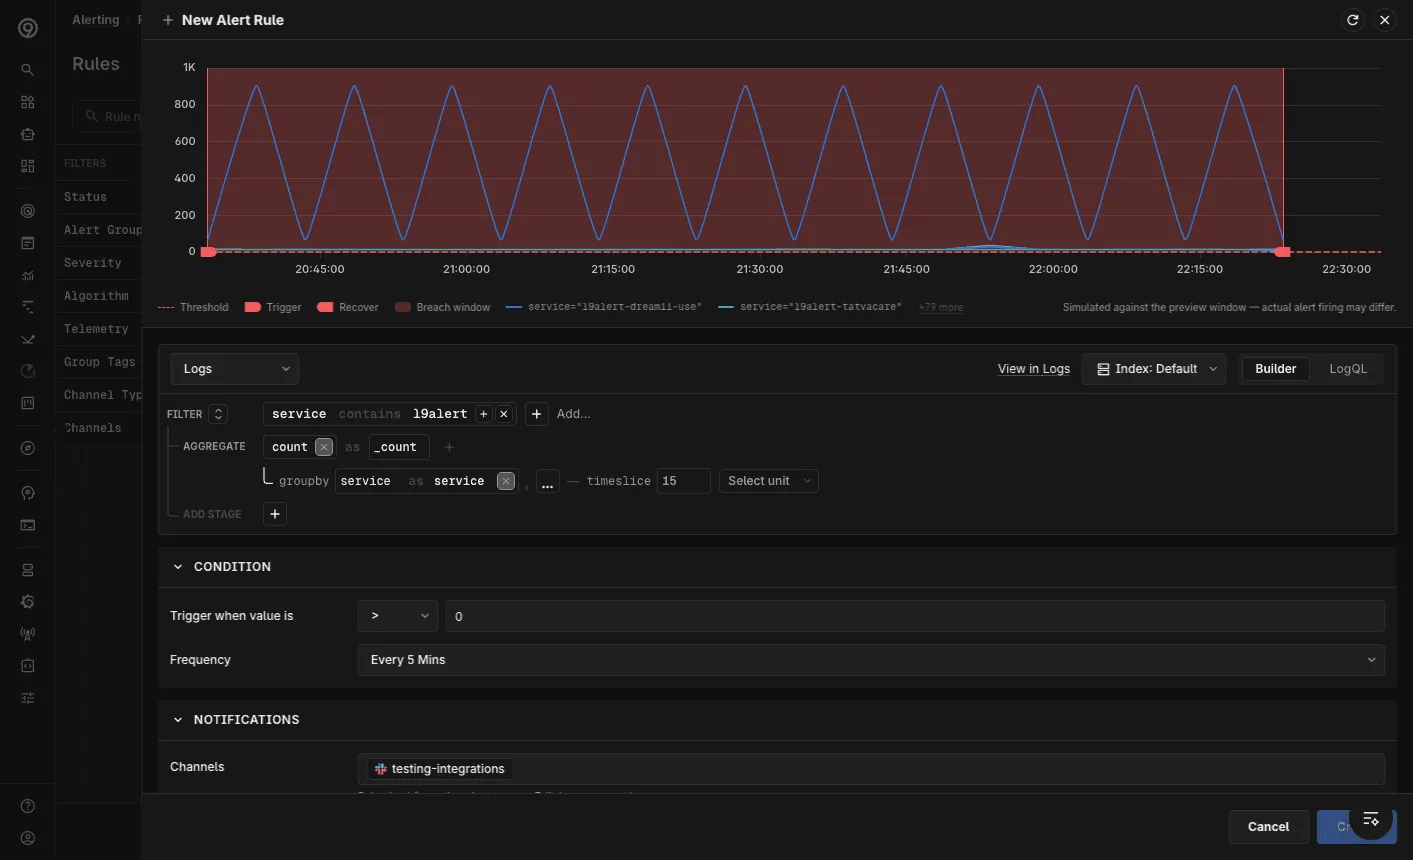
Log rules and Scheduled Search
A log Alert Rule and a [Scheduled Search](/docs/scheduled-search/) map to each other in both directions. Scheduled Search as a standalone surface will be deprecated in favor of log Alert Rules.
## Notifications
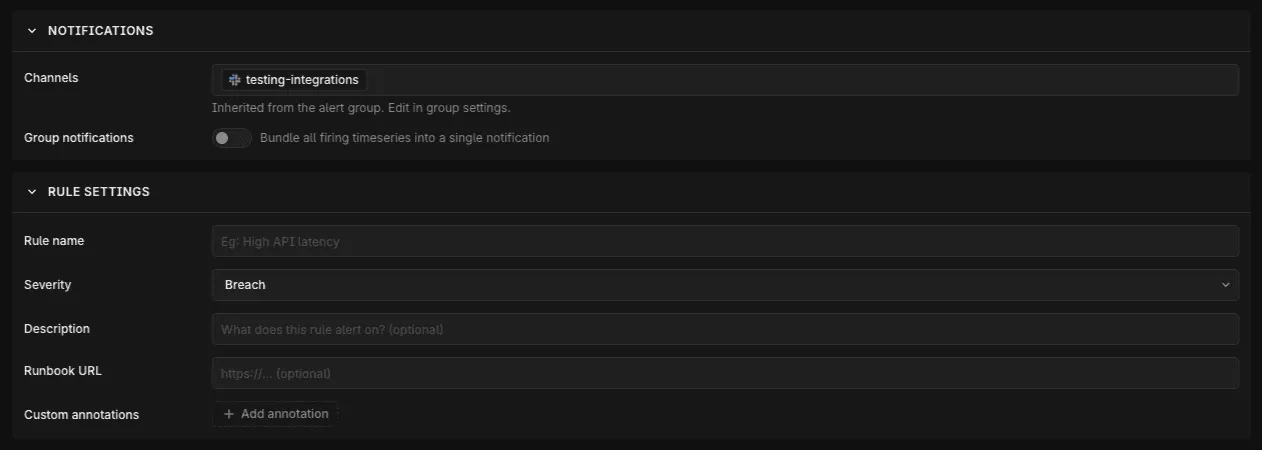
* **Channels** — the [Notification Channels](/docs/notification-channels/) the rule notifies are **inherited from the Alert Group**. Edit them in the [group’s settings](/docs/alert-rules/#alert-groups-view).
* **Group notifications** — enable to bundle all firing timeseries into a single notification instead of one per timeseries. Recommended to avoid noise; grouped notifications call out the count of labelsets and values.
## Rule Settings
* **Rule name** — keep it short and identifiable; the name is shown alongside the Alert Group name in notifications.
* **Severity** — **Breach** or **Threat**. Severity is metadata used by integrations like PagerDuty and Opsgenie to route and prioritize.
* **Description** — what the rule alerts on (optional).
* **Runbook URL** — a link to the runbook for this alert (optional).
* **Custom annotations** — add `key:value` annotations that are sent with every notification.
### Dynamic Annotations
The description, runbook, and custom annotations can include dynamic values using template variables:
* **Labels** — the value of a label on the timeseries under alert: `{{ $labels. }}` or `{{ .Labels. }}`
* **Value** — the worst value of the timeseries under alert: `{{ $value }}` or `{{ .Value }}`
* **Timestamp and time offsets** — the alert’s evaluation timestamp and common lookback windows, useful for building links to dashboards or logs: `{{ $timestamp }}`, `{{ $timestampMilli }}`, `{{ $offset5Min }}`, `{{ $offset15Min }}`, `{{ $offset30Min }}`, `{{ $offset60Min }}` (seconds), and `{{ $offset5MinMilli }}`, `{{ $offset15MinMilli }}`, `{{ $offset30MinMilli }}`, `{{ $offset60MinMilli }}` (milliseconds).
Template variables can be combined with plain text (for example, `Service name is {{ $labels.service }}`), and multiple variables can be used in one field. Spaces in the template syntax are optional.
Considerations:
* **Labels only include what survives the rule’s PromQL aggregation.** If the rule’s expression aggregates with `by (...)` (for example, `avg by (host) (metric)`), only the labels named in `by (...)` are available as `$labels.`. The aggregation drops every other label from the underlying metric, so those aren’t referenceable.
* Apart from the metric’s timeseries labels, the [Alert Group](/docs/alert-rules/#alert-groups-view) labels can also be referenced. If labels match, the metric’s timeseries takes preference.
* If a label value is missing, the template variable is shown as-is.
* If the template syntax is incorrect, the UI displays an error.
* In grouped notifications, *Labels* are shown as a count of all label values and *Values* as a P99 of all the worst values.
* **`$value` is only populated for Static Threshold rules.** For anomaly-detection algorithms (Spike, Trend, Seasonality, and other non-static-threshold rule types), `$value` currently renders as `--`.
#### Sample usage with Splunk
A custom annotation named `splunk_debug_url` with the value `https://search.splunk.com/?service={{ urlquery $labels.service }}&stack={{ urlquery $labels.stack }}` is interpolated per firing timeseries. For example, `service=billing` and `stack=my-org` produce `https://search.splunk.com/?service=billing&stack=my-org`.
#### Encoding template variables inside URLs
When a template variable is used inside a URL, wrap it with `urlquery` to percent-encode the substituted value:
```plaintext
https://app.last9.io/dashboards/my-dashboard?service={{ urlquery $labels.service }}
```
Label values can contain spaces or special characters (for example, `4 service_names`). Without `urlquery`, the value is inserted as-is, producing an invalid URL — and notification channels may then render the annotation as plain text instead of a clickable link. `urlquery` is not needed for plain-text annotations such as descriptions.
## Preview and Save
The live preview at the top of the editor simulates the rule against recent data, marking each **Trigger** and **Recover** point and shading the breach windows, so you can tune the condition before saving. The preview covers only the preview window; actual alert firing may differ.
When you are done, click **Create** (or **Update** when editing). Closing the editor with unsaved changes prompts a discard-changes confirmation. To receive notifications, ensure the rule’s [Alert Group](/docs/alert-rules/#alert-groups-view) has at least one [Notification Channel](/docs/notification-channels/) configured.
***
## Troubleshooting
Please get in touch with us on [Discord](https://discord.com/invite/Q3p2EEucx9) or [Email](mailto:support@last9.io) if you have any questions.
# Creating Dashboards
> Learn how to create custom dashboards with panels, visualization types, and query configurations in Last9

You can create dashboards in Last9 either from scratch or by promoting queries from the Logs and Traces explorers.
## Creating a Dashboard from Scratch
1. Navigate to **Dashboards** in the left sidebar
2. Click **Create Dashboard**
3. Enter a name for your dashboard
4. Click **Add Panel** to add your first visualization
5. Configure the panel query and visualization type (see below)
6. Click **Save** to save the dashboard
## Creating from Service Overview
You can add any performance chart from the [Service Overview](/docs/discover-services/) directly to a dashboard without writing a query. The underlying PromQL is extracted automatically.

1. Navigate to [Discover > Services](https://app.last9.io/service-catalog) and open a service
2. On the **Overview** tab, hover over any chart panel
3. Click the **⋮** menu in the top-right corner of the panel
4. Select **Add to Dashboard**
5. Choose to add to an existing dashboard or create a new one
6. Provide a panel name and click **Save**
The following chart types are supported:
| Chart | Visualization added |
| ----------------------- | ------------------- |
| APDEX Score | Time Series |
| Response Time | Time Series |
| Availability | Time Series |
| Throughput & Error Rate | Time Series |
| Error Distribution | Time Series |
Note
The PromQL query powering each chart is extracted automatically. You can edit the query after the panel is added to the dashboard.
## Creating from Logs or Traces Explorer
You can promote aggregated queries from the Logs Explorer or Traces Explorer directly into dashboard panels.
1. Build an aggregation query in the [Logs Explorer](https://app.last9.io/logs) or [Traces Explorer](https://app.last9.io/traces)
2. Click the **Add to Dashboard** button
3. Choose to create a new dashboard or add to an existing one
4. Provide a descriptive panel name
5. You will be redirected to the dashboard with your query added as a panel
For detailed instructions on building aggregation queries, see:
* [Creating Log Analytics Dashboards](/docs/creating-log-analytics-dashboards-from-logs-explorer/)
* [Creating Trace Analytics Dashboards](/docs/creating-trace-analytics-dashboards-from-traces-explorer/)
## Panels
Panels are the building blocks of a dashboard. Each panel contains a query and a visualization.
### Adding a Panel
1. Open a dashboard and click **Add Panel**
2. Choose a visualization type from the tabs at the top (Time Series, Bar Chart, Doughnut Chart, Gauge Chart, Stat, Table, Heatmap, or Status History)
3. Select a telemetry type (Metrics, Logs, or Traces)
4. Write your query using the appropriate query mode
5. Configure panel options (legend, units, thresholds)
6. Click **Save** to add the panel to your dashboard
### Visualization Types
| Type | Description | Best For |
| ------------------ | --------------------------------------------------------- | ---------------------------------------------- |
| **Time Series** | Line or area charts plotted over time | Monitoring trends, comparing metrics over time |
| **Bar Chart** | Vertical or horizontal bar charts, with optional stacking | Comparing categories, distribution analysis |
| **Doughnut Chart** | Pie/donut chart showing proportions | Percentage breakdowns, resource allocation |
| **Gauge Chart** | Dial indicator showing a single value against a range | Utilization metrics, threshold monitoring |
| **Stat** | Single prominent value display | Key metrics at a glance, counters |
| **Table** | Tabular data with sorting, filtering, and summaries | Detailed breakdowns, top-N analysis |
| **Heatmap** | Color-coded cells showing value density over time | Latency distributions, spotting outliers |
| **Status History** | Discrete state blocks per series over time | Up/down status, pass/fail checks over time |
### Telemetry Types and Query Modes
Each panel supports different query modes depending on the selected telemetry type:
**Metrics** panels use PromQL:
```promql
rate(http_requests_total{service="api"}[5m])
```
**Logs** panels support two modes — **Builder** for visual query construction, and **LogQL** for writing queries directly:
```sql
sum by (severity) (count_over_time({service="api"} [1m]))
```
**Traces** panels use the **Query Builder** with filter and aggregate stages to query span data.
### Query Modes
Each query can run in one of two modes:
| Mode | Description | Use Case |
| ----------- | ----------------------------------------------- | --------------------------------- |
| **Range** | Returns data points over a time range | Timeseries, bar charts, heatmaps |
| **Instant** | Returns a single data point at the current time | Stat panels, gauge panels, tables |
Tip
Use [variables](/docs/using-dashboards/#variables) in your queries to make dashboards dynamic and reusable. For example, `$service` lets users switch between services without editing the query.
Note
**Stat panels show the value at the last evaluated step, not a summary across the time range.**
When a Stat panel runs in Range mode, the displayed value comes from the **final step** of the query result (usually “now” for relative time ranges). A query like `max_over_time(metric[5m])` always reflects activity in the most recent 5 minutes, no matter whether the dashboard time range is set to 1 hour or 7 days — the time range only affects the chart axis, not the value the Stat shows.
To make a Stat reflect the selected time range, aggregate against `[$__range]`:
```promql
sum(avg_over_time(my_metric[$__range]))
```
Pick the aggregator that matches what the Stat should mean: `avg_over_time` for averages, `max_over_time` for peaks, `sum_over_time` for totals. See [Built-in Variables](/docs/using-dashboards/#built-in-variables) for the full list of range and interval variables.
## Panel Configuration
### Chart Settings
These options are available under **Chart Settings** when editing a panel:
* **Unit**: Set the unit format for panel values (see [Units](#units) below)
* **Legend Type**: **Auto** (uses the query name as the legend label) or **Custom** (lets you define your own legend label)
* **Legend Placement**: **Bottom**, **Left**, or **Right**
* **Display Type**: **Line** or **Area** (Time Series panels only)
### Bar Chart Options
* **Orientation**: **Vertical** or **horizontal** bars
* **Stacked**: Enable stacking to show cumulative values
### Table Settings
| Option | Description |
| --------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Transpose** | Swap rows and columns (max 20 columns when transposed) |
| **Density** | **Compact** or **comfortable** row spacing |
| **Summary Footer** | Display a summary row at the bottom |
| **Summary Type** | Aggregation for summary: sum, avg, min, max, first, last, count, p50, p90, p95, p99 |
| **Thresholds** | Color cells based on their values. Set a value, color, and target (**Text** or **Background**). Higher thresholds take precedence. Click **+ Add** for multiple thresholds |
| **Column Visibility** | Show or hide individual table columns |
### Units
Apply unit formatting to panel values. Select from the built-in units or type a custom unit:
| Unit | Format |
| --------------- | ------------------------------------ |
| Bytes (IEC) | KiB, MiB, GiB, TiB (factors of 1024) |
| Bytes (SI) | KB, MB, GB, TB (factors of 1000) |
| Bytes/sec (IEC) | KiB/s, MiB/s, GiB/s |
| Bytes/sec (SI) | KB/s, MB/s, GB/s |
| Nanoseconds | ns precision |
| Milliseconds | ms precision |
| Seconds | s precision |
You can also enter any custom unit (e.g., `requests/s`, `%`, `ops`) by typing directly into the unit field.
## Layout
Panels can be repositioned by dragging the panel header and resized using the handles at the panel edges.
### Sections
Add **Section** dividers to organize panels into named groups. Sections act as visual separators with a label, making it easier to navigate dashboards with many panels. You can drag panels between sections and reposition sections themselves by dragging.
## Links
Links add navigation from a dashboard to another dashboard, a runbook, or any external page. Every link opens in a new tab.
Last9 supports three link surfaces. All three use the same editor.
| Surface | Where you configure it | Where it appears |
| ------------------- | ----------------------------------------- | -------------------------------------- |
| **Dashboard links** | Dashboard **Settings** > **Custom Links** | The dashboard header menu |
| **Panel links** | Panel editor > **Panel Links** | The panel header menu |
| **Data links** | Panel editor > **Data Links** | When you click a data point on a chart |
### Adding a Link
1. Open the **Custom Links**, **Panel Links**, or **Data Links** section
2. Click **Add Link**
3. Enter a **Title** — the text shown in the menu
4. Enter the **URL**
5. Under **Options**, optionally enable **Keep Time Range** and **Include Variables**
6. Save the dashboard or the panel
### Link Types
Dashboard links add a **Type** field with two choices. Panel links and data links are always a single URL.
* **URL**: a single address. The address can contain tokens, as described in [Link Tokens](#link-tokens).
* **Dashboards with tags**: a submenu that lists every other dashboard carrying **all** of the tags you select. The submenu is labelled with those tags. A dashboard gets its tags in **Edit** > **Tags**, and tags are case insensitive. If no dashboard matches, the link does not appear.
### Link Options
| Option | Effect |
| --------------------- | ---------------------------------------------------------------------- |
| **Keep Time Range** | Adds the dashboard time range to the URL as `from` and `to` parameters |
| **Include Variables** | Adds the selected dashboard variable values to the URL as parameters |
Both options skip a parameter that the URL already sets. For example, if the URL ends with `?from=now-1h`, then **Keep Time Range** does not overwrite that value.
For a **Dashboards with tags** link, both options apply to every dashboard the submenu opens.
### Link Tokens
A token is a placeholder that Last9 replaces with a live value. Tokens work in the **Title** field and in the **URL** field. Both `${name}` and `$name` are accepted.
| Token | Resolves to |
| --------------------------- | ------------------------------------------------------------------------------ |
| `${variable}` | A dashboard variable value. Multiple values join with commas |
| `${variable:queryparam}` | The same variable as `var-name=value&var-name=value2` |
| `${__from}`, `${__to}` | The start and the end of the dashboard time range |
| `${__url_time_range}` | The full range as `from=...&to=...` |
| `${__value.raw}` | The value of the data point you clicked |
| `${__value.text}` | The same value, formatted for display |
| `${__value.time}` | The timestamp of the data point you clicked, in milliseconds |
| `${__series.name}` | The name of the series you clicked |
| `${__field.labels.